WiCi One GPU: Maker's RTX 5090 PC Hits 7.27 tok/s, Level With DGX Spark
WiCi One's maker-run InferSSD benchmark has an RTX 5090 test PC level with a DGX Spark on DeepSeek-V4.1-Flash, but its shop claims 20 tok/s with no conditions. No independent LLM test exists yet.
Local AI DeskEdited by Ege Erten
6 min readAI-assisted
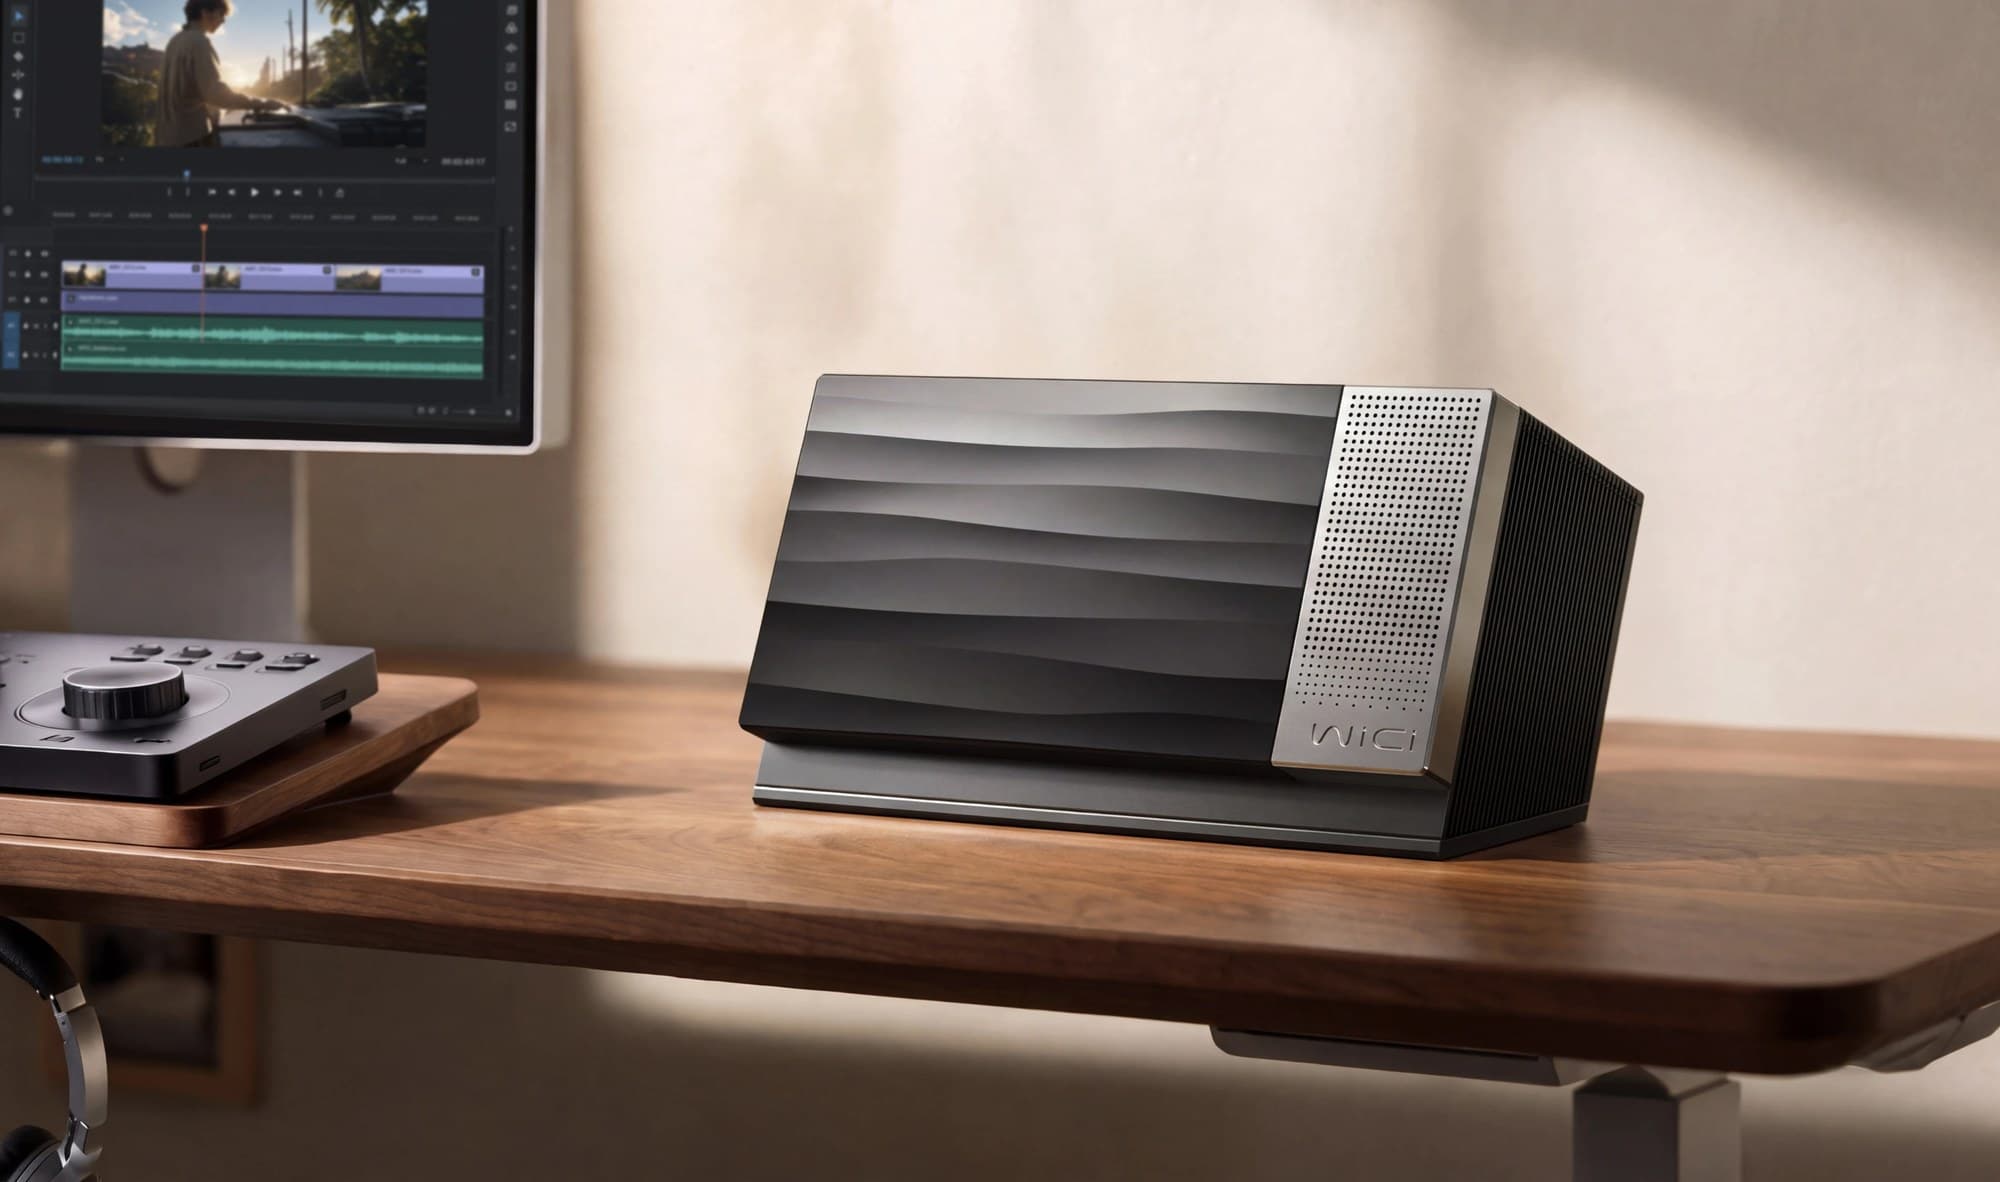
WiCi One in WiCi's own product image. WiCi supplies the picture; the speeds in this story are also WiCi's.
Image: WiCi
Source · Press image from the WiCi product page, used for news reporting.
WiCi, maker of the WiCi One wireless GPU box, puts its RTX 5090 test PC at 7.27 tokens per second (tok/s) decoding DeepSeek-V4.1-Flash-1017 in its own open benchmark, level with NVIDIA's DGX Spark at 7.26 tok/s. The WiCi One shop page claims 20 tok/s for the $9,999 RTX 5090 edition on DeepSeek V4.1 Flash. Those two maker figures were taken under different conditions, and only the first comes with conditions stated.
That gap is what a buyer needs to understand before ordering. The "750B model on 32 GB of VRAM over Wi-Fi" pitch does not come from the radio. It comes from InferSSD, an open-source engine that streams model weights from an SSD, and WiCi's own repository shows that engine running on ordinary PCs, a DGX Spark and a MacBook Pro. No independent outlet or lab has published an LLM speed for a WiCi One. This file sets out what the company states, what its own benchmark shows, and what remains unmeasured.
What WiCi One Is and What It Costs
WiCi One is a box with an NVIDIA RTX GPU, an Intel CPU and an NVMe SSD inside. It plugs into a wall outlet and serves laptops, tablets and phones as a GPU over Wi-Fi 7, with a 4x4 MIMO radio on a 320 MHz channel, according to WiCi's shop and overview pages. Devices reach it three ways: a driver that presents a virtual GPU on macOS, Windows and Linux, an SDK for Python, JavaScript and Swift, or an OpenAI-compatible API. WiCi says the box is bought outright, with no subscription.
The shop lists two editions. The RTX 5060 Ti edition has 16 GB of GDDR7, an Intel Core 3 100U and a 1 TB NVMe 4 SSD for $2,599, and its buy box reads "Ships in 8 weeks". The RTX 5090 edition has 32 GB of GDDR7, an Intel Core Ultra 7 255H and a 4 TB NVMe 5 SSD for $9,999, and the shop gives no separate ship date for it, though its FAQ says orders ship within 8 weeks of purchase. Both pages show a $600-off code applied at checkout, which would bring the 5060 Ti edition to an effective $1,999, the early-access price that Notebookcheck (Sept. 25) and Engadget (Sept. 26) reported. WiCi does not state the system RAM of either retail box.
Gizmodo reported on Oct. 5 that the 5060 Ti box uses a 650 W desktop power supply and the 5090 box a 1,000 W unit. It also reported a Thunderbolt 4 port for running the box as a conventional external GPU. WiCi's own pages list no Thunderbolt port, so that detail rests on Gizmodo's report alone.
What's New: InferSSD Streams Weights From the SSD
The new part is the way a model larger than the GPU's memory gets to run at all. WiCi's overview page says the box runs InferSSD, which keeps the weights on the onboard NVMe and moves the parts in use to the GPU. The shop page calls the same idea "TurboStream weight paging". It works because DeepSeek-V4.1-Flash is a mixture-of-experts (MoE) model: the InferSSD README lists it at 763B parameters in total but only 8B to 16B active per token. According to the InferSSD changelog, it streams the routed experts from the SSD through bounded RAM and VRAM caches, so only the experts a token needs have to sit in fast memory.
InferSSD is public. It is licensed under Apache-2.0, is built on llama.cpp and reads standard GGUF files. Version 0.1.0 shipped on Oct. 30, and version 0.1.1, with Linux CUDA build fixes, followed on Oct. 31. It installs on Apple Silicon Macs and on Linux machines with NVIDIA GPUs, and the README says the first run downloads about 470 GiB of model files. The engine is not tied to WiCi's hardware.
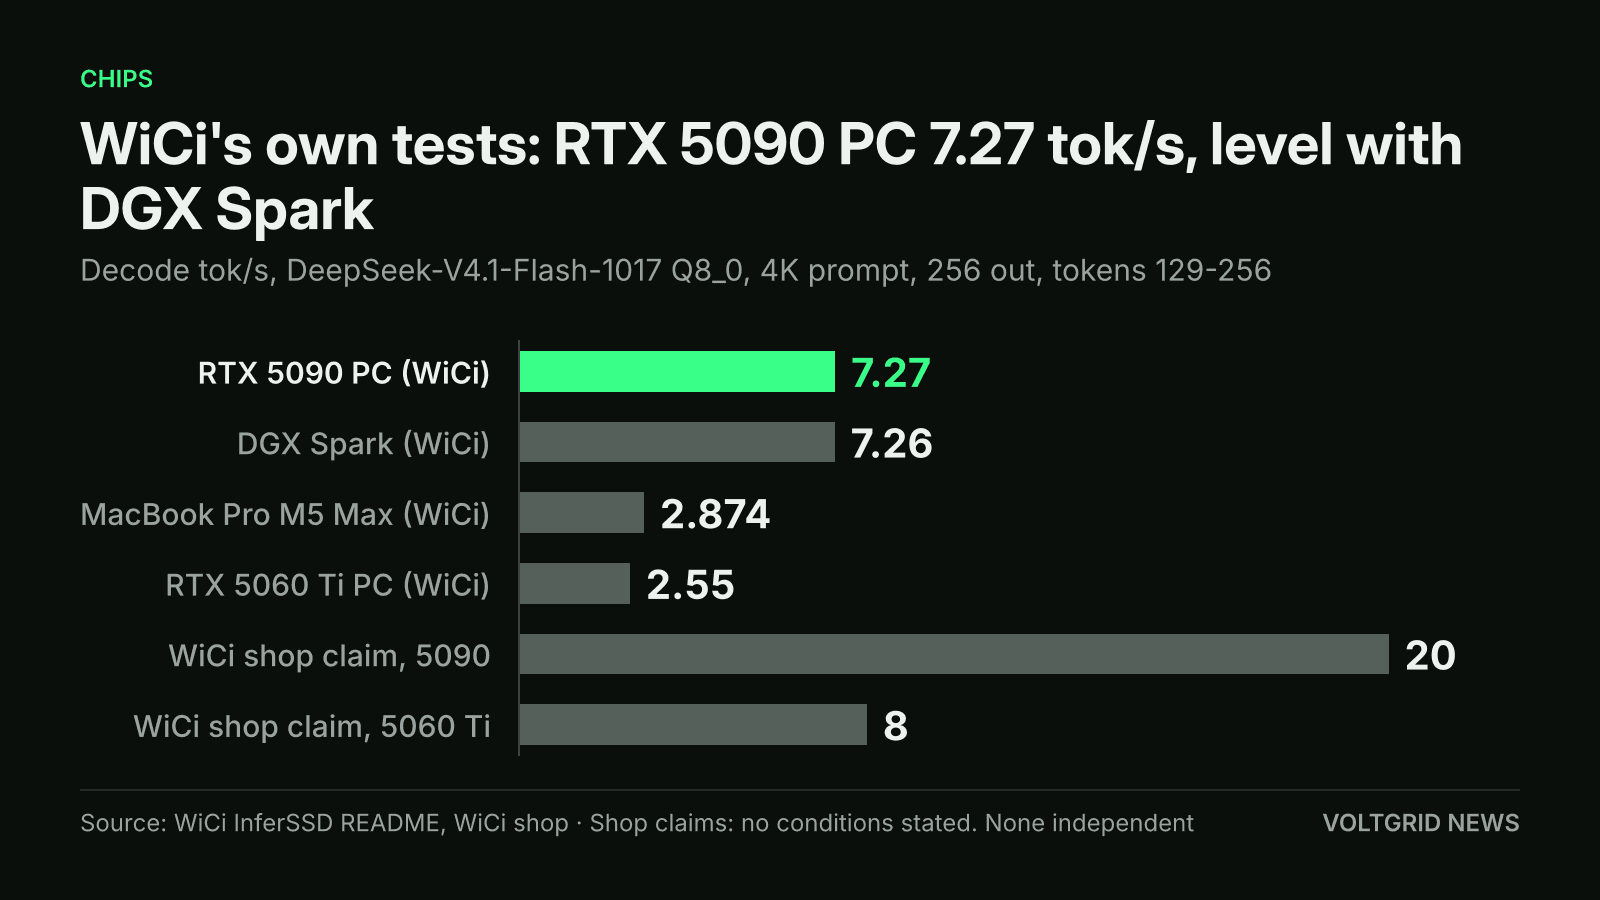
WiCi's own InferSSD tests put the RTX 5090 PC at 7.27 tok/s, level with the DGX Spark's 7.26; the shop's 20 and 8 tok/s are WiCi claims with no conditions stated. None is independent.
Illustration (AI-generated)
The README benchmarks DeepSeek-V4.1-Flash-1017 as a Q8_0 GGUF, with routed experts kept at native 4-bit MXFP4, at a 4K prompt and 256 output tokens, with decode measured over tokens 129 to 256. Under those conditions it lists decode at 7.27 tok/s on the RTX 5090 PC, 7.26 tok/s on a DGX Spark, 2.874 tok/s on a MacBook Pro with an M5 Max and 48 GB, and 2.55 tok/s on the RTX 5060 Ti PC. Prefill runs at 164.5 tok/s on the 5090 PC and 127.5 tok/s on the DGX Spark.
Those test machines are not the boxes WiCi sells. The README's RTX 5090 PC uses an Intel Core Ultra 5 230F, 32 GB of system RAM and a 2 TB PCIe 5.0 SSD, against the retail edition's Core Ultra 7 255H and 4 TB. The RTX 5060 Ti PC shares the retail Core 3 100U but has 8 GB of system RAM and a 2 TB PCIe 4.0 SSD, against 1 TB in the retail box. The README does not mention Wi-Fi or a WiCi One unit: these are local runs on the PCs themselves. The methodology page also says the Linux and NVIDIA rates are tester-supplied summary values.
How WiCi One Compares With the DGX Spark
WiCi's argument is that one box on the home network can serve a large open model to every device in the house without a cloud subscription. Wi-Fi is not what limits the chat case. WiCi's FAQ says models load from the onboard NVMe and are not sent over the air, so a chat request moves a prompt one way and a stream of text tokens back, a small load for a Wi-Fi 7 link. The link matters far more for graphics and games, where frames cross the air. In Gizmodo's Cyberpunk 2077 demo, performance was close to 30% better next to the box than across the room.
The comparison a local-AI buyer should draw is with the DGX Spark. In WiCi's own table, the RTX 5090 test PC and the Spark decode within 0.01 tok/s of each other on the same model, quantization and window. The 5090 edition lists at $9,999. NVIDIA's marketplace listed the 128 GB DGX Spark at $6,950 on Oct. 31, with stock unverified, as covered in our DGX Spark review. The Spark also has 128 GB of unified memory and can run the same open engine. What the WiCi box adds is the wireless serving layer and the RTX GPU for graphics work, not a faster decode on this model by its maker's own numbers.
WiCi One Speed: What Independent Tests Have Not Measured
The largest open question is where the shop's speeds come from. The shop says its LLM figures were taken "over Wi-Fi 7 on a production WiCi One" and gives DeepSeek V4.1 Flash at 20 tok/s on the 5090 edition and 8 tok/s on the 5060 Ti. It states no quantization, context length, prompt size or measurement window. By Voltgrid's arithmetic, the 20 tok/s figure is 2.75 times the 7.27 tok/s in WiCi's open benchmark, and 8 tok/s is 3.14 times the 2.55 tok/s; no source states those ratios. The two sets were measured on different hardware under different or unstated conditions, so the ratio is not a like-for-like gap. WiCi has not explained the difference.
WiCi's materials also disagree on the model's size. The shop says 748B parameters, the InferSSD README says 763B in total, and the description of a sponsored video says 750 billion. The shop also lists Kimi K3, at 2.8 trillion parameters, at 2.5 tok/s on the 5060 Ti edition and 5 tok/s on the 5090 edition. InferSSD 0.1.0 does not list Kimi K3 as a supported model, and WiCi has not published how the Kimi K3 figures were measured. They remain maker claims, although the shop's comparison table calls the 5 tok/s figure measured.
No independent outlet or lab has measured LLM speed on a WiCi One. Gizmodo's Oct. 5 report, "The First 'Wireless GPU' Uses Wi-Fi to Headbutt All Those AI Subscriptions", centred on gaming from a demo with WiCi chief executive Zili Meng. The 5090 unit ran DeepSeek-V4.1 on a short prompt, but Gizmodo reported no speed, and it wrote that the product still needs work before launch. Notebookcheck and Engadget reported the prices and WiCi's own performance claims. NetworkChuck's video of Oct. 30 is marked "Sponsored by WiCi", so it counts as a maker-sponsored demo, not an independent measurement.
When Independent WiCi One Tests Are Expected
The 5060 Ti buy box read "Ships in 8 weeks" on Oct. 31, and Gizmodo reported a December launch plan; eight weeks from Oct. 31 would be late December, by Voltgrid's arithmetic. Independent LLM figures can come only after retail units reach testers. The useful run would put a retail 5090 edition and a DGX Spark through InferSSD on DeepSeek-V4.1-Flash-1017 Q8_0 at the README's settings, once over Wi-Fi and once locally. Until then, every speed quoted for WiCi One is the company's own.
How it compares
Full table| Product | Memory | Bandwidth | AI compute | Measured speed | Price |
|---|---|---|---|---|---|
| HP ZGX Fury AI StationHP | 252 GB HBM3e GPU + 496 GB LPDDR5x CPU (4x 128 GB SOCAMM); 748 GB unified[1] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5x)[1] | — | — | Japan list price from 28,490,000 yen incl. tax (sales from Oct 27, 2026); no US list price published[2] |
| NVIDIA DGX StationNVIDIA (systems built by ASUS, Dell, GIGABYTE, HP, MSI, Supermicro and Exxact) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[3] | GPU HBM3e 7.1 TB/s; CPU LPDDR5X 396 GB/s; NVLink-C2C 900 GB/s between them[3] | 15 PFLOPS FP4 (without sparsity)[3] | Over 26,000 output tokens/s aggregate on Qwen3.6-35B-A3B NVFP4 at 512 concurrent users (24-30-token input, 1,024-token output), Gigabyte W775-V10-L01; idle never below 250 W.[4] | No list price from most OEMs (sales inquiry only); ServeTheHome heard about $100K, up to $120-125K, and unlikely under $80-85K[5] |
| NVIDIA RTX PRO 6000 Blackwell Workstation EditionNVIDIA (sold through PNY, TD SYNNEX and workstation makers) | 96 GB[6] | 1,792 GB/s[6] | 4,000 AI TOPS (FP4, with sparsity) (sparse)[6] | LM Studio: Mistral Small (26 GB) at 42.4 tokens/s vs 17 on an RTX 5090; Gemma 3 27B at 29 vs 5; tied with the RTX 5090 at about 81 tokens/s on DeepSeek Llama 8B Distil, where VRAM does not limit.[7] | $16,000 on NVIDIA's US marketplace (Workstation Edition), listed out of stock[8] |
| Apple Mac Studio (M5 Ultra)Apple | up to 512 GB unified (96 GB on 30-core M5 Ultra; 256 GB or 512 GB on 36-core/80-core M5 Ultra)[9] | 1.2 TB/s[9] | — | Qwen 3.8 27B 4-bit MLX in LM Studio: about 55 tok/s on M5 Ultra (36-core, 256 GB) vs about 40 on M3 Ultra (BGR)[10] | $22,299 minimum with 512 GB ($6,799 36-core CPU/80-core GPU M5 Ultra config plus $15,500 memory upgrade; Oct 28, 2026)[11] |
| NVIDIA RTX Spark (N1X) PCsNVIDIA (MediaTek collaborated on the custom CPU design) | Up to 128 GB LPDDR5X (20-core CPU / 6,144-core GPU version); up to 64 GB (18-core / 5,120-core laptop version)[12] | Up to 300 GB/s: LPDDR5X-9400 on a 256-bit bus (NVIDIA's product page lists no bandwidth)[13] | — | gpt-oss:20b via Ollama in a Codex CLI coding agent, 64K context: 58.5 tok/s generation, 3 of 4 tasks passed (Dell XPS 16, 20-core N1X, 64 GB; StorageReview)[14] | Laptops from $2,599; pricing and configurations vary by region[15] |
| Framework Desktop (Ryzen AI Max+ PRO 495, 192 GB)Framework | 192 GB LPDDR5X-8533 soldered[16] | 273 GB/s (256-bit)[16] | — | — | from $6,799 (DIY Edition pre-order, Oct 30, 2026)[17] |
| Lenovo ThinkStation PGXLenovo | 128 GB LPDDR5X unified (256-bit)[18] | 273 GB/s[18] | — | — | about $4,100 for the 1 TB configuration (Mar 2026)[19] |
| MSI EdgeXpert (MS-C931)MSI | 64 GB or 128 GB LPDDR5x unified (256-bit)[20] | 273 GB/s[20] | 1 PFLOPS FP4 (sparse)[20] | — | No list price; MSI sells via quote (Get a quote)[20] |
| NVIDIA DGX SparkNVIDIA (partner GB10 systems from Acer, ASUS, Dell, GIGABYTE, HP, Lenovo and MSI) | 128 GB; a 64 GB configuration is sold only through OEM partners[21] | 273 GB/s[21] | Up to 1 PFLOP FP4 (theoretical, using the sparsity feature) (sparse)[21] | Qwen 3.8 27B (dense) with multi-token prediction: decode of about 20 tokens/s, with time-to-first-token staying interactive out to the full 262K context.[22] | $6,950.00 (128 GB, 4 TB) on NVIDIA's enterprise marketplace with an Add To Cart button in a copy cached 07:59 UTC on 2026-10-31; stock unverified (listed out of stock on 2026-10-21); 64 GB partner systems from $4,999[23] |
| NVIDIA DGX Spark 64 GBNVIDIA (sold by Acer, ASUS, Dell, Gigabyte, HP and MSI) | 64 GB LPDDR5X unified (two units pool 128 GB over ConnectX-7)[24] | 273 GB/s (256-bit; NVIDIA spec table covers both 64 GB and 128 GB)[21] | 1 PFLOPS FP4 (sparse; NVIDIA spec table covers both memory configurations)[21] | — | from $4,999 (partner systems, Oct 2026; no Founders Edition)[24] |
| AMD Ryzen AI Halo Developer PlatformAMD | 128 GB LPDDR5x-8000 unified[25] | 256 GB/s[25] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL 256/256: 222 tok/s aggregate at batch 64 vs 701 on DGX Spark (StorageReview)[26] | $3,999 with 2 TB SSD (Jul 2026)[26] |
| Framework Desktop (Ryzen AI Max+ 395)Framework | 128 GB LPDDR5x-8000 soldered (32 GB and 64 GB options)[27] | 256 GB/s[28] | — | — | $3,449 (DIY Edition, Max+ 395 with 128 GB, Oct 30, 2026)[17] |
| Acer Veriton GN100 AI Mini WorkstationAcer | 128 GB LPDDR5x coherent unified[29] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.65 tok/s at batch 1 rising to 713.18 tok/s aggregate at batch 64 (StorageReview)[30] | from $3,999 in North America (announced Sep 3, 2025; prices vary by region)[29] |
| ASRock Industrial AI BOX-A395ASRock Industrial | 128 GB LPDDR5X-8000 soldered[31] | — | — | AgentSTH V7, 32 threads: 15% ahead of the next-closest Ryzen AI Max+ 395 box (single-core within 1%); estimated SPEC CPU2026 int rate: top of a 44% spread across four 395 systems; measured by ServeTheHome, Ubuntu 26.04[32] | — |
| ASUS Ascent GX10ASUS | 64 GB or 128 GB LPDDR5X-8533 unified[33] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 70 tok/s at batch 1 rising to 680 tok/s aggregate at batch 64 (StorageReview)[34] | $5,999 (128 GB, 1 TB, GX10-GG0010BN, ASUS eShop US, Oct 30, 2026)[35] |
| Dell Pro Precision with GB10 (model FCM1253; launched as Dell Pro Max with GB10)Dell | 128 GB LPDDR5x up to 8533 MT/s onboard (64 GB option also listed)[36] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 68.57 tok/s at batch 1 rising to 670.83 tok/s aggregate at batch 64 (StorageReview)[37] | $6,593 (128 GB, 2 TB QLC SSD, Dell.com US, Oct 30, 2026)[36] |
| Dell Pro Precision with GB300 (model FCT6263; announced as Dell Pro Max with GB300)Dell | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU[38] | — | — | — | $159,283 (Dell.com US default config with RTX PRO 2000 display GPU and 16 TB SSD, Oct 30, 2026)[38] |
| GIGABYTE AI TOP ATOMGIGABYTE | 128 GB unified system memory[39] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 60.71 tok/s at batch 1 rising to 649.62 tok/s aggregate at batch 64 (StorageReview)[40] | — |
| GMKtec EVO-X2 AI Mini PCGMKtec | 64 GB or 128 GB onboard LPDDR5X-8000 (non-upgradeable)[41] | — | — | — | $3,499.99 (128 GB/1 TB, GMKtec US store, Oct 30, 2026; listed against $3,999.99)[41] |
| HP Z2 Mini G1a WorkstationHP | up to 128 GB unified, up to 96 GB assignable to the GPU, up to 8000 MT/s[42] | — | — | gpt-oss-120b GGUF (63.39 GB, full GPU offload) in LM Studio: close to 40 tok/s (StorageReview)[43] | — |
| HP ZGX Nano AI Station (G1n)HP | 128 GB coherent unified system memory[44] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.6 tok/s at batch 1 rising to 722.9 tok/s aggregate at batch 64 (StorageReview)[45] | — |
| MSI XpertStation WS300MSI (NVIDIA DGX Station platform) | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU (748 GB coherent)[46] | — | — | Noise about 37-40 dBA at lower loads and 46-49 dBA at full load; GPU idle ~148 W (1.3 kW cap), Grace module idle ~78 W (300 W cap), system idle never below 250 W. Measured by ServeTheHome[47] | ServeTheHome calls it a $100K+ system; no MSI list price given[48] |
| Tenstorrent TT-QuietBox 2 (Blackhole)Tenstorrent | 128 GB GDDR6 on the accelerators + 256 GB DDR5-5600 system memory[49] | — | — | — | $9,999 (Oct 30, 2026)[49] |
| WiCi One (RTX 5060 Ti edition)WiCi | 16 GB GDDR7 VRAM; 1 TB NVMe 4 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[50] | — | — | — | $2,599 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout. Early-access price was $1,999 (Notebookcheck, Engadget, Sep 2026)[50] |
| WiCi One (RTX 5090 edition)WiCi | 32 GB GDDR7 VRAM; 4 TB NVMe 5 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[50] | — | — | — | $9,999 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout[50] |
Italic values are reported by an outlet or measured by an independent lab; the rest come from the maker. Measured speeds use different models, quantizations and tools, so read each with its source rather than against the others. Voltgrid News does not test hardware itself.
Sources (50)
- [1] HP
- [2] HP Japan
- [3] NVIDIA
- [4] ServeTheHome
- [5] ServeTheHome
- [6] NVIDIA
- [7] Gamers Nexus
- [8] NVIDIA
- [9] Apple
- [10] BGR
- [11] MacRumors
- [12] NVIDIA
- [13] ServeTheHome
- [14] StorageReview
- [15] NVIDIA
- [16] Framework Blog
- [17] Framework
- [18] Lenovo PSREF
- [19] ServeTheHome
- [20] MSI
- [21] NVIDIA
- [22] Tom's Hardware
- [23] NVIDIA Marketplace
- [24] NVIDIA Blog
- [25] AMD
- [26] StorageReview
- [27] Framework
- [28] Framework Blog
- [29] Acer
- [30] StorageReview
- [31] ServeTheHome
- [32] ServeTheHome
- [33] ASUS
- [34] StorageReview
- [35] ASUS eShop
- [36] Dell
- [37] StorageReview
- [38] Dell
- [39] GIGABYTE (PR Newswire)
- [40] StorageReview
- [41] GMKtec
- [42] HP
- [43] StorageReview
- [44] HP
- [45] StorageReview
- [46] StorageReview
- [47] ServeTheHome
- [48] ServeTheHome
- [49] Tenstorrent
- [50] WiCi
Sources
- 01I Saw a Wireless GPU in Action, and It Needs More WorkGizmodo · gizmodo.com
- 02This external GPU uses Wi-Fi to transform any device into a gaming rigEngadget · engadget.com
- 03InferSSD: Large MoE models, powered by your SSDWiCi (GitHub) · github.com
- 04Buy WiCi OneWiCi · wici.ai
- 05WiCi One, the first wireless eGPU with up to RTX 5090 claims impressive gaming performance and shared compute for multiple devicesNotebookcheck · notebookcheck.net
- 06local AI's biggest problem... they solved it?NetworkChuck (YouTube) · youtube.com