Unsloth Desktop Adds AMD Ryzen AI NPU Support; 35B Model Needs 64GB RAM
Unsloth Desktop's beta now runs models on AMD's XDNA 2 NPUs, AMD says. Its 35B Qwen example needs 64GB of RAM, and Unsloth's 2x to 4x energy-per-token claim is unmeasured.
3 min read
AMD's announcement artwork for Unsloth Desktop's NPU support; the image is promotional art, not a photo of a Ryzen AI chip or system.
Image: AMD
Source · Press image from the AMD newsroom, used for news reporting.
Unsloth Desktop now has AMD Ryzen AI NPU support: it can run language models on the XDNA 2 neural processing units (NPUs) in AMD's Ryzen AI chips, AMD and Unsloth said on Nov. 19, and AMD says its 35-billion-parameter example model needs a PC with 64GB of RAM.
AMD's blog calls XDNA 2 the first NPU the app supports. The work runs through two runtimes, Lemonade and FastFlowLM, and ships in Unsloth's v0.1.920-beta release. Unsloth's guide lists the Ryzen AI 300 (Strix Point and Krackan Point), Ryzen AI Max (Strix Halo) and Ryzen AI 400 (Gorgon Point) families, on Windows 11 or 64-bit Linux. Linux users need kernel 7.0 or newer with the amdxdna driver (older kernels need the amdxdna-dkms package), updated NPU firmware and an unlimited memlock limit. Because Unsloth Desktop exposes an OpenAI-compatible endpoint, AMD says more than 100 agent apps can use the NPU, naming Cline, Open WebUI and VS Code among them.
Memory Decides Which Models Fit on the NPU
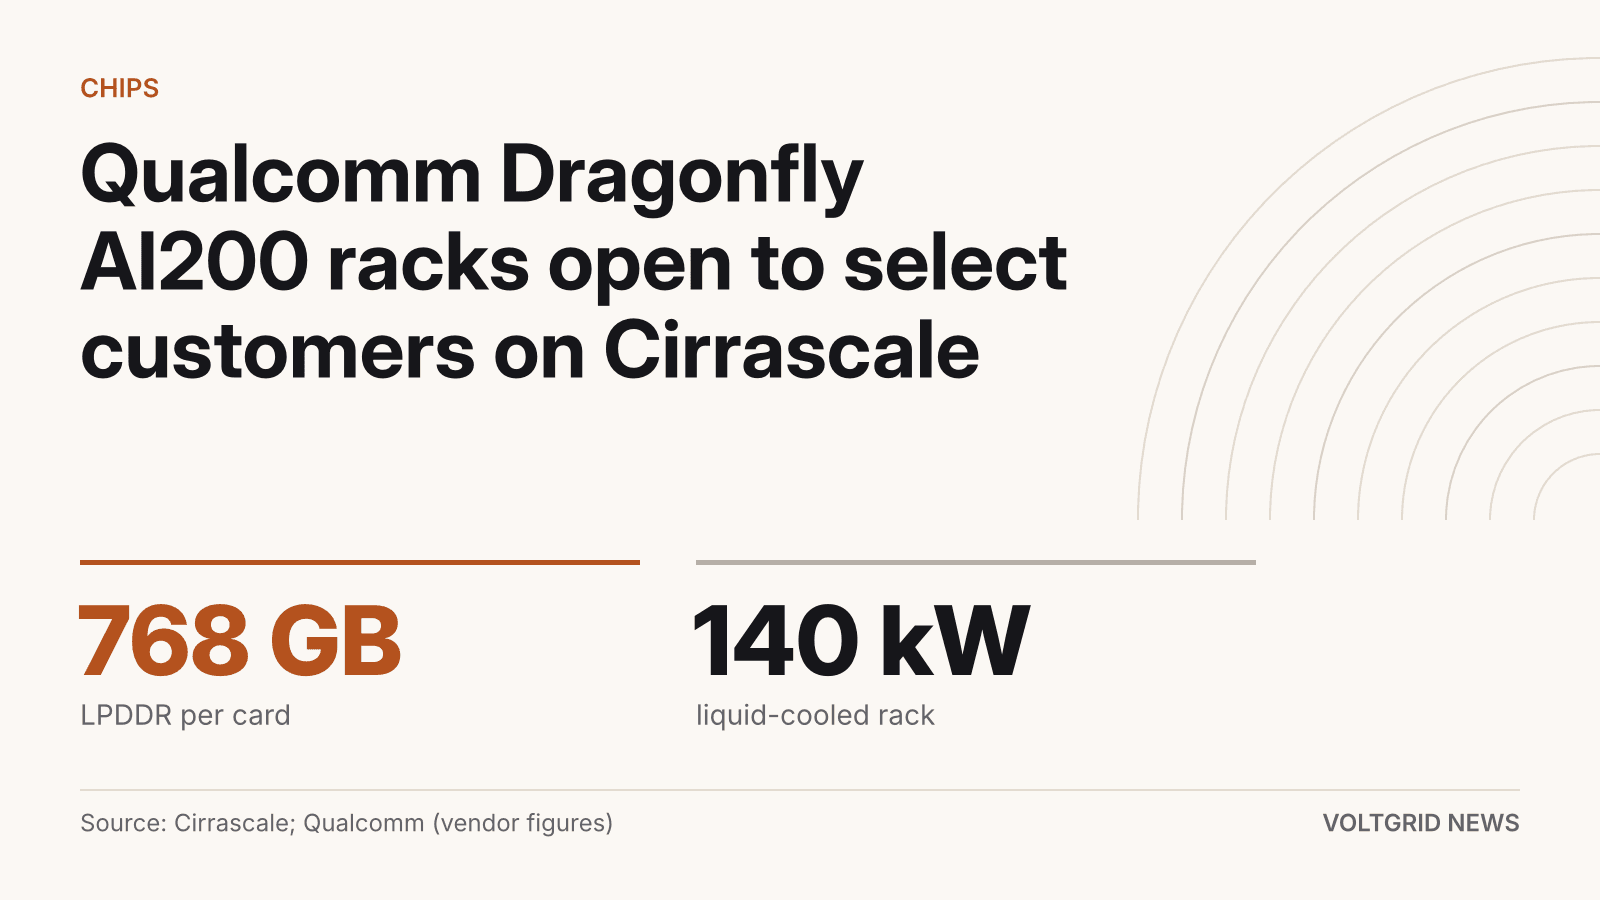
The NPU works from shared system RAM, and by AMD's account Windows shares half of it by default. AMD's own example is Qwen 3.6 35B A3B, a mixture-of-experts model with 35 billion parameters in all. At full context it needs around 28GB available to the NPU, AMD said, so the PC needs 64GB of RAM. Unsloth's table puts the 4-bit file at 20.6 GB; AMD's 28GB figure is for full context, and neither company breaks down the difference. The arithmetic is unforgiving: half of a 48GB laptop is 24GB, short of 28GB. Unsloth recommends 48GB for its 27B Qwen 3.8 model and 32GB for its 9B and 12B models; only the 4B and 1.7B models are listed for 16GB machines.
AMD says the 35B model needs around 28GB for the NPU at full context, so a PC needs 64GB of RAM; the 20.6 GB file size is Unsloth's figure.
Graphic: Voltgrid News
Models must also be in Q4NX, a 4-bit format built for FastFlowLM. The new release adds a converter tab that turns a GGUF file into Q4NX on the CPU, and converted models now load on the NPU, Unsloth said.
Why a 35B Model Can Run on an NPU
Mixture-of-experts models split their weights into many specialist blocks and use only a few for each token. Qwen's model card lists Qwen 3.6 35B A3B at 35 billion parameters in all and 3 billion active per token, across 256 experts. All of it must still sit in memory, which is why the 4-bit file is 20.6 GB in Unsloth's table, but each token reads far less than the full set.
The speed table fits that pattern. Unsloth lists 17.2 tokens per second for the 35B model and 2.0 for Qwen3.8-27B, a smaller model in total, with no test chip named for either. Those are Unsloth's figures, so they show a trend in its own table and not a measured ranking.
Unsloth's Efficiency and Speed Figures Are Unmeasured
The pitch is energy. Unsloth's changelog says NPUs are 2x to 4x more efficient per joule per token than GPUs, and AMD says moving inference to the NPU can help battery life while leaving the CPU and GPU free. Unsloth's changelog and guide name no GPU, models or method behind that range, and no independent lab has measured it yet.
The same holds for speed. Unsloth's guide lists 17.2 tokens per second and a 3.13-second time to first token for the 35B model, 9.5 tokens per second for a 9B Qwen model and 40.7 for a 1.7B model. These are Unsloth's figures. The table does not name the chip they were run on, the memory, the context length or which of FastFlowLM's four power modes was used; the default is Performance. A Strix Halo with 128GB and a 16GB Ryzen AI 300 laptop are very different machines.
Independent numbers so far cover only the GPU path on the Ryzen AI Halo's Strix Halo chip, not the NPU. In our roundup of Ryzen AI Halo reviews, StorageReview and Tom's Hardware measured it well behind NVIDIA's GB10 boxes, and AMD's ROCm 10.2 notes flagged WSL2 AI failures on Strix Halo, as we reported on Nov. 19. Nothing in those results speaks to the NPU.
What Is Not Confirmed Yet
Three things are open: which chip produced Unsloth's speed table, what the 2x to 4x energy range was measured against, and how tokens per watt on the NPU compare with the integrated Radeon GPU on the same laptop under the same model. Until a reviewer measures wall power and throughput on a named Ryzen AI system, the speed and energy figures remain vendor claims. The software is also a beta, and Unsloth says loading self-converted models straight from the NPU model list is not supported yet.
Sources
- Published
- Sources
- 3 cited