AMD Lux Opens at Oak Ridge: 4,000+ MI355X GPUs, 3.5M Node-Hours a Year
AMD's Lux at Oak Ridge opened Nov. 16 with 4,000+ MI355X GPUs; half of its 3.5M node-hours a year go to the Genesis Mission, half to AMD and paid users. No power figure yet.
3 min read
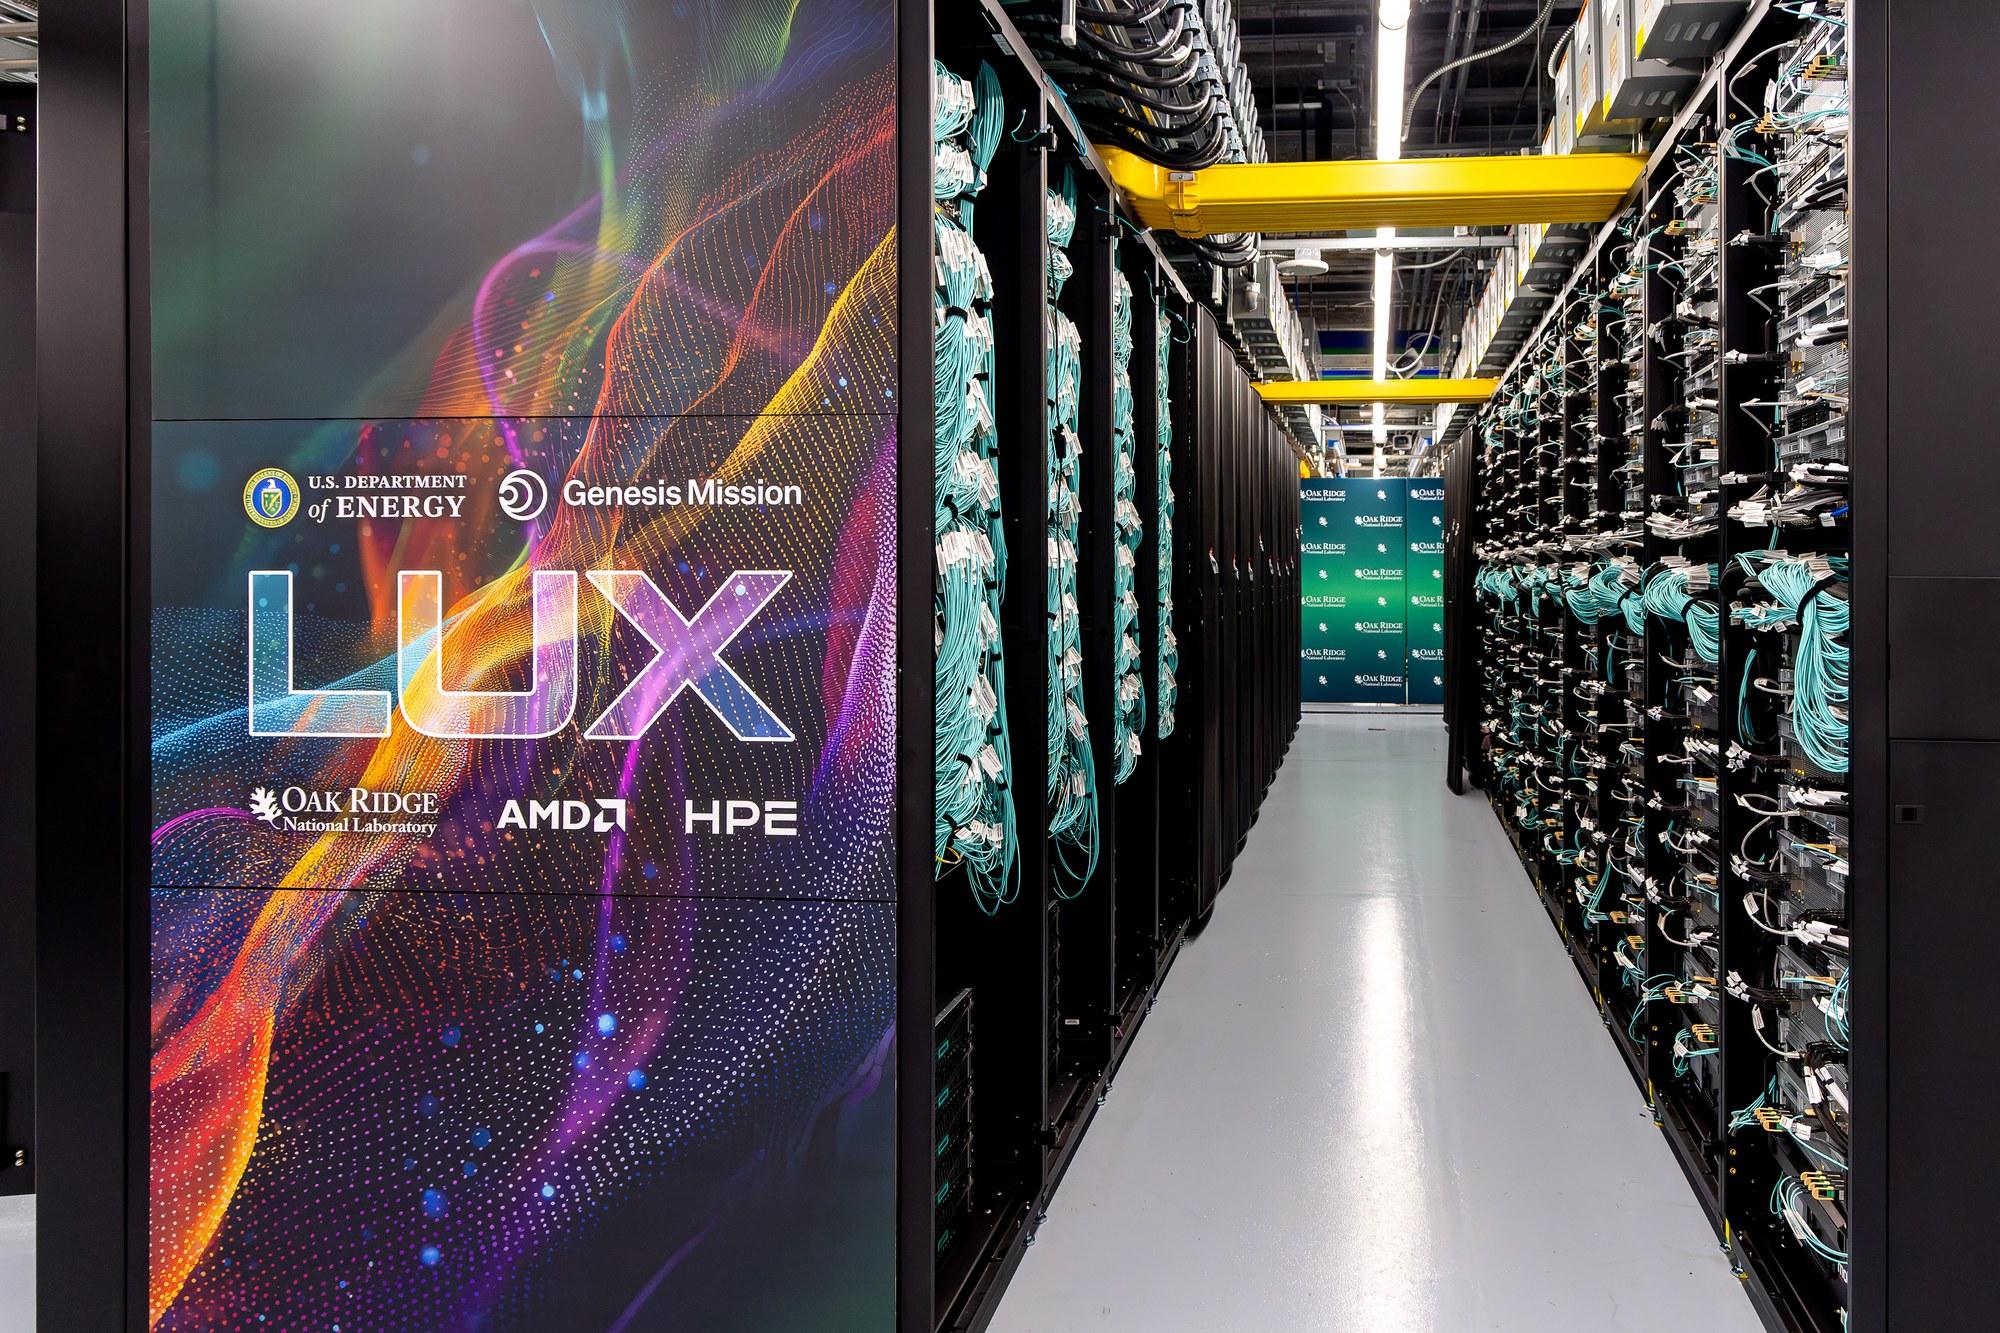
The Lux supercomputer at Oak Ridge National Laboratory, built with AMD Instinct MI355X GPUs in HPE nodes.
Image: AMD
Source · Press image from the AMD newsroom, used for news reporting.
AMD and Oak Ridge National Laboratory (ORNL) opened the Lux supercomputer to scientific users on Nov. 16, with more than 4,000 Instinct MI355X GPUs in more than 500 HPE ProLiant Compute XD685 nodes, according to the lab and AMD. The system debuted at No. 14 on the 68th TOP500 list with an HPL (FP64) Rmax of 220.79 petaflops, a submitted result.
AMD, which announced the opening in a press release, calls Lux the first dedicated U.S. AI factory for the Department of Energy's (DOE) Genesis Mission, the DOE-led AI-for-science program. ORNL, which operates the machine on DOE's behalf, describes it as the first major addition to DOE computing infrastructure for that mission. Neither source gives a power draw or a price for Lux.
How the time is split
The more telling number is the allocation. ORNL says about half of Lux's 3.5 million node-hours a year go to the Genesis Mission and the other half to AMD, under a co-investment model in which DOE and AMD share infrastructure and operating costs. On the lab's resource page the second half is paid access for public and private partners at the DOE user-facility rate. AMD uses part of it for development and testing.
ORNL says about half of Lux's 3.5 million node-hours a year go to the Genesis Mission; the rest goes to AMD and paid partners.
Graphic: Voltgrid News
By our arithmetic, and assuming use is spread evenly through the year, 3.5 million node-hours is about 400 nodes running every hour of the year, out of more than 500 installed. The lab says full-system jobs may be limited to fewer than 4,000 GPUs, because some nodes are set aside for persistent services.
What the hardware offers
OLCF lists 288 GB of HBM3E memory per GPU at 8 TB/s, 1.1 PB of HBM across the system, a 400G Ultra Ethernet NIC per GPU and more than 24 TB of NVMe flash per node. Its system page gives 317 petaflops of FP64 for modeling and simulation, 20 exaflops of FP8 for AI training and 40 exaflops of FP4 for inference; OLCF does not say whether the FP8 and FP4 figures are dense or sparse. Those are peak figures from the lab's specification page, not measured results.
Lux runs both Slurm and Kubernetes for scheduling, so one machine can serve batch simulation and cloud-style AI services. It has access to Orion, OLCF's Lustre file system with more than 600 PB, and runs under DOE Moderate security controls, the level used for Frontier, which allow export-controlled applications and data.
Why Lux Posts Two Different Speeds
The TOP500 ranks machines on High-Performance Linpack, which solves dense equations in 64-bit floating point (FP64). Lux's measured result was 220.79 petaflops, against a theoretical peak of 323.90 petaflops, TOP500 lists. The lab's AI figures are different peaks: 20 exaflops at FP8 and 40 exaflops at FP4, which are lower-precision formats that fit more math into each clock cycle. OLCF puts each MI355X at 5 petaflops of FP8 and 78 teraflops of FP64.
No list tested the AI peaks, so the 220.79 petaflops says little about training or inference speed. Power ties both to the data center, and Lux has not submitted a figure, so its efficiency and its grid draw stay unknown.
Who gets it and what comes next
The first Genesis projects named for Lux cover AI-assisted fusion power plant design, a foundation-model factory for materials and manufacturing, and river and water-availability forecasts for the Tennessee Valley Authority region. Partners buy node-hours in blocks of at least 175,000 per six months. The lab's example is a 400-node job of 3,200 GPUs for 18 days, spread over six months, so eight GPUs per node.
For data-center planners the open question is power. As Voltgrid reported on the Nov. 16 list, Lux was among the entries that submitted no power figure, so Lux has no Green500 efficiency reading yet. StorageReview reported in July that funded projects were expected to start on Lux in October 2026; the formal opening came on Nov. 16. The next machine, Discovery, with MI430X GPUs, is due at ORNL in 2028. Oak Ridge and AMD are also partners with IBM in a separate quantum error correction platform.
What is not confirmed yet
Lux's power draw, its energy efficiency and the size of the DOE and AMD investments were not given in the release or in the ORNL post. The TOP500 result is a submitted run, not an independent test. "First AI factory" is AMD's description, and the lab's own wording is narrower.
Sources
- 01Lux SI+HPC Supercomputer Debuts in the Top500, Advances Genesis Mission GoalsOak Ridge Leadership Computing Facilityolcf.ornl.gov
- 02AMD's Lux Becomes the First Genesis Mission Supercomputer, With Discovery to Follow in 2028StorageReviewstoragereview.com
- 03AMD-Powered Lux Supercomputer Opens to Scientific Users at Oak Ridge, Becoming First AI Factory for DOE’s Genesis MissionAMD · press releasesir.amd.com
- Published
- Sources
- 3 cited