Apple Mac Studio M5 Ultra Review: 256GB Units Measured, 512GB Due Dec. 3
MacStories, BGR and Tom's Hardware measured the 256GB M5 Ultra well ahead of the M3 Ultra and DGX Spark for local LLMs. The $22,299 512GB model, due Dec. 3, has not been measured by anyone.
Local AI DeskEdited by Ege Erten
8 min readAI-assisted
Follows our story: Mac Studio M5 Ultra 512GB Opens for Orders at $22,299
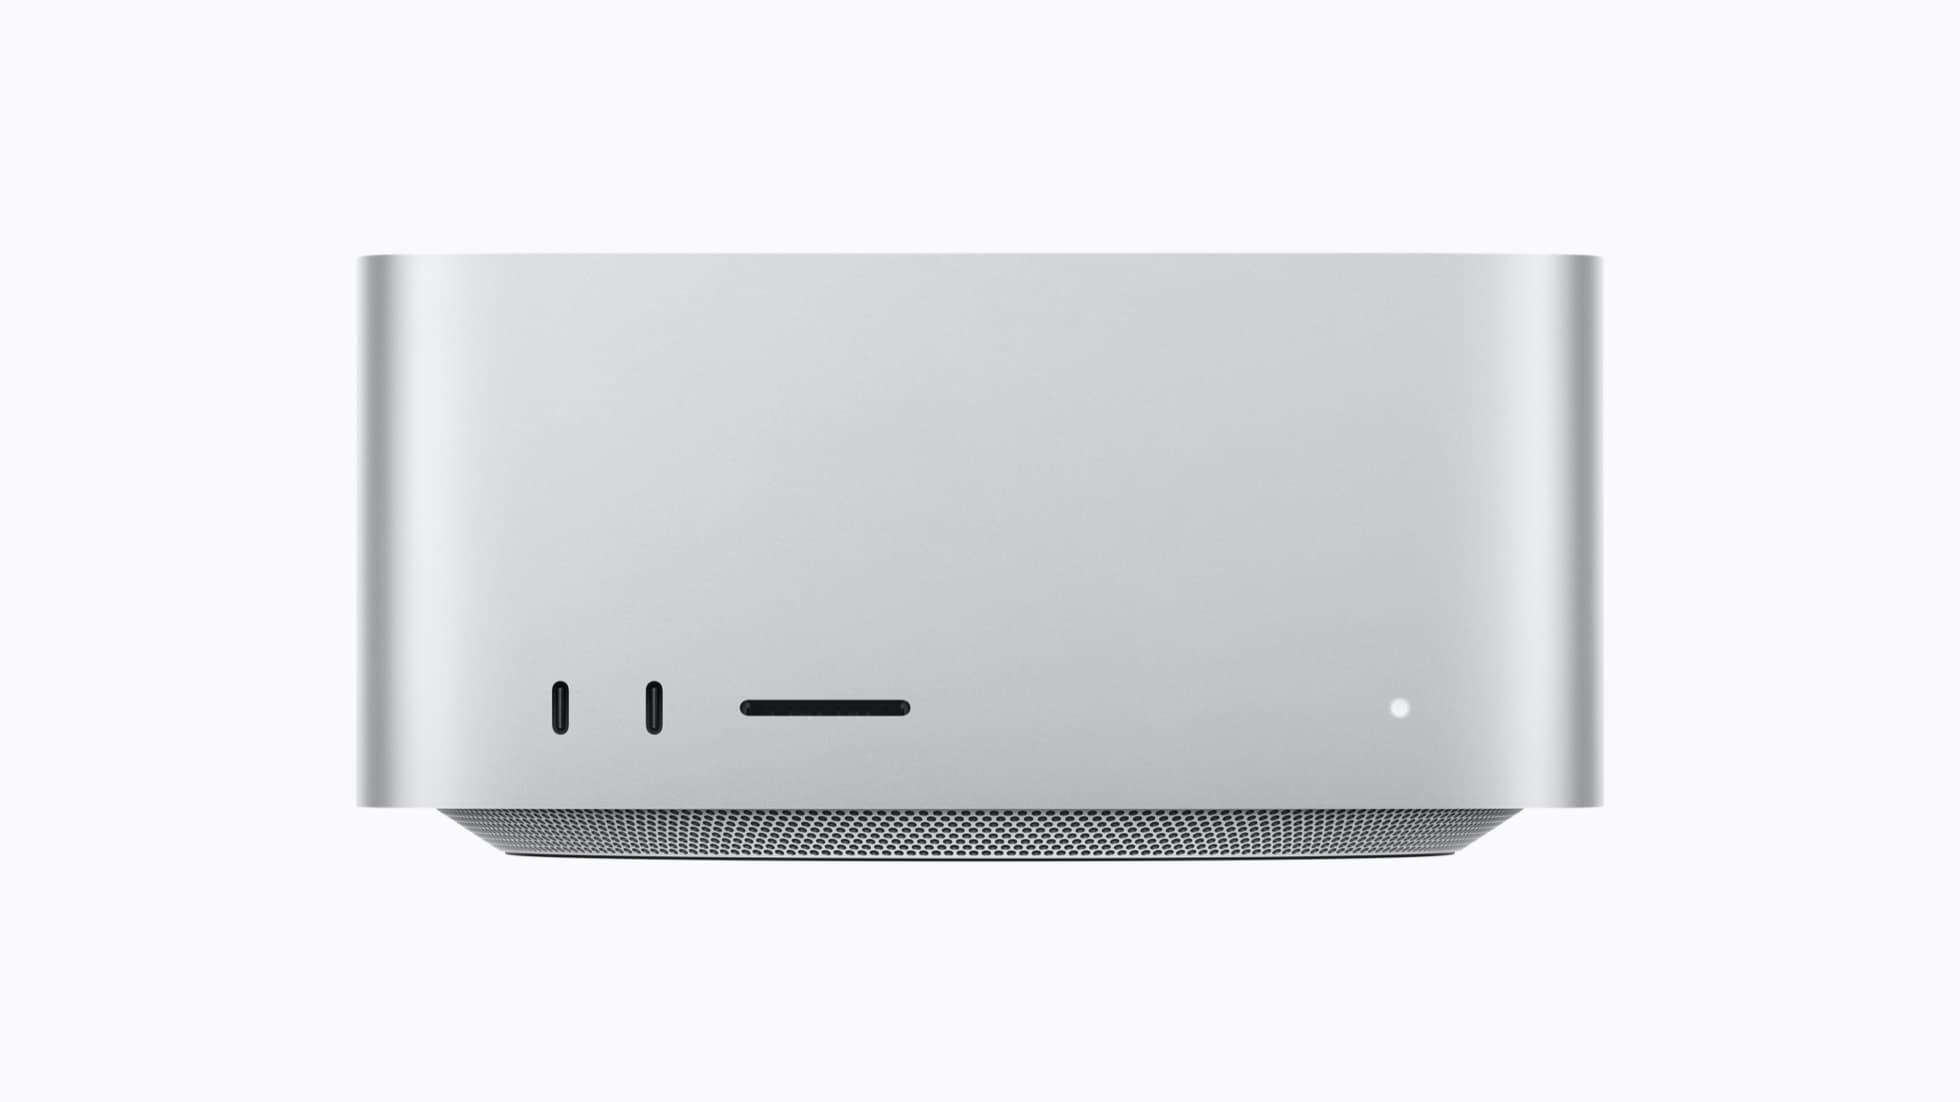
Apple's Mac Studio, the desktop that now offers the M5 Ultra with up to 512 GB of unified memory.
Image: Apple
Source · Press image from the Apple Newsroom, used for news reporting.
Apple's Mac Studio M5 Ultra pairs up to 512 GB of unified memory with 1.2 TB/s of bandwidth, and every independent measurement so far comes from 256 GB units. MacStories, BGR and Tom's Hardware all reviewed the 36-core CPU, 80-core GPU version with 256 GB, and found it far faster than the M3 Ultra for local language models. The 512 GB model, which opened for orders on Oct. 28 from $22,299, has not been measured by anyone. Digital Trends reports that the first of those orders arrive on Dec. 3.
That gap matters, because the 512 GB tier is the reason many local-AI buyers look at this machine. As Voltgrid reported when the 512 GB option opened for orders, it is a $15,500 memory upgrade on the $6,799 top chip. This review sets Apple's specifications against what the three outlets measured on their 256 GB units. Voltgrid did not test the machine, and nothing here should be read as a result for the 512 GB configuration.
What Is New in the M5 Ultra Mac Studio
The chip is the change. Tom's Hardware and BGR describe the M5 Ultra as Apple's first four-die design: two dual-die M5 Max chips joined over UltraFusion, which Apple says moves more than 4.4 TB/s between the dies. Apple's spec page lists the base M5 Ultra with a 30-core CPU of 10 super cores and 20 performance cores, a 64-core GPU and a 32-core Neural Engine. The upgraded chip has a 36-core CPU and an 80-core GPU. Apple's spec page lists a Neural Accelerator in each GPU core.
Memory bandwidth is the change that matters most for models. Apple lists 1.2 TB/s for both M5 Ultra versions. BGR reports Apple's claim that this is 50% above the M3 Ultra's roughly 819 GB/s. Capacity has not grown past the old ceiling: the base M5 Ultra has 96 GB, and only the 36-core, 80-core chip can be configured with 256 GB or 512 GB, Apple's spec sheet says.
The box itself is unchanged in shape, at 9.5 cm tall and 19.7 cm square, but the M5 Ultra version weighs 3.6 kg. Tom's Hardware attributes the extra 2 pounds over the M5 Max model to a copper fin stack and vapor chamber. Apple lists a maximum continuous power of 480 W. The M5 Ultra model gets Thunderbolt 5 on its two front ports as well as its four rear ones, plus 10 Gb Ethernet. BGR reports Apple's claim that four Mac Studios linked over Thunderbolt 5 with RDMA deliver up to three times the inference performance of one unit; no outlet has tested that.
The price has moved too. The cheapest M5 Ultra costs $5,499 with 96 GB and 1 TB, and the 36-core chip adds $1,300, Tom's Hardware lists. Going from 96 GB to 256 GB adds $4,000. Digital Trends reports that a fully loaded machine with 512 GB and 16 TB now costs $29,799, against an $18,299 maximum when the line launched in August.
What the Mac Studio M5 Ultra Solves
The first problem it removes is fit without a cloud bill. MacStories ran Qwen3.8-Flash-Next at 4-bit (oQ4e, in oMLX 0.7.0.dev2 on macOS 27.0) with a peak process footprint of 155 GB, and the 5-bit build at 179 GB, both entirely in memory on the 256 GB unit. A 32 GB RTX 5090 cannot hold a model that size and would have to spill into system memory over PCIe. MacStories measured what spilling costs, but on a different model and quantization (Qwen3.8-27B, Q4_K_M GGUF): the 5090 fell to 1.5 tok/s at 256K context once it borrowed system RAM. That shows the penalty of spilling, not what Flash-Next would do on a 5090.
The second is long agent sessions that stay usable. On the same Flash-Next build, MacStories measured the M5 Ultra reading a 16K-token prompt at 2,887 tok/s against 1,143 on a 512 GB M3 Ultra, with the first token at 5.6 seconds instead of 13.9. A 256K-token prompt took about 104 seconds to the first token, against 246 on the M3 Ultra, per MacStories' timing table (its text says 102 and 245). Writing speed after 256K tokens of context was 74.7 tok/s, against 38.6.
The third is serving several requests from one box. With three Flash-Next requests of about 6,500 tokens at once, MacStories measured 81.5 tok/s of combined output, up from 66.2 for a single request. The M3 Ultra stayed near 39 to 40 either way.
Mac Studio M5 Ultra Pros and Cons
The reviews agree on direction, not on size; the numbers differ by tool, model and prompt, and Tom's Hardware compared against the M4 Max and DGX Spark rather than the M3 Ultra. BGR, mostly in LM Studio, measured about 55 tok/s on a 4-bit MLX build of Qwen 3.8 27B against about 40 on the M3 Ultra, and about 80 against 60 on Qwen 3.5 122B A10B (quantization not stated). It put the average gain at 30% to 40%, and found first tokens arriving in about half a second instead of over one. MacStories, in oMLX with a 6,091-token prompt, measured 48 tok/s on Qwen3.8-27B against 31 on the M3 Ultra. Those are different runtimes, models and prompts, so neither figure supersedes the other.
Tom's Hardware ran Qwen 3.8-27B at Q4_K_M, a dense model whose speed depends heavily on memory bandwidth. It found the M5 Ultra's prompt processing faster than NVIDIA's DGX Spark and its token generation double the M4 Max and almost four times the Spark. Tom's published the exact rates only in chart images.
The RTX 5090 comparison is MacStories' matched test. On the 6,091-token prompt, the 5090 PC read at 3,031 tok/s and wrote at 59; the M5 Ultra read at 1,701 and wrote at 48. The Macs ran MLX oQ4e and the PC ran GGUF Q4_K_M, so MacStories frames it as a system comparison rather than a chip one. At 256K context the 5090 still led, 30.0 tok/s against 24.3, but only with an 8-bit attention cache that let the prompt fit in 32 GB.
The memory limits are MacStories' too. On its 256 GB unit, macOS ended the 6-bit Flash-Next load at 176.6 GB, and oMLX refused the 8-bit build, projecting 244.2 GB against the 200.4 GB it allows. Both ran only with their embedding tables offloaded to the SSD. GLM-5.3-Flash produced no answer on a 256K-token prompt, which ran out of memory, and a repeat of its 128K prompt also ran out of memory. These are exactly the cases the 512 GB model is sold to fix, and no one has yet shown that it does. Tom's Hardware notes the memory is soldered and Apple sells no replacement SSDs, so capacity is fixed at purchase.
Who the Mac Studio M5 Ultra Is For
It fits a developer or tinkerer running agents on open models in the 100 GB to 180 GB range at 4-bit or 5-bit, who wants long contexts and quiet operation. MacStories said it could not hear the fan with Flash-Next running unless it put an ear to the top of the machine. BGR put the 256 GB configuration at $10,799, which matches Tom's Hardware's price list with a 1 TB SSD; Tom's tested it with 4 TB at $12,299.
It also fits a small team that wants one box to serve a few concurrent sessions of a mid-sized model, where MacStories' three-request test showed total output rising rather than falling.
It does not fit a buyer whose model fits in 32 GB and who wants the fastest single-user decode: MacStories' RTX 5090 PC was faster on both reading and writing. It is also not yet a proven buy for anyone who needs the 512 GB tier to hold a model at 8-bit. That case has no independent measurement.
Why Memory Bandwidth Sets Local Model Speed
A language model writes each word by reading its weights out of memory, so the speed of that memory, its bandwidth, limits how fast a large model can write, while its capacity decides whether the model fits at all. Apple lists 1.2 TB/s for the M5 Ultra and up to 512 GB. NVIDIA lists 273 GB/s and 128 GB for the DGX Spark, and 1,792 GB/s and 96 GB for the RTX PRO 6000 Blackwell.
The two numbers trade off. The RTX PRO 6000 moves data fastest but holds the least, and the Spark holds more than the card but moves data slowest. The Mac Studio sits between them on speed and above both on capacity. That is why the open 512 GB question matters: capacity buys models that fit, and no one has yet measured how fast they run.
How It Compares With DGX Spark, RTX PRO 6000 and DGX Station
Against NVIDIA's DGX Spark, the Mac wins on bandwidth and capacity and loses on price at the 256 GB and 512 GB tiers; the $5,499 base M5 Ultra undercuts the Spark's $6,950 list but has only 96 GB. The Spark has 128 GB at 273 GB/s and lists at $6,950 for the 128 GB, 4 TB unit on NVIDIA's marketplace, with stock unverified. In our DGX Spark review, 273 GB/s is the figure that caps dense models. Tom's Hardware's near-4x generation gap on a dense 27B model, read from chart images with the Spark's settings not shown, points the same way. The Spark keeps CUDA and its 200 Gbps clustering.
NVIDIA's RTX PRO 6000 Blackwell is the bandwidth rival: 96 GB of GDDR7 at 1,792 GB/s, at $16,000 on NVIDIA's marketplace, where it is listed out of stock. It needs a host PC and draws up to 600 W as a board. No outlet has run it and the M5 Ultra on the same model, quantization and tool, so there is no measured speed comparison yet.
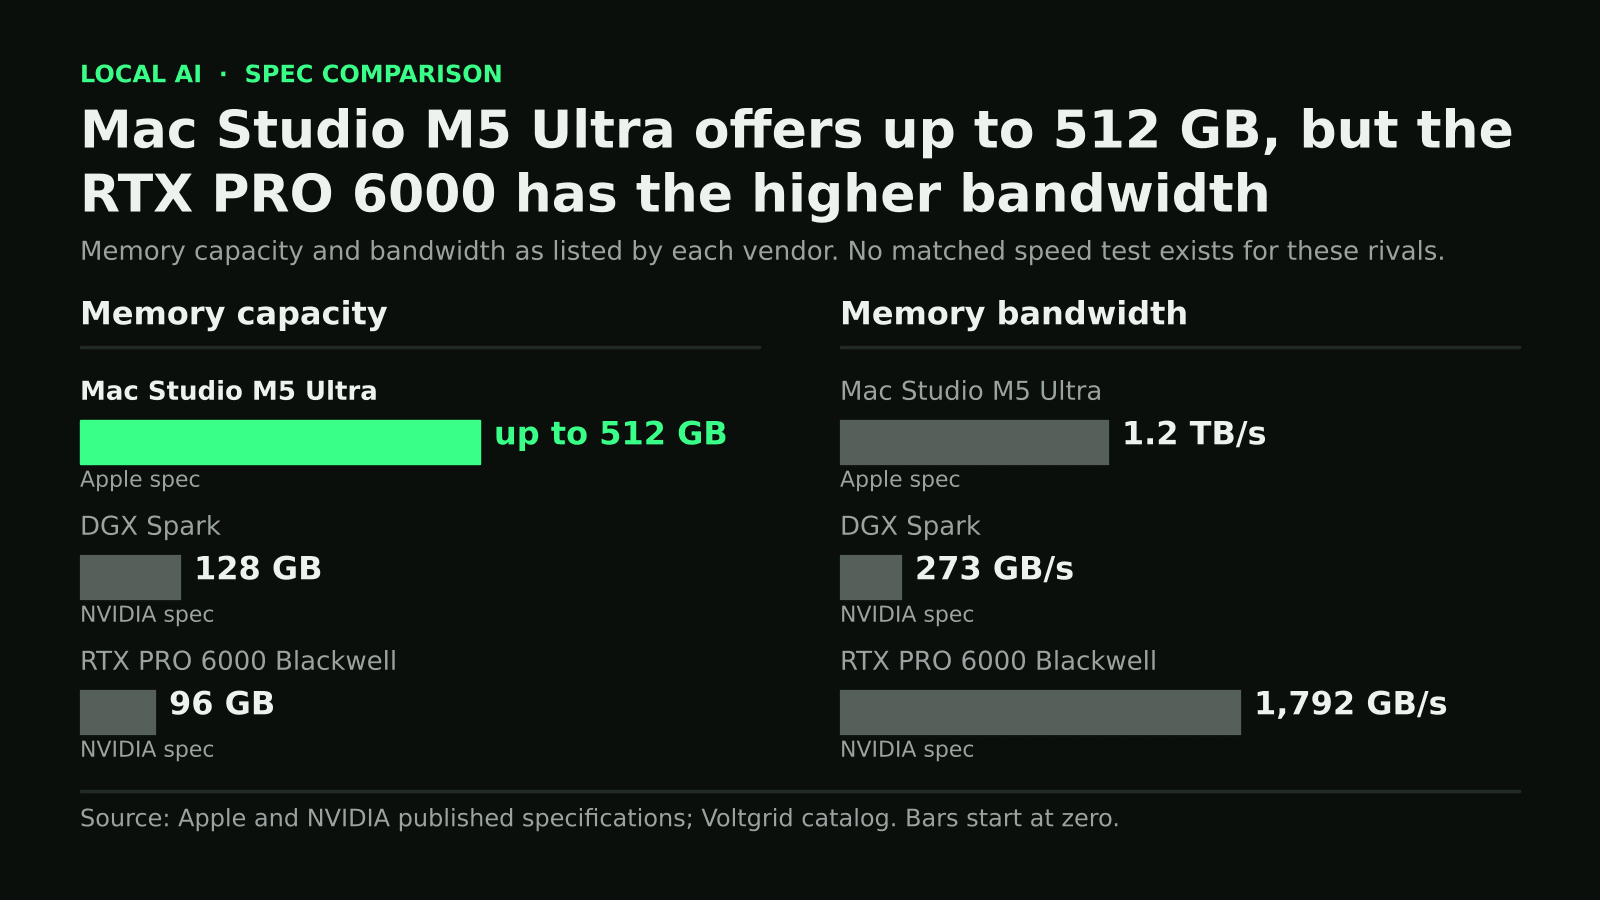
By vendor specification the M5 Ultra holds the most memory and the RTX PRO 6000 moves data fastest; no measurement on the same model, quantization and tool exists for these rivals, so only spec bars are shown.
Illustration (AI-generated)
The next capacity tier is the DGX Station. Its GB300 superchip has 748 GB of coherent memory, 252 GB of it HBM3e at 7.1 TB/s, and a 1,600 W system rating, as Voltgrid set out in its DGX Station product file. ServeTheHome heard prices around $100,000. A 512 GB Mac Studio at $22,299 to $29,799 sits between the Spark and the Station on both capacity and price. The table under this story lists the catalog figures for all four.
What to Watch
The first 512 GB deliveries are due on Dec. 3, according to Digital Trends, and the first independent runs on that configuration should follow. The open questions are whether 8-bit builds of models such as Flash-Next run fully in memory and at what speed, and whether 256K-context runs that failed on 256 GB complete. No outlet has published wall power under a sustained LLM load; Apple's 480 W is a maximum, not a measurement. Apple's claim that four clustered units deliver up to three times one unit's inference performance is also untested.
How it compares
Full table| Product | Memory | Bandwidth | AI compute | Measured speed | Price |
|---|---|---|---|---|---|
| HP ZGX Fury AI StationHP | 252 GB HBM3e GPU + 496 GB LPDDR5x CPU (4x 128 GB SOCAMM); 748 GB unified[1] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5x)[1] | — | — | Japan list price from 28,490,000 yen incl. tax (sales from Oct 27, 2026); no US list price published[2] |
| NVIDIA DGX StationNVIDIA (systems built by ASUS, Dell, GIGABYTE, HP, MSI, Supermicro and Exxact) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[3] | GPU HBM3e 7.1 TB/s; CPU LPDDR5X 396 GB/s; NVLink-C2C 900 GB/s between them[3] | 15 PFLOPS FP4 (without sparsity)[3] | Over 26,000 output tokens/s aggregate on Qwen3.6-35B-A3B NVFP4 at 512 concurrent users (24-30-token input, 1,024-token output), Gigabyte W775-V10-L01; idle never below 250 W.[4] | No list price from most OEMs (sales inquiry only); ServeTheHome heard about $100K, up to $120-125K, and unlikely under $80-85K[5] |
| NVIDIA RTX PRO 6000 Blackwell Workstation EditionNVIDIA (sold through PNY, TD SYNNEX and workstation makers) | 96 GB[6] | 1,792 GB/s[6] | 4,000 AI TOPS (FP4, with sparsity) (sparse)[6] | LM Studio: Mistral Small (26 GB) at 42.4 tokens/s vs 17 on an RTX 5090; Gemma 3 27B at 29 vs 5; tied with the RTX 5090 at about 81 tokens/s on DeepSeek Llama 8B Distil, where VRAM does not limit.[7] | $16,000 on NVIDIA's US marketplace (Workstation Edition), listed out of stock[8] |
| Apple Mac Studio (M5 Ultra)AppleThis story | up to 512 GB unified (96 GB on 30-core M5 Ultra; 256 GB or 512 GB on 36-core/80-core M5 Ultra)[9] | 1.2 TB/s[9] | — | Qwen 3.8 27B 4-bit MLX in LM Studio: about 55 tok/s on M5 Ultra (36-core, 256 GB) vs about 40 on M3 Ultra (BGR)[10] | $22,299 minimum with 512 GB ($6,799 36-core CPU/80-core GPU M5 Ultra config plus $15,500 memory upgrade; Oct 28, 2026)[11] |
| NVIDIA RTX Spark (N1X) PCsNVIDIA (MediaTek collaborated on the custom CPU design) | Up to 128 GB LPDDR5X (20-core CPU / 6,144-core GPU version); up to 64 GB (18-core / 5,120-core laptop version)[12] | Up to 300 GB/s: LPDDR5X-9400 on a 256-bit bus (NVIDIA's product page lists no bandwidth)[13] | — | gpt-oss:20b via Ollama in a Codex CLI coding agent, 64K context: 58.5 tok/s generation, 3 of 4 tasks passed (Dell XPS 16, 20-core N1X, 64 GB; StorageReview)[14] | Laptops from $2,599; pricing and configurations vary by region[15] |
| Framework Desktop (Ryzen AI Max+ PRO 495, 192 GB)Framework | 192 GB LPDDR5X-8533 soldered[16] | 273 GB/s (256-bit)[16] | — | — | from $6,799 (DIY Edition pre-order, Oct 30, 2026)[17] |
| Lenovo ThinkStation PGXLenovo | 128 GB LPDDR5X unified (256-bit)[18] | 273 GB/s[18] | — | — | about $4,100 for the 1 TB configuration (Mar 2026)[19] |
| MSI EdgeXpert (MS-C931)MSI | 64 GB or 128 GB LPDDR5x unified (256-bit)[20] | 273 GB/s[20] | 1 PFLOPS FP4 (sparse)[20] | — | No list price; MSI sells via quote (Get a quote)[20] |
| NVIDIA DGX SparkNVIDIA (partner GB10 systems from Acer, ASUS, Dell, GIGABYTE, HP, Lenovo and MSI) | 128 GB; a 64 GB configuration is sold only through OEM partners[21] | 273 GB/s[21] | Up to 1 PFLOP FP4 (theoretical, using the sparsity feature) (sparse)[21] | Qwen 3.8 27B (dense) with multi-token prediction: decode of about 20 tokens/s, with time-to-first-token staying interactive out to the full 262K context.[22] | $6,950.00 (128 GB, 4 TB) on NVIDIA's enterprise marketplace with an Add To Cart button in a copy cached 07:59 UTC on 2026-10-31; stock unverified (listed out of stock on 2026-10-21); 64 GB partner systems from $4,999[23] |
| NVIDIA DGX Spark 64 GBNVIDIA (sold by Acer, ASUS, Dell, Gigabyte, HP and MSI) | 64 GB LPDDR5X unified (two units pool 128 GB over ConnectX-7)[24] | 273 GB/s (256-bit; NVIDIA spec table covers both 64 GB and 128 GB)[21] | 1 PFLOPS FP4 (sparse; NVIDIA spec table covers both memory configurations)[21] | — | from $4,999 (partner systems, Oct 2026; no Founders Edition)[24] |
| AMD Ryzen AI Halo Developer PlatformAMD | 128 GB LPDDR5x-8000 unified[25] | 256 GB/s[25] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL 256/256: 222 tok/s aggregate at batch 64 vs 701 on DGX Spark (StorageReview)[26] | $3,999 with 2 TB SSD (Jul 2026)[26] |
| Framework Desktop (Ryzen AI Max+ 395)Framework | 128 GB LPDDR5x-8000 soldered (32 GB and 64 GB options)[27] | 256 GB/s[28] | — | — | $3,449 (DIY Edition, Max+ 395 with 128 GB, Oct 30, 2026)[17] |
| Acer Veriton GN100 AI Mini WorkstationAcer | 128 GB LPDDR5x coherent unified[29] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.65 tok/s at batch 1 rising to 713.18 tok/s aggregate at batch 64 (StorageReview)[30] | from $3,999 in North America (announced Sep 3, 2025; prices vary by region)[29] |
| ASRock Industrial AI BOX-A395ASRock Industrial | 128 GB LPDDR5X-8000 soldered[31] | — | — | AgentSTH V7, 32 threads: 15% ahead of the next-closest Ryzen AI Max+ 395 box (single-core within 1%); estimated SPEC CPU2026 int rate: top of a 44% spread across four 395 systems; measured by ServeTheHome, Ubuntu 26.04[32] | — |
| ASUS Ascent GX10ASUS | 64 GB or 128 GB LPDDR5X-8533 unified[33] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 70 tok/s at batch 1 rising to 680 tok/s aggregate at batch 64 (StorageReview)[34] | $5,999 (128 GB, 1 TB, GX10-GG0010BN, ASUS eShop US, Oct 30, 2026)[35] |
| Dell Pro Precision with GB10 (model FCM1253; launched as Dell Pro Max with GB10)Dell | 128 GB LPDDR5x up to 8533 MT/s onboard (64 GB option also listed)[36] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 68.57 tok/s at batch 1 rising to 670.83 tok/s aggregate at batch 64 (StorageReview)[37] | $6,593 (128 GB, 2 TB QLC SSD, Dell.com US, Oct 30, 2026)[36] |
| Dell Pro Precision with GB300 (model FCT6263; announced as Dell Pro Max with GB300)Dell | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU[38] | — | — | — | $160,195 (Dell.com US default config with RTX PRO 2000 display GPU and 16 TB SSD, read Nov 1, 2026)[38] |
| GIGABYTE AI TOP ATOMGIGABYTE | 128 GB unified system memory[39] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 60.71 tok/s at batch 1 rising to 649.62 tok/s aggregate at batch 64 (StorageReview)[40] | — |
| GMKtec EVO-X2 AI Mini PCGMKtec | 64 GB or 128 GB onboard LPDDR5X-8000 (non-upgradeable)[41] | — | — | — | $3,499.99 (128 GB/1 TB, GMKtec US store, Oct 30, 2026; listed against $3,999.99)[41] |
| HP Z2 Mini G1a WorkstationHP | up to 128 GB unified, up to 96 GB assignable to the GPU, up to 8000 MT/s[42] | — | — | gpt-oss-120b GGUF (63.39 GB, full GPU offload) in LM Studio: close to 40 tok/s (StorageReview)[43] | — |
| HP ZGX Nano AI Station (G1n)HP | 128 GB coherent unified system memory[44] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.6 tok/s at batch 1 rising to 722.9 tok/s aggregate at batch 64 (StorageReview)[45] | — |
| MSI XpertStation WS300MSI (NVIDIA DGX Station platform) | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU (748 GB coherent)[46] | — | — | GPT-OSS-120B MXFP4, vLLM, 512/512 ISL/OSL, concurrency sweep to 128: peak 9,294 output tok/s vs 3,384 on an RTX PRO 6000 and 500 on DGX Spark (StorageReview, MSI-hosted unit, no add-in GPU)[46] | ServeTheHome calls it a $100K+ system; no MSI list price given[47] |
| Tenstorrent TT-QuietBox 2 (Blackhole)Tenstorrent | 128 GB GDDR6 on the accelerators + 256 GB DDR5-5600 system memory[48] | — | — | — | $9,999 (Oct 30, 2026)[48] |
| WiCi One (RTX 5060 Ti edition)WiCi | 16 GB GDDR7 VRAM; 1 TB NVMe 4 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[49] | — | — | — | $2,599 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout. Early-access price was $1,999 (Notebookcheck, Engadget, Sep 2026)[49] |
| WiCi One (RTX 5090 edition)WiCi | 32 GB GDDR7 VRAM; 4 TB NVMe 5 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[49] | — | — | — | $9,999 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout[49] |
Italic values are reported by an outlet or measured by an independent lab; the rest come from the maker. Measured speeds use different models, quantizations and tools, so read each with its source rather than against the others. Voltgrid News does not test hardware itself.
Sources (49)
- [1] HP
- [2] HP Japan
- [3] NVIDIA
- [4] ServeTheHome
- [5] ServeTheHome
- [6] NVIDIA
- [7] Gamers Nexus
- [8] NVIDIA
- [9] Apple
- [10] BGR
- [11] MacRumors
- [12] NVIDIA
- [13] ServeTheHome
- [14] StorageReview
- [15] NVIDIA
- [16] Framework Blog
- [17] Framework
- [18] Lenovo PSREF
- [19] ServeTheHome
- [20] MSI
- [21] NVIDIA
- [22] Tom's Hardware
- [23] NVIDIA Marketplace
- [24] NVIDIA Blog
- [25] AMD
- [26] StorageReview
- [27] Framework
- [28] Framework Blog
- [29] Acer
- [30] StorageReview
- [31] ServeTheHome
- [32] ServeTheHome
- [33] ASUS
- [34] StorageReview
- [35] ASUS eShop
- [36] Dell
- [37] StorageReview
- [38] Dell
- [39] GIGABYTE (PR Newswire)
- [40] StorageReview
- [41] GMKtec
- [42] HP
- [43] StorageReview
- [44] HP
- [45] StorageReview
- [46] StorageReview
- [47] ServeTheHome
- [48] Tenstorrent
- [49] WiCi
Sources
- 01Apple's maxed-out M5 Ultra Mac Studio is here, and it costs as much as a Chevy Bolt EVDigital Trends · digitaltrends.com
- 02Mac Studio (M5 Ultra) Review: The Ultimate AI WorkstationBGR · bgr.com
- 03M5 Ultra Mac Studio Review: The Dream Mac for Local AI AgentsMacStories · macstories.net
- 04Mac Studio With M5 Ultra Now Available With 512GB RAM for $22,299MacRumors · macrumors.com
- 05Apple Mac Studio (M5 Ultra) review: Local model citizen outpaces DGX Spark and ThreadripperTom's Hardware · tomshardware.com
- 06Mac Studio - Technical SpecificationsApple · apple.com