HP ZGX Nano Review: Cool-Running GB10 Box Priced $4,759 to $7,399
HP ZGX Nano review: four outlets point to GB10-class performance, led by StorageReview's 722.9 tok/s on gpt-oss-120b at batch 64, with a cooler case, but reported 4 TB US prices conflict, $4,759 to $7,399.
Local AI DeskEdited by Ege Erten
8 min readAI-assisted
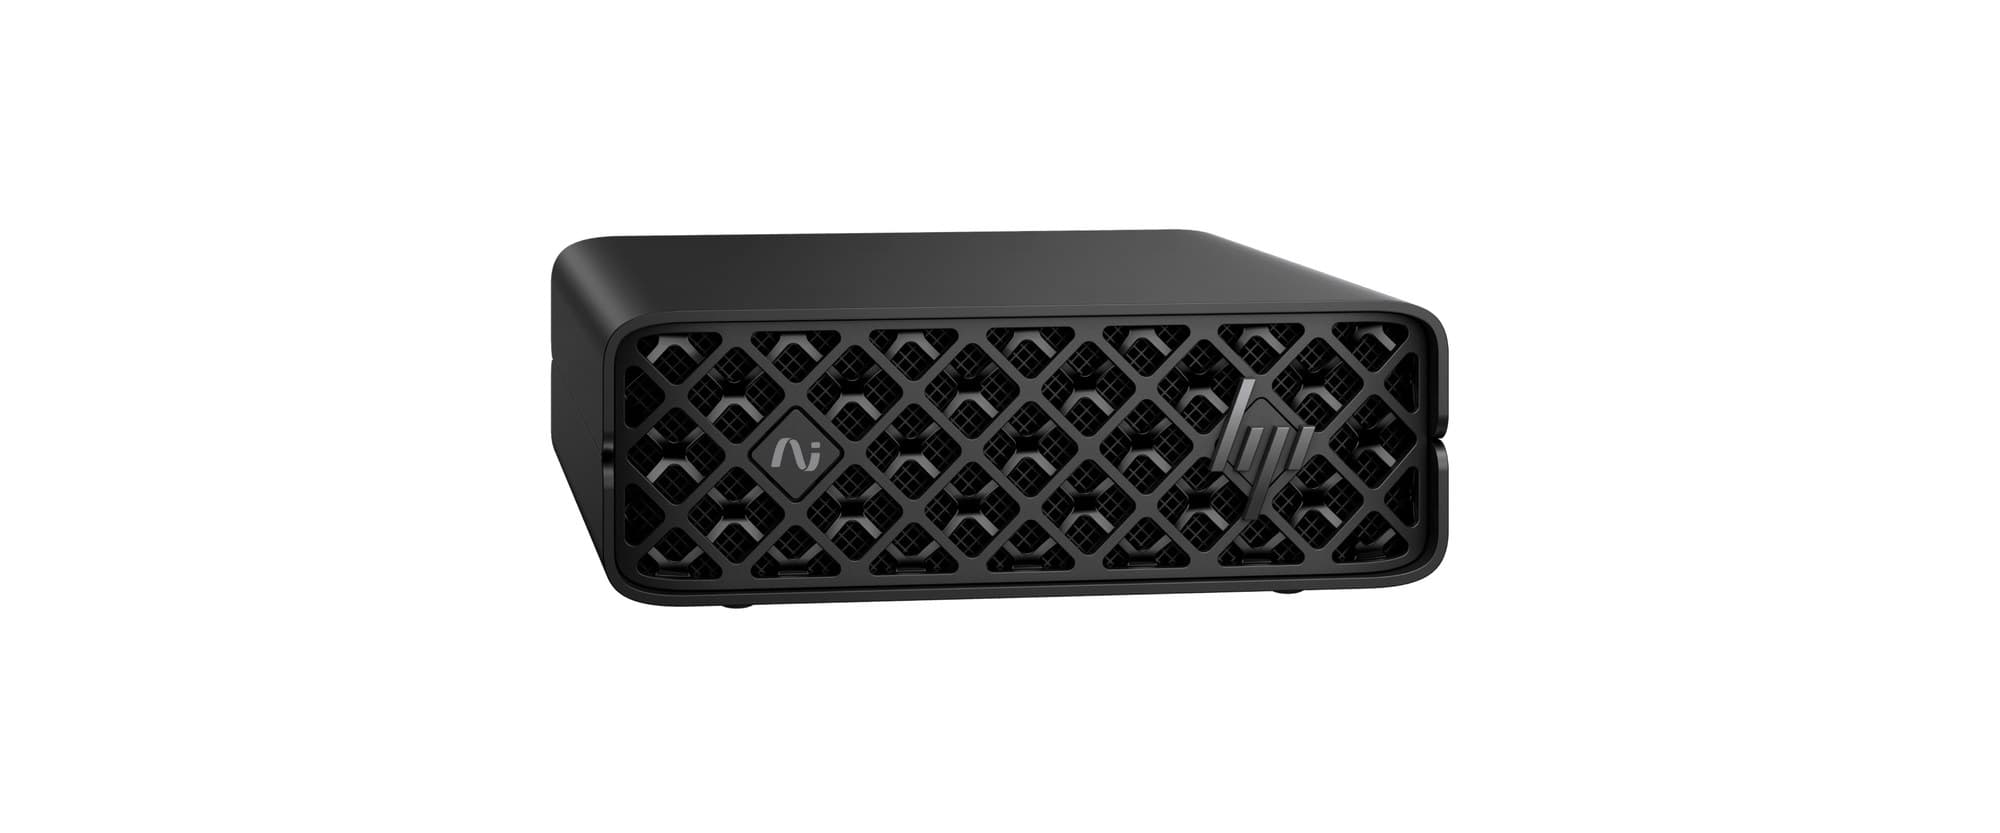
The HP ZGX Nano G1n AI Station, as shown on HP's product page.
Image: HP
Source · Press image from the HP product page, used for news reporting.
HP's ZGX Nano G1n AI Station puts NVIDIA's GB10 chip and 128 GB of unified memory in a 150 mm box. HP ZGX Nano review results from four outlets point to GB10-class performance: StorageReview measured 722.9 tokens per second in aggregate on gpt-oss-120b at batch 64. What separates it is cooling, a security stack for regulated buyers and a price nobody agrees on.
HP's US product page lists no price. The reported figures for the same machine run from $4,759 to $7,399 for the 4 TB model, depending on the outlet, the retailer and the date. That spread is as wide as the gap between the reported ZGX Nano prices and the DGX Spark's $6,950 listing, so the price a buyer is actually quoted matters more than any benchmark below.
What's new in the HP ZGX Nano
The silicon is not new. HP lists the NVIDIA GB10 Grace Blackwell Superchip with a 20-core Arm Grace CPU and 128 GB of coherent unified memory, the same pairing as NVIDIA's own DGX Spark. HotHardware gives its memory bandwidth as 273 GB/s, the figure NVIDIA's DGX Spark spec page uses for GB10. HP claims up to 1,000 TOPS of AI compute without naming the precision on its page; StorageReview's and Notebookcheck's spec tables list it as FP4. NVIDIA's own spec page for GB10 labels its 1 PFLOP FP4 figure theoretical, with sparsity, and states no dense number.
The chassis is HP's own. ServeTheHome, which reviewed the unit on May 4, 2026, found a front almost entirely given over to mesh, and HotHardware said the open grille lets the box draw in noticeably cool air. StorageReview reported that HP splits the case into upper and lower halves, which makes the SSD and coin-cell battery easier to reach, and uses up to 75% recycled aluminum.
Security is the second change. StorageReview listed a TPM 2.0 module running in FIPS 140-2 mode, Common Criteria EAL4+ certification and self-encrypting OPAL drives. HP also sells a Secure & Regulated Environments version with no Wi-Fi or Bluetooth radios, and now supports its Remote System Controller for BIOS-level remote keyboard, video and mouse access, though not remote power-on.
The software is mostly NVIDIA's. HotHardware and ServeTheHome both found DGX OS, NVIDIA's Ubuntu 24.04-based system, with HP branding on top. HP adds its free Z Toolkit, which installs MLflow, Ollama and other open-source tools from an x86 client running VS Code; HP claims it cuts setup time by 45% on average against a do-it-yourself install, a figure no reviewer has checked.
What 722.9 Tokens Per Second at Batch 64 Means
Batch size is how many requests the server answers at the same time. In StorageReview's vLLM test of gpt-oss-120b, the ZGX Nano produced 69.6 tokens per second at batch 1 and 722.9 at batch 64. The second figure is the total across all 64 requests, not the speed any one user sees.
Each pass over the model's weights serves every request in the batch, so the total climbs while memory bandwidth stays fixed at 273 GB/s, as HotHardware lists it. The decode-heavy run shows the ceiling: it rose only from 183.7 to 262.9 tokens per second. A shared box can serve a small team, but one user running a dense model still waits on memory.
What it solves: a 120B model on a desk
The 128 GB pool is the point. A 120-billion-parameter model such as gpt-oss-120b fits in memory without a server or a cloud instance, and HP says one unit handles models up to 200B parameters, or 405B with two units joined by a QSFP cable that is sold separately. Both are HP's claims; none of the reviewers ran a 405B model across two units.
Memory bandwidth sets how fast such a model writes. Every generated token requires reading the model's active weights from memory, so 273 GB/s caps decode speed no matter how much compute sits beside it. HotHardware put it plainly on a dense model: a Qwen 3.8 27B coding agent ran at about 13 tokens per second with an empty context and slowed to about 9 as the input grew, though 16 agents in parallel reached about 80 tokens per second in total. HotHardware did not restate the quantization for that run; its llama.cpp tests on the same model used Unsloth's UD-Q4_K_M.
Mixture-of-experts models suit the box better because few weights are active per token. HotHardware ran NVIDIA's NVFP4 build of Qwen 3.8 Flash Next in vLLM and saw an 8,000-token prompt processed in about 4.5 seconds, with output streaming at about 45 tokens per second.
Pros and Cons
The throughput figure comes from StorageReview's vLLM online-serving sweep, where gpt-oss-120b rose from 69.6 tokens per second at batch 1 to 722.9 at batch 64 with equal input and output lengths. In its prefill-heavy run the same model climbed from 304.5 to 2,773.3 tokens per second, while the decode-heavy run went from 183.7 to 262.9, a pattern consistent with a bandwidth-limited chip. ServeTheHome's Geekbench 6 and heat-soak tests placed the unit second or third among six GB10 systems, never first, which it called the expected result of NVIDIA's tight design rules.
On heat, StorageReview logged a 77.3 °C CPU peak and a 69 °C GPU peak, on the cool side of the GB10 units it has tested, some of which pushed CPUs into the 90 °C range. HotHardware put the enclosure at about 98 °F under load against 115 °F on the Dell Pro Max with GB10, readings it describes as how cool the case feels to the touch (it used a laser thermometer on the exhaust, not the case), and said the DGX Spark was similar to the Dell. Notebookcheck measured surfaces around 50 °C, so the outlets did not measure the same point on the case. HotHardware also found the fans a little louder than rivals, and Notebookcheck measured 30 dB(A) idle and 40 dB(A) at full load; the 27.6 dBA load figure StorageReview quoted is HP's rating, not a measurement.
Power readings broadly agree. ServeTheHome measured 37 to 40 W at idle, about 18 W of which it traced to an active ConnectX-7 link, peaks just under 200 W and 110 to 140 W with many LLMs. Notebookcheck measured up to 206 W at full GPU load and about 160 W in sustained inference. HotHardware calculated that the GB10 chip itself used about 1,900 joules per 1,000 tokens on Qwen 3 Coder Next at low concurrency, falling to about 1,450 as concurrency rose, a chip reading from nvidia-smi that excludes adapter losses.
The software complaints are specific. HotHardware's vLLM container crashed with CUBLAS_STATUS_INTERNAL_ERROR, and as of early September it could not keep prefix caching stable, so long coding sessions reprocessed tens of thousands of tokens per edit until it switched to a community recipe. Notebookcheck found some of NVIDIA's ready-made blueprints outdated, could not install the Multi-modal Inference one, and saw gpt-oss 120B take up to three minutes to load. In its count-to-1,000 test the model started at 40 to 55 tokens per second and fell below 5 as the context filled; Notebookcheck did not state the quantization or the inference tool.
Who the HP ZGX Nano is for
It fits a corporate or public-sector AI team that must clear procurement: the FIPS-mode TPM, EAL4+ certification, self-encrypting storage and radio-free option are the features StorageReview singled out. It also fits a developer who wants a 120B mixture-of-experts model served locally to several users, where StorageReview's 722.9 tokens per second at batch 64 applies, and who will keep the box on a desk, where HotHardware's cooler enclosure matters.
It does not fit a buyer paying retail who only needs a GB10. Reviewers found GB10-class performance, and ServeTheHome noted that GB10 partners have limited room to differentiate beyond cooling, SSD, support and services, so a buyer paying a premium should need what HP adds. It also fits poorly for anyone whose main model is dense: HotHardware's 9 to 13 tokens per second on a 27B dense model is what 273 GB/s allows.
How it compares with DGX Spark, Dell and Ryzen AI Halo
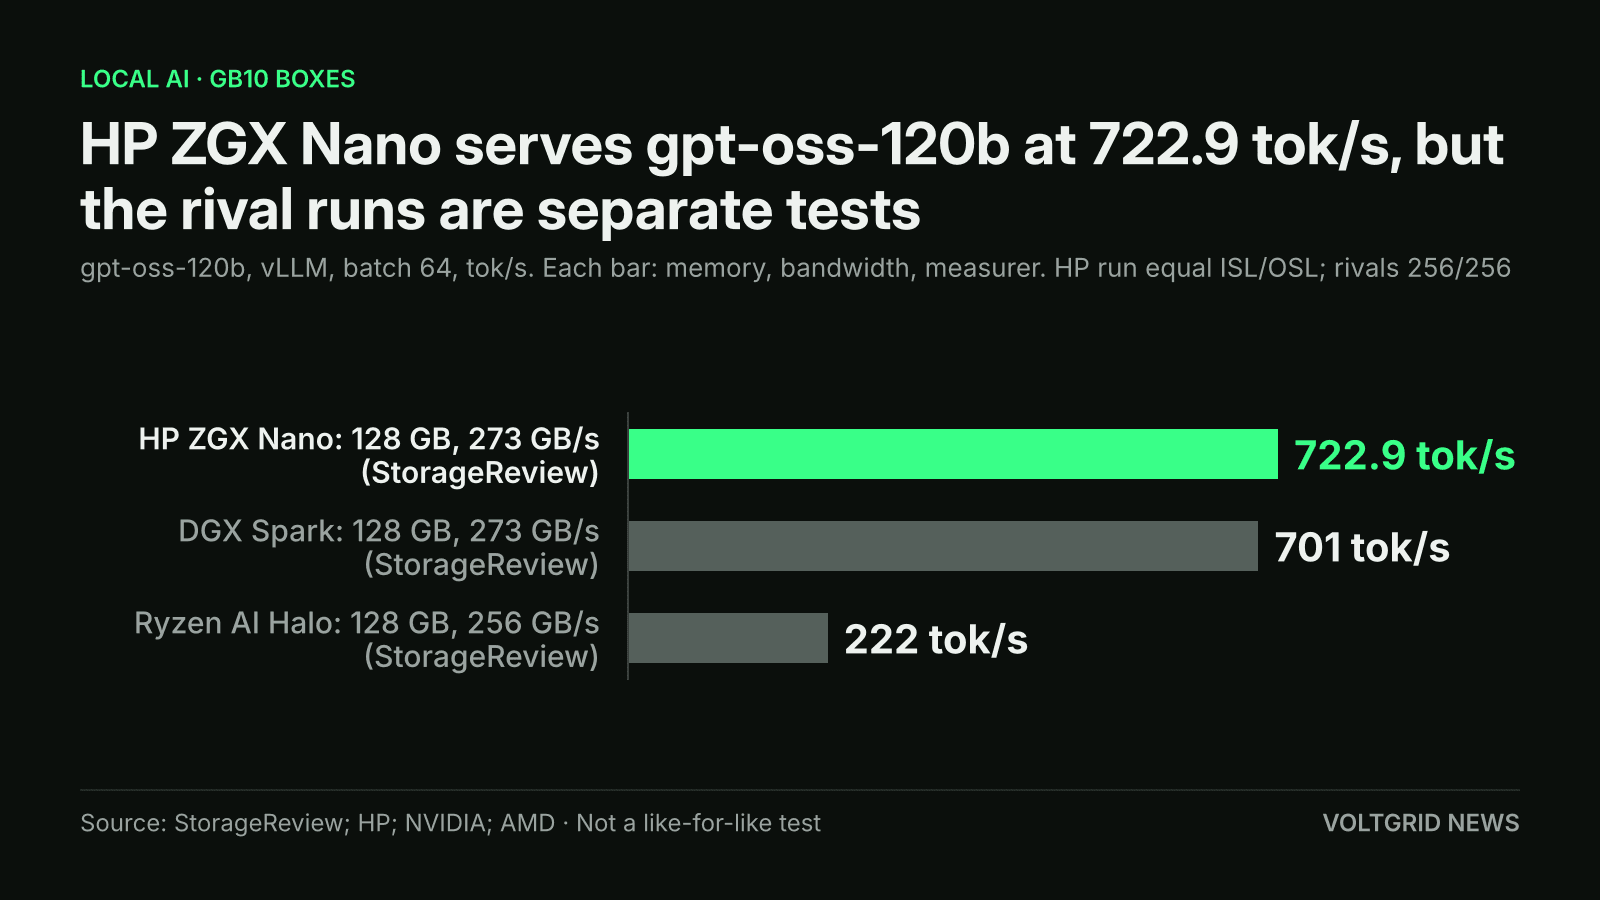
StorageReview measured all three, but in separate reviews: the HP run is equal ISL/OSL, the rival run 256/256.
Illustration (AI-generated)
Against other GB10 boxes, the useful comparison is StorageReview's. Its separate reviews measured 722.9 tokens per second on the ZGX Nano (April) and 670.83 on Dell's GB10 system (March) with the same method (gpt-oss-120b, vLLM, batch 64), though neither review states the token lengths. NVIDIA's DGX Spark shares the 128 GB and 273 GB/s and listed at $6,950 for 128 GB and 4 TB on NVIDIA's marketplace on Oct. 31, with stock unverified. Dell.com listed its GB10 system at $6,593 on Oct. 30 and $8,103 on Nov. 2, both for 128 GB with a 2 TB QLC drive.
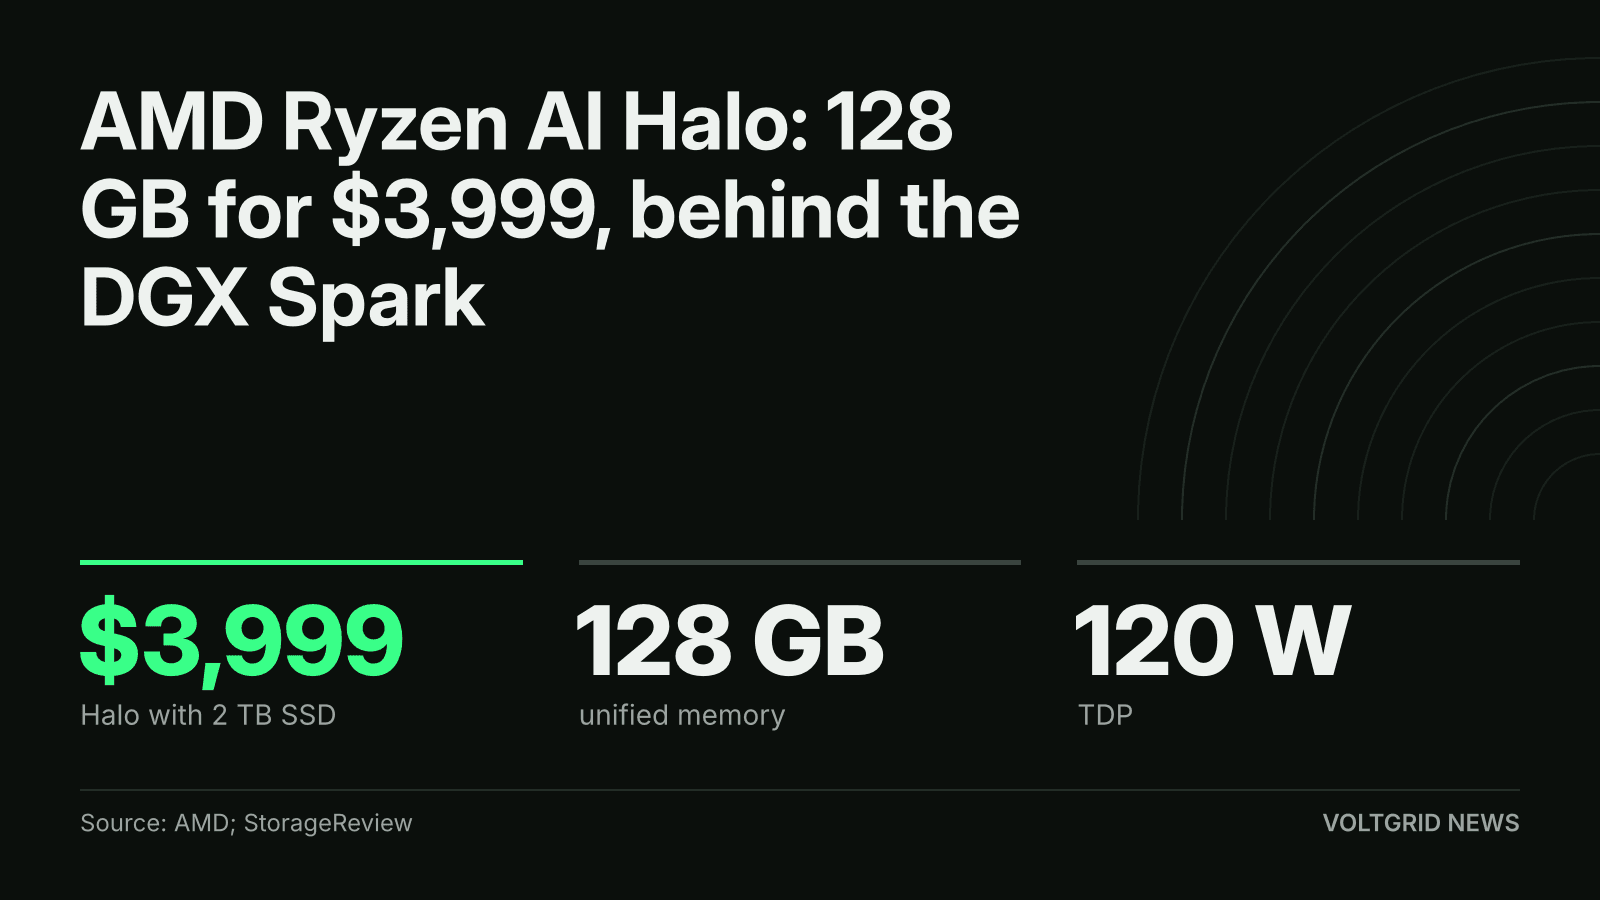
AMD's Ryzen AI Halo is the 128 GB alternative at $3,999 with 2 TB, as StorageReview reported in July. Its memory runs at 256 GB/s, a gap HotHardware puts at 6% in the ZGX Nano's favor, and HotHardware's direct llama.cpp comparison (CUDA on DGX OS against ROCm on Windows 11, Unsloth UD-Q4_K_M for the medium models, which it credits partly to NVIDIA's more mature software stack) matched that: the ZGX Nano generated tokens a few percent faster, but processed long uncached prompts far faster and ran embeddings more than twice as fast. StorageReview measured the Halo at 222 tokens per second on gpt-oss-120b at batch 64 against 701 on a DGX Spark, using 256-token inputs and outputs; its HP review does not state the token lengths behind its 722.9 figure, so the two runs should not be set side by side as one test.
Price undoes much of the HP case. Notebookcheck, in its Oct. 5 update, found the 4 TB model at $4,759 on Amazon and $7,399 at the HP Store. HotHardware headed its Oct. 2 review with $5,749 as of Oct. 1, then gave $5,649 for its 2 TB unit and $6,700 for 4 TB in its conclusion. These figures conflict and Voltgrid could not confirm a current HP Store price; at the low end the ZGX Nano undercuts the DGX Spark's $6,950 listing, and at the high end, both for 4 TB, it costs $449 more (Voltgrid arithmetic).
What to watch
The first thing to settle is HP's own US price, which its product page does not show. The next is software: HotHardware's crash and Notebookcheck's broken blueprints are NVIDIA stack issues that affect every GB10 box, so a DGX OS or vLLM release that stabilizes prefix caching on GB10, should one arrive, would lift the ZGX Nano along with its rivals. NVIDIA reports its third fiscal quarter on Nov. 17, 2026, and no reviewer has yet tested HP's 405B two-unit claim.
How it compares
Full table| Product | Memory | Bandwidth | AI compute | Measured speed | Price |
|---|---|---|---|---|---|
| HP ZGX Fury AI StationHP | 252 GB HBM3e GPU + 496 GB LPDDR5x CPU (4x 128 GB SOCAMM); 748 GB unified[1] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5x)[1] | — | Two-unit cluster with an ASUS ET900N G3 over two 400G DACs: GLM-5.3 NVFP4 5,018 output tok/s at 256 streams, 512/512, vLLM 0.27.1 TP2 with MTP (StorageReview); no single-unit HP result[2] | Japan list price from 28,490,000 yen incl. tax (sales from Oct 27, 2026); no US list price published[3] |
| NVIDIA DGX StationNVIDIA (systems built by ASUS, Dell, GIGABYTE, HP, MSI, Supermicro and Exxact) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[4] | GPU HBM3e 7.1 TB/s; CPU LPDDR5X 396 GB/s; NVLink-C2C 900 GB/s between them[4] | 15 PFLOPS FP4 (without sparsity)[4] | Over 26,000 output tokens/s aggregate on Qwen3.6-35B-A3B NVFP4 at 512 concurrent users (24-30-token input, 1,024-token output), Gigabyte W775-V10-L01; idle never below 250 W.[5] | No NVIDIA list price; first public US OEM list price is Dell Pro Precision with GB300 at $160,195 default config (Dell.com, read Nov 1, 2026); ServeTheHome had heard about $100K[6] |
| NVIDIA RTX PRO 6000 Blackwell Workstation EditionNVIDIA (sold through PNY, TD SYNNEX and workstation makers) | 96 GB[7] | 1,792 GB/s[7] | 4,000 AI TOPS (FP4, with sparsity) (sparse)[7] | LM Studio: Mistral Small (26 GB) at 42.4 tokens/s vs 17 on an RTX 5090; Gemma 3 27B at 29 vs 5; tied with the RTX 5090 at about 81 tokens/s on DeepSeek Llama 8B Distil, where VRAM does not limit.[8] | $16,000 on NVIDIA's US marketplace (Workstation Edition), listed out of stock[9] |
| Apple Mac Studio (M5 Ultra)Apple | up to 512 GB unified (96 GB on 30-core M5 Ultra; 256 GB or 512 GB on 36-core/80-core M5 Ultra)[10] | 1.2 TB/s[10] | — | Qwen 3.8 27B 4-bit MLX in LM Studio: about 55 tok/s on M5 Ultra (36-core, 256 GB) vs about 40 on M3 Ultra (BGR)[11] | $22,299 minimum with 512 GB ($6,799 36-core CPU/80-core GPU M5 Ultra config plus $15,500 memory upgrade; Oct 28, 2026)[12] |
| NVIDIA RTX Spark (N1X) PCsNVIDIA (MediaTek collaborated on the custom CPU design) | Up to 128 GB LPDDR5X (20-core CPU / 6,144-core GPU version); up to 64 GB (18-core / 5,120-core laptop version)[13] | Up to 300 GB/s: LPDDR5X-9400 on a 256-bit bus (NVIDIA's product page lists no bandwidth)[14] | — | gpt-oss:20b via Ollama in a Codex CLI coding agent, 64K context: 58.5 tok/s generation, 3 of 4 tasks passed (Dell XPS 16, 20-core N1X, 64 GB; StorageReview)[15] | Laptops from $2,599; pricing and configurations vary by region[16] |
| Dell Pro Precision with GB10 (model FCM1253; launched as Dell Pro Max with GB10)Dell | 128 GB LPDDR5x up to 8533 MT/s onboard (64 GB option also listed)[17] | 273 GB/s (128 GB LPDDR5x, 256-bit)[18] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 68.57 tok/s at batch 1 rising to 670.83 tok/s aggregate at batch 64 (StorageReview)[19] | $8,103 (128 GB, 2 TB Gen4 QLC SSD default config, in stock, no discount, Dell.com US, read Nov 2, 2026)[17] |
| Framework Desktop (Ryzen AI Max+ PRO 495, 192 GB)Framework | 192 GB LPDDR5X-8533 soldered[20] | 273 GB/s (256-bit)[20] | — | — | from $6,799 (DIY Edition pre-order, Oct 30, 2026)[21] |
| GMKtec EVO-X5 Pro AI Mini PCGMKtec | 192 GB LPDDR5X-8533 onboard (8 x 24 GB, non-upgradeable); up to 160 GB allocatable as VRAM[22] | 273 GB/s[23] | — | — | $6,799 (192 GB/2 TB) and $7,099 (192 GB/4 TB), GMKtec US store, Nov 2, 2026[22] |
| HP ZGX Nano AI Station (G1n)HPThis story | 128 GB coherent unified system memory[24] | 273 GB/s (128 GB LPDDR5x)[25] | GB10: up to 1 PFLOP FP4, theoretical, using the sparsity feature; HP and reviewers list 1,000 TOPS FP4 (sparse)[26] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.6 tok/s at batch 1 rising to 722.9 tok/s aggregate at batch 64 (StorageReview)[27] | $7,399.00 at the HP Store for the 4 TB model; $4,759 on Amazon (Notebookcheck, review updated Oct 5, 2026)[28] |
| Lenovo ThinkStation PGXLenovo | 128 GB LPDDR5X unified (256-bit)[29] | 273 GB/s[29] | — | — | about $4,100 for the 1 TB configuration (Mar 2026)[30] |
| MSI EdgeXpert (MS-C931)MSI | 64 GB or 128 GB LPDDR5x unified (256-bit)[31] | 273 GB/s[31] | 1 PFLOPS FP4 (sparse)[31] | — | No list price; MSI sells via quote (Get a quote)[31] |
| NVIDIA DGX SparkNVIDIA (partner GB10 systems from Acer, ASUS, Dell, GIGABYTE, HP, Lenovo and MSI) | 128 GB; a 64 GB configuration is sold only through OEM partners[26] | 273 GB/s[26] | Up to 1 PFLOP FP4 (theoretical, using the sparsity feature) (sparse)[26] | Qwen 3.8 27B (dense) with multi-token prediction: decode of about 20 tokens/s, with time-to-first-token staying interactive out to the full 262K context.[32] | $6,950.00 (128 GB, 4 TB) on NVIDIA's enterprise marketplace with an Add To Cart button in a copy cached 07:59 UTC on 2026-10-31; stock unverified (listed out of stock on 2026-10-21); 64 GB partner systems from $4,999[33] |
| NVIDIA DGX Spark 64 GBNVIDIA (sold by Acer, ASUS, Dell, Gigabyte, HP and MSI) | 64 GB LPDDR5X unified (two units pool 128 GB over ConnectX-7)[34] | 273 GB/s (256-bit; NVIDIA spec table covers both 64 GB and 128 GB)[26] | 1 PFLOPS FP4 (sparse; NVIDIA spec table covers both memory configurations)[26] | — | from $4,999 (partner systems, Oct 2026; no Founders Edition)[34] |
| AMD Ryzen AI Halo Developer PlatformAMD | 128 GB LPDDR5x-8000 unified[35] | 256 GB/s[35] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL 256/256: 222 tok/s aggregate at batch 64 vs 701 on DGX Spark (StorageReview)[36] | $3,999 with 2 TB SSD (Jul 2026)[36] |
| Framework Desktop (Ryzen AI Max+ 395)Framework | 128 GB LPDDR5x-8000 soldered (32 GB and 64 GB options)[37] | 256 GB/s[38] | — | — | $3,449 (DIY Edition, Max+ 395 with 128 GB, Oct 30, 2026)[21] |
| Acer Veriton GN100 AI Mini WorkstationAcer | 128 GB LPDDR5x coherent unified[39] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.65 tok/s at batch 1 rising to 713.18 tok/s aggregate at batch 64 (StorageReview)[40] | from $3,999 in North America (announced Sep 3, 2025; prices vary by region)[39] |
| ASRock Industrial AI BOX-A395ASRock Industrial | 128 GB LPDDR5X-8000 soldered[41] | — | — | AgentSTH V7, 32 threads: 15% ahead of the next-closest Ryzen AI Max+ 395 box (single-core within 1%); estimated SPEC CPU2026 int rate: top of a 44% spread across four 395 systems; measured by ServeTheHome, Ubuntu 26.04[42] | — |
| ASUS Ascent GX10ASUS | 64 GB or 128 GB LPDDR5X-8533 unified[43] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 70 tok/s at batch 1 rising to 680 tok/s aggregate at batch 64 (StorageReview)[44] | $5,999 (128 GB, 1 TB, GX10-GG0010BN, ASUS eShop US, Oct 30, 2026)[45] |
| Dell Pro Precision with GB300 (model FCT6263; announced as Dell Pro Max with GB300)Dell | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU[6] | — | — | — | $160,195 (Dell.com US default config with RTX PRO 2000 display GPU and 16 TB SSD, read Nov 1, 2026)[6] |
| GIGABYTE AI TOP ATOMGIGABYTE | 128 GB unified system memory[46] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 60.71 tok/s at batch 1 rising to 649.62 tok/s aggregate at batch 64 (StorageReview)[47] | — |
| GMKtec EVO-X2 AI Mini PCGMKtec | 64 GB or 128 GB onboard LPDDR5X-8000 (non-upgradeable)[48] | — | — | — | $3,499.99 (128 GB/1 TB, GMKtec US store, Oct 30, 2026; listed against $3,999.99)[48] |
| HP Z2 Mini G1a WorkstationHP | up to 128 GB unified, up to 96 GB assignable to the GPU, up to 8000 MT/s[49] | — | — | gpt-oss-120b GGUF (63.39 GB, full GPU offload) in LM Studio: close to 40 tok/s (StorageReview)[50] | — |
| Microsoft Surface RTX Spark Dev BoxMicrosoft | 128 GB unified memory[51] | — | up to 1 PFLOP of AI compute (Microsoft; precision and sparsity not stated on the page) (sparse)[51] | — | From $5,999.99 (Microsoft Store US, pre-order, read Nov 1, 2026)[51] |
| MSI XpertStation WS300MSI (NVIDIA DGX Station platform) | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU (748 GB coherent)[52] | — | — | GPT-OSS-120B MXFP4, vLLM, 512/512 ISL/OSL, concurrency sweep to 128: peak 9,294 output tok/s vs 3,384 on an RTX PRO 6000 and 500 on DGX Spark (StorageReview, MSI-hosted unit, no add-in GPU)[52] | ServeTheHome calls it a $100K+ system; no MSI list price given[53] |
| Tenstorrent TT-QuietBox 2 (Blackhole)Tenstorrent | 128 GB GDDR6 on the accelerators + 256 GB DDR5-5600 system memory[54] | — | — | — | $9,999 (Oct 30, 2026)[54] |
| WiCi One (RTX 5060 Ti edition)WiCi | 16 GB GDDR7 VRAM; 1 TB NVMe 4 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[55] | — | — | — | $2,599 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout. Early-access price was $1,999 (Notebookcheck, Engadget, Sep 2026)[55] |
| WiCi One (RTX 5090 edition)WiCi | 32 GB GDDR7 VRAM; 4 TB NVMe 5 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[55] | — | — | — | $9,999 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout[55] |
Italic values are reported by an outlet or measured by an independent lab; the rest come from the maker. Measured speeds use different models, quantizations and tools, so read each with its source rather than against the others. Voltgrid News does not test hardware itself.
Sources (55)
- [1] HP
- [2] StorageReview
- [3] HP Japan
- [4] NVIDIA
- [5] ServeTheHome
- [6] Dell
- [7] NVIDIA
- [8] Gamers Nexus
- [9] NVIDIA
- [10] Apple
- [11] BGR
- [12] MacRumors
- [13] NVIDIA
- [14] ServeTheHome
- [15] StorageReview
- [16] NVIDIA
- [17] Dell
- [18] HotHardware
- [19] StorageReview
- [20] Framework Blog
- [21] Framework
- [22] GMKtec
- [23] GMKtec
- [24] HP
- [25] HotHardware
- [26] NVIDIA
- [27] StorageReview
- [28] Notebookcheck
- [29] Lenovo PSREF
- [30] ServeTheHome
- [31] MSI
- [32] Tom's Hardware
- [33] NVIDIA Marketplace
- [34] NVIDIA Blog
- [35] AMD
- [36] StorageReview
- [37] Framework
- [38] Framework Blog
- [39] Acer
- [40] StorageReview
- [41] ServeTheHome
- [42] ServeTheHome
- [43] ASUS
- [44] StorageReview
- [45] ASUS eShop
- [46] GIGABYTE (PR Newswire)
- [47] StorageReview
- [48] GMKtec
- [49] HP
- [50] StorageReview
- [51] Microsoft
- [52] StorageReview
- [53] ServeTheHome
- [54] Tenstorrent
- [55] WiCi
Sources
- 01HP ZGX Nano G1n Review: GB10 Mini PC Runs Local Qwen Coding AgentHotHardware · hothardware.com
- 02HP ZGX Nano G1n AI Station Review: A Secure, Sustainable Desk-Side AI NodeStorageReview · storagereview.com
- 03HP ZGX Nano G1n review: the HP take on the NVIDIA GB10ServeTheHome · servethehome.com
- 04HP ZGX Nano G1n AI Station review: Compact server power with Nvidia DGX SparkNotebookcheck · notebookcheck.net
- 05HP ZGX Nano AI StationHP · hp.com