DGX Station Alternatives: 4 RTX PRO 6000s Lead Only on MiniMax M3
In StorageReview's tests, four RTX PRO 6000s beat the GB300 DGX Station only on MiniMax M3 at 4 to 16 streams, peaking at 1,181 vs a best-case 940 tok/s. Cheaper Mac and Strix Halo clusters are unmeasured.
Local AI DeskEdited by Ege Erten
11 min readAI-assisted
Follows our story: ASUS ET900N G3 Price: US Resellers List DGX Station Build From $111,999.99
NVIDIA's DGX Station, the GB300 desktop that the alternatives in this comparison are measured against.
Image: NVIDIA
Source · Press image from the NVIDIA newsroom, used for news reporting.
No DGX Station alternative with a public US price beats the GB300 desktop on price, measured throughput and memory at once, on the prices and independent measurements available on Nov. 4, 2026.
The closest call is four NVIDIA RTX PRO 6000 cards. In StorageReview's tests they beat the Station only on MiniMax M3, a model that barely fits its fast memory, and only from 4 to 16 concurrent streams: 1,181 output tokens per second against 940 at 16, then 759 against 1,041 at 32. The Station's figures there are best-case, because the lab forced its speculative decoder's acceptance length. Two AMD MI350P server cards led on two models at 32 streams, but in AMD's MXFP4 against NVIDIA's NVFP4, and Voltgrid found no public price for them. The baseline price varies too: Central Computers shows $111,999.99 for ASUS's build of the Station as a request-a-quote listing, ASUS publishes no list price, and Exxact's starting price is $98,450.00, with no storage stated.
The four cards hold 384 GB of GDDR7 across four boards, 51% of the Station's 748 GB, which counts 496 GB of slower CPU memory, by Voltgrid's arithmetic, and none of the US builders Voltgrid read publishes a fixed four-card price. Two 512 GB Mac Studio M5 Ultras or four 192 GB Strix Halo mini PCs cost less and add up to more memory on paper, but Voltgrid found no lab that had measured either serving many users as of Nov. 4.
The job is serving a 120B-class open model such as gpt-oss-120b, or a larger mixture-of-experts model, to many users or agents on premises. Voltgrid did not test these machines. Every speed below names who measured it and on which model, says where the lab left quantization or software unstated, and stays inside one test setup. Our DGX Station review covers the platform.
The baseline: 748 GB and 9,280 tokens per second
Every GB300 desktop is built around the same GB300 Superchip design: one Blackwell Ultra GPU with 252 GB of HBM3e at 7.1 TB/s, joined by an NVLink-C2C link that NVIDIA lists at 900 GB/s, and StorageReview labels bidirectional, to a 72-core Grace CPU with 496 GB of LPDDR5X at 396 GB/s. NVIDIA counts the two pools as 748 GB of coherent memory. It lists 1,600 W of total system power and a 20 A circuit; full-load wall power is unpublished.
US prices read on Nov. 4 start at $98,450 for Exxact's Valence DGX Station, which Tom's Hardware found at $94,930 in August. MSI's XpertStation WS300, model WS300T60L with two 2 TB drives, lists at $99,999 at Newegg as a "start from" price on a request-a-quote listing. Puget Systems' GB300 XpertStation is $106,648.80 as configured, and Dell's default Pro Precision build, with a display card and 16 TB of SSDs, is $160,195. TechRadar reported on Sept. 1 that Supermicro had begun selling its GB300 workstation at $92,887.47 before tax and shipping, or about $90,101.05 with a 3% new-customer discount; its headline says almost $91,100. Voltgrid could not find Supermicro's US store page for the model on Nov. 4. These are starting, listed, default or request-a-quote prices, and none is a confirmed delivered price.
StorageReview's vLLM serving test is the yardstick: 512-token prompts and 512-token answers, with concurrent streams doubling up to 128. On gpt-oss-120b, which ships in MXFP4 so every machine runs the same weights, the lab measured 9,280 and 9,294 aggregate output tokens per second at 128 streams on an ASUS ExpertCenter Pro ET900N G3 and an MSI WS300, or 5,023 and 5,038 with 8,192-token prompts and 1,024-token answers. One AMD Instinct MI350P at 450 W, on vLLM 0.32.0 and ROCm 10.1.0, reached 5,057, and one 600 W RTX PRO 6000 Server Edition in a Dell XE7740, on NVIDIA's vLLM 26.08 container, reached 3,064, according to StorageReview's MI350P first look. A DGX Spark-class Acer Veriton GN100 reached 500, a result the lab's ASUS review carries over from its August WS300 testing. Voltgrid found no four-card, Mac, Strix Halo or Tenstorrent result for this setup.
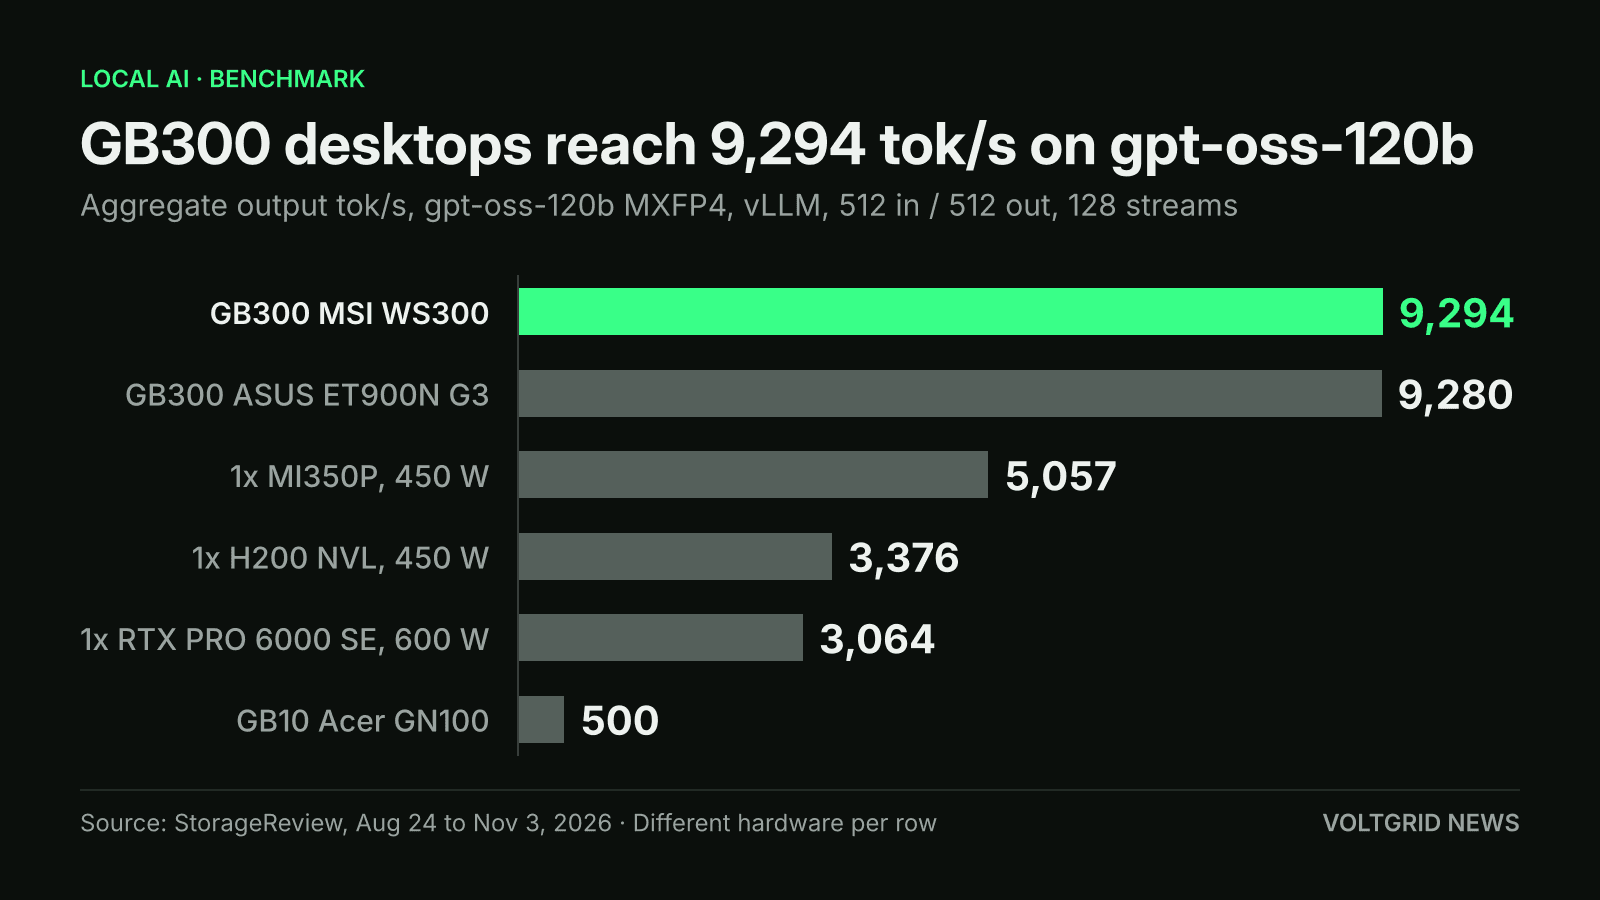
On gpt-oss-120b in StorageReview's 512 in, 512 out vLLM test at 128 streams, the GB300 desktops reach 9,294 and 9,280 tok/s.
Illustration (AI-generated)
The reason is where the weights sit. Each new token means reading the model's active weights again, so once a model fits, decode speed is limited mostly by memory bandwidth, StorageReview writes, though at many streams compute matters too: in StorageReview's matrix-math test the Station reached about 3.3 times the MI350P's BF16 rate. StorageReview read the Station's HBM at 6,869 GB/s in its own test, against 1,540 GB/s for one RTX PRO 6000 Server Edition, a card its table rates at 1.6 TB/s. A model larger than 252 GB spills into the 396 GB/s LPDDR5X. The rivals' best result came just below that line: MiniMax M3's 233 GB checkpoint barely fits, and four RTX PRO 6000s led it at 4 to 16 streams, while on GLM-5.2, at 433 GB, the Station led the four cards.
Four RTX PRO 6000s: faster at one setting, half the memory
StorageReview's four-card machine was a Dell PowerEdge XE7740 server with 600 W RTX PRO 6000 Server Edition cards of 96 GB each. On MiniMax M3 in NVFP4, with the same EAGLE3 speculative decoder as the Station, the cards matched the Station at one and two streams and led from four streams up to 1,181 against 940 at 16. At 32 streams the Station led, 1,041 against 759. StorageReview's MI350P review adds that the Station, the four cards and two MI350Ps stayed within 10 percent of each other through eight streams, so the four cards' lead from four to eight streams is small. With 8,192-token prompts the four cards also led, about 349 against 271 at four streams and 444 against 103 at eight.
On GLM-5.2, about 433 GB in NVFP4, the order reverses. The Station keeps about 215 GB of experts in Grace memory and served 35 tokens per second to one stream and 139 across 32, best-case figures from MTP speculative decoding; the four cards' decoder setting is not stated. The four cards, each offloading about 30 GB to host memory over PCIe, managed 9 and about 40. Voltgrid found no published four-card run of gpt-oss-120b.
Price is the other gap. None of the builders Voltgrid read, Exxact, BIZON, VRLA Tech, Puget and Central Computers, lists a fixed four-card price: VRLA Tech configures quad builds to the workload, and Puget's Quad GPU Rackmount shows $63,861.73 only with two Max-Q cards. VRLA Tech says four RTX PRO 6000s draw up to 2,400 W and typically need a dedicated 30 A, 208 V circuit. Puget's Threadripper PRO tower with two 300 W Max-Q cards and 256 GB of DDR5 costs $52,412.24 as configured, though those are not the cards StorageReview measured. StorageReview's two 600 W Server Edition cards ran DeepSeek V4 Flash in FP8, with 512-token prompts and answers at 32 streams, at 803 tokens per second in its Sept. 23 ASUS review and 829 in its Nov. 3 MI350P first look, against 1,766 for the Station. Our RTX PRO 6000 review covers the card.
How Speculative Decoding Shapes These Speed Figures
Speculative decoding speeds up token generation. A cheap draft mechanism guesses several tokens, and the full model checks them in one pass and keeps the longest run that matches its own output, NVIDIA's developer blog explains. The average tokens kept per pass is the acceptance length.
StorageReview forced that length to 3 tokens on the Station's MiniMax M3 and GLM-5.2 runs, so the Station's 1,041 and 139 tokens per second are best-case; real serving depends on how often the draft is right. The lab does not say whether the four-card or MI350P runs were forced the same way, so a lead or gap against the Station holds only if the decoder setting matches.
Two AMD MI350Ps: faster in a different format, and unpriced
StorageReview's Nov. 3 first look ran two 144 GB MI350P cards in a Dell PowerEdge R7725 server at 450 W. At 32 streams the pair reached 1,509 tokens per second on MiniMax M3 and 1,462 on GLM-5.3 Flash, against 1,041 and 828 for the Station. Those are not like-for-like: AMD's builds were MXFP4 and NVIDIA's NVFP4, the pair ran ROCm 7.2.3 with older vLLM images while the NVIDIA runs used the vLLM 26.08 container, the Station's MiniMax M3 figure used a forced acceptance length, and StorageReview does not state the pair's decoder setting. At one stream on GLM-5.3 Flash the Station led, 353 to 45. The pair holds 288 GB, two cards of 144 GB. Voltgrid found no public price: AMD's product page lists none, and Dell supports the card in its PowerEdge servers. AMD's deskside Threadripper Halo Station, with up to four MI350Ps, 576 GB of HBM3e and up to 2 TB of CPU RDIMM, 2.6 TB in all by AMD's count, is listed as coming in 2027.
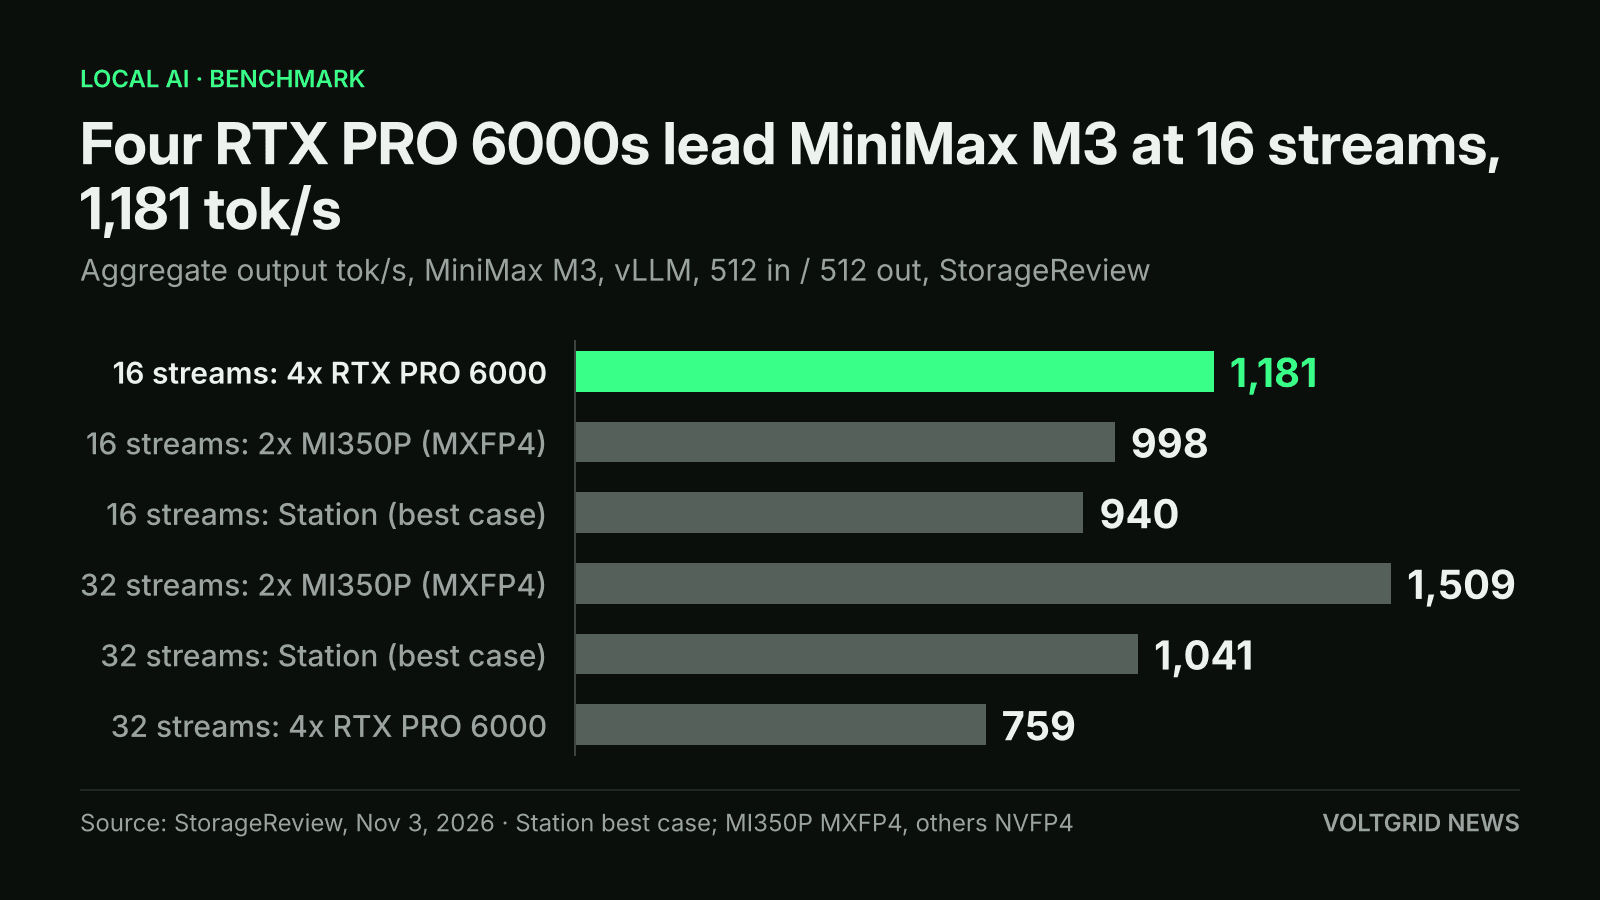
Four RTX PRO 6000s lead MiniMax M3 at 16 streams with 1,181 tok/s against 940 for the Station, then trail at 32 streams, 759 against 1,041; the Station's figures are best case and the MI350P ran MXFP4.
Illustration (AI-generated)
Mac and Strix Halo clusters: more memory for less, speed unmeasured
Apple's Mac Studio M5 Ultra with 512 GB of unified memory at 1.2 TB/s costs at least $22,299, MacRumors reported on Oct. 28, and first orders arrive Dec. 3, according to Digital Trends. Two hold 1,024 GB for $44,598 by Voltgrid's arithmetic, under half Exxact's price. MacRumors reported that Meta's Muse Spark Open model runs on two such Macs with Apple's MLX framework, without a speed. The only independent M5 Ultra figure Voltgrid found is BGR's: its 256 GB unit "generally got closer to 55 tokens per second" on a 4-bit MLX build of Qwen 3.8 27B in LM Studio, an informal single-machine figure with no stated concurrency. Our Mac Studio review and our 512 GB report have the details.
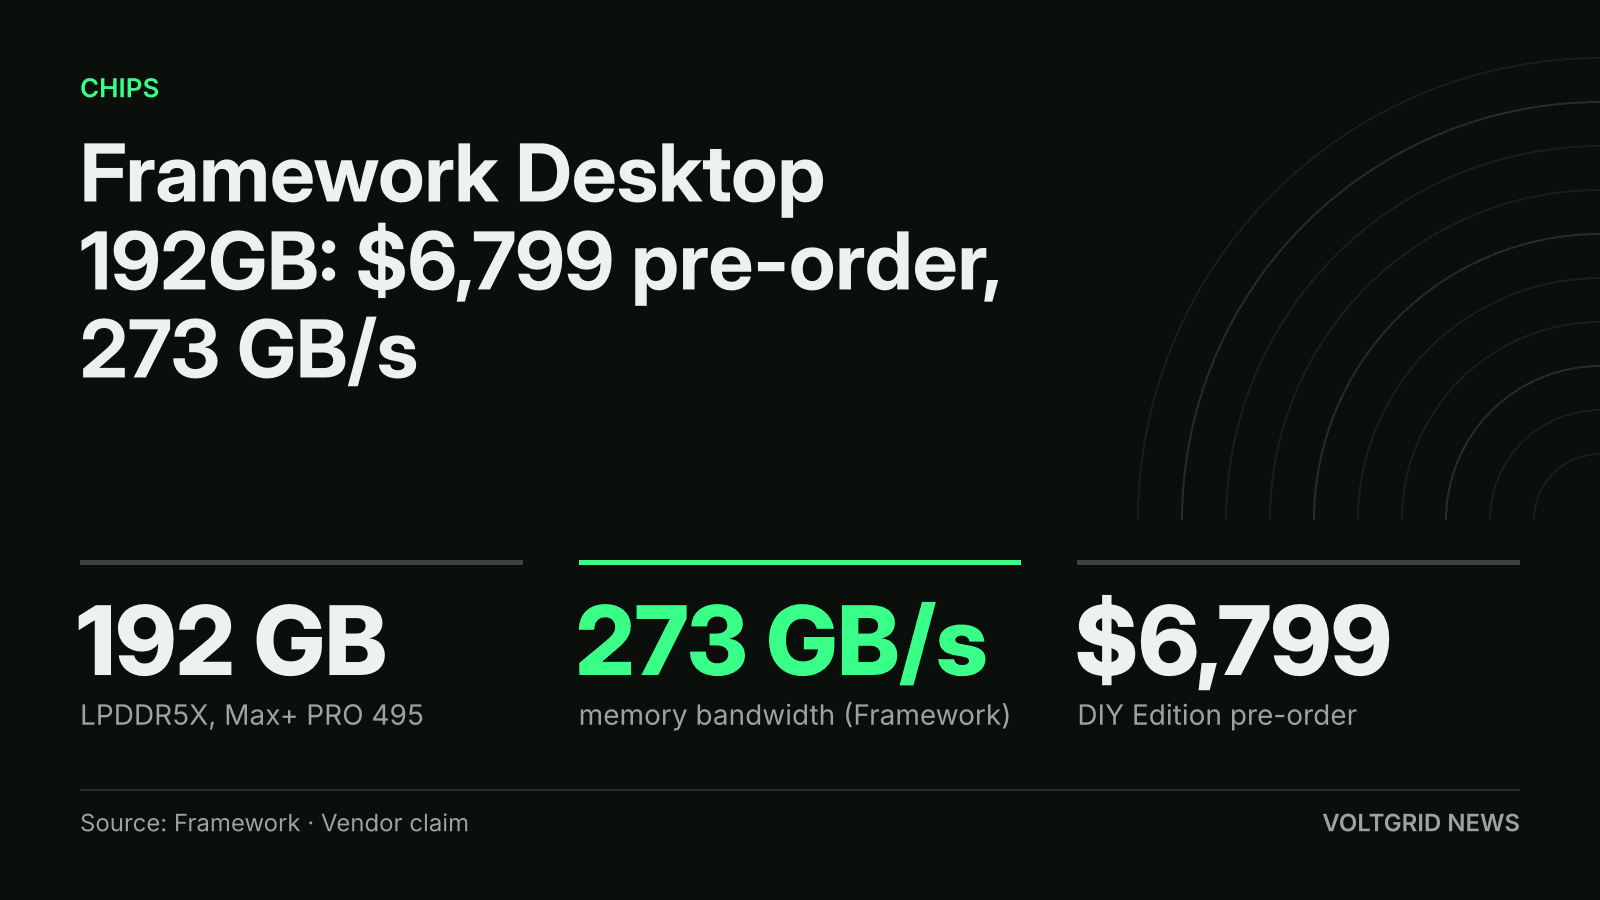
Boxes on AMD's Ryzen AI Max+ PRO 495 cost less still. Framework's 192 GB Desktop is $6,799 without storage, with Batch 3 shipping in December after two sold-out batches. GMKtec's EVO-X5 Pro is $6,799 with 2 TB and in stock. Four of either hold 768 GB for $27,196, four times $6,799 by Voltgrid's arithmetic, though only GMKtec's price includes storage. Each box has 273 GB/s of memory bandwidth, "up to" that figure in GMKtec's wording. Voltgrid found no published multi-user result for a 495 box or a cluster of them. The nearest measured relative, AMD's 128 GB Ryzen AI Halo, which uses the Ryzen AI Max+ 395, served gpt-oss-120b at 222 aggregate tokens per second at batch 64, with 256-token prompts and answers and precision unstated, against 701 for a DGX Spark in StorageReview's July review.
Memory added across boxes is not one pool: a model split across machines sends its work over network links. StorageReview wrote that, in results others have published, per-user throughput on clusters beyond two Sparks can drop into single-digit tokens per second for models large enough to need them, though it did not measure those clusters itself. Until someone does, the Mac and Strix Halo clusters are bigger only on paper.
GB10 pairs: cheaper and measured, but a different class
Two GB10 boxes joined by one 200GbE link are the cheapest priced option with a multi-user measurement Voltgrid found. In StorageReview's May 11 cluster test, gpt-oss-120b in pipeline-parallel mode peaked at 463.97 output tokens per second on two Dell units, 497.26 on two GIGABYTE units and 504.88 on two HP units, at batch 64; the lab did not state precision or prompt lengths. That harness differs from the Station sweep, so its numbers do not sit beside 9,280. By Voltgrid's arithmetic, a GIGABYTE pair at $7,312 a unit (CDW, Nov. 2, 4 TB) costs $14,624, the lowest of the three, an HP ZGX Nano pair at $7,399 (HP Store via Notebookcheck, Oct. 5, 4 TB) $14,798, and a Dell Pro Precision GB10 pair at $7,967 (Dell.com, Nov. 2, 2 TB) $15,934, each with 256 GB. Notebookcheck also lists the HP at $4,759 on Amazon. StorageReview called a two-box cluster a development and learning platform. Our GB10 comparison and DGX Spark review cover the boxes.
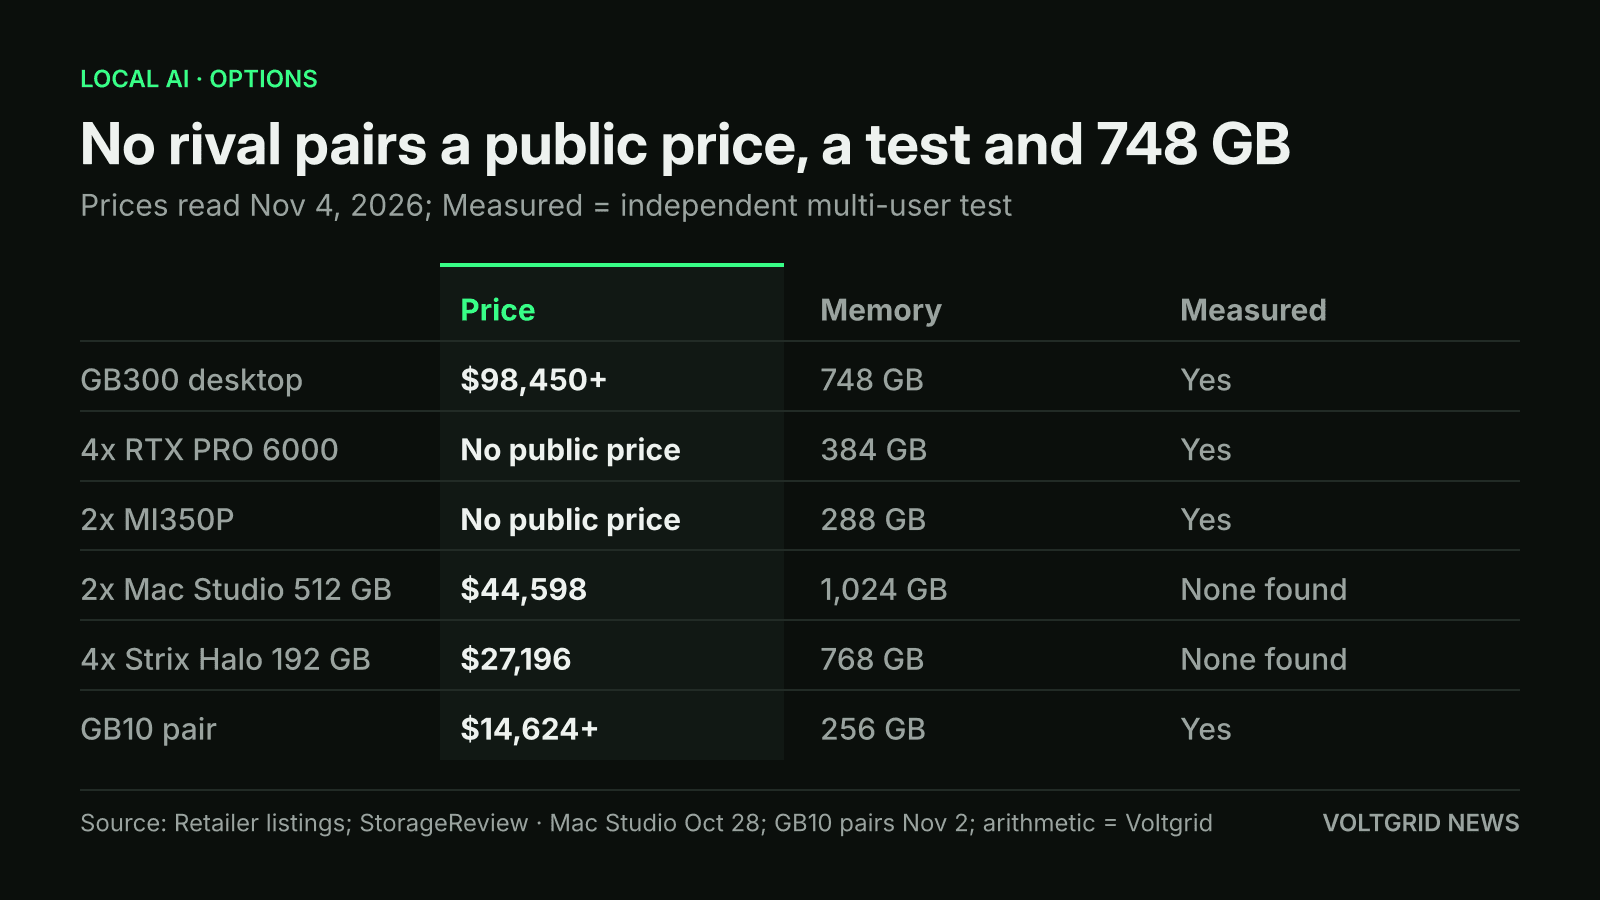
Only the GB300 desktop combines a public price, a measured multi-user test and 748 GB of memory.
Illustration (AI-generated)
What the money buys
Per gigabyte, the cheaper machines win, by Voltgrid's arithmetic. Exxact's $98,450 over 748 GB, 252 GB of HBM3e at 7.1 TB/s plus 496 GB at 396 GB/s, is $131.62 per GB. A $22,299 Mac Studio with 512 GB of unified memory at 1.2 TB/s is $43.55 per GB, and a $6,799 Strix Halo box with 192 GB at 273 GB/s is $35.41. Those are single machines, not clusters, and storage differs: Exxact states none, Framework includes none and GMKtec includes 2 TB.
Measured speed gives two ratios from two different tests. MSI's WS300 at Newegg's $99,999 costs $10.76 per output token per second of its 9,294 on gpt-oss-120b, in StorageReview's 512/512 vLLM test at 128 streams. The HP pair at $14,798 costs $29.31 per token per second of its 504.88, in the May 11 cluster test at batch 64. Both are Voltgrid's arithmetic, and because the tests differ, they are not a ranking.
Renting a GB300 Instead of Buying
Oracle lists a GB300 GPU at $18.00 an hour, a B300 at $15.00 and an RTX PRO 6000 at $4.50, its list on-demand rates as read by Voltgrid's GPU cloud price tracker at 02:00 UTC on Nov. 4. By Voltgrid's arithmetic on those list prices, with no matched throughput, Exxact's $98,450 divided by $18.00 is 5,469 rented hours, about 7.5 months around the clock at roughly 730 hours a month, and Dell's $160,195 is 8,900 hours, about 12.2 months. Four rented RTX PRO 6000s cost $18.00 an hour, four times $4.50, the same as one GB300. The tracker shows on-demand list prices only; committed-use, reserved and spot rates are not shown. Oracle's GB300 is the data-center part, not the desktop chip, the sum leaves out the owned machine's power, space and staff, and a rented GPU is off premises, which rules it out for this job.
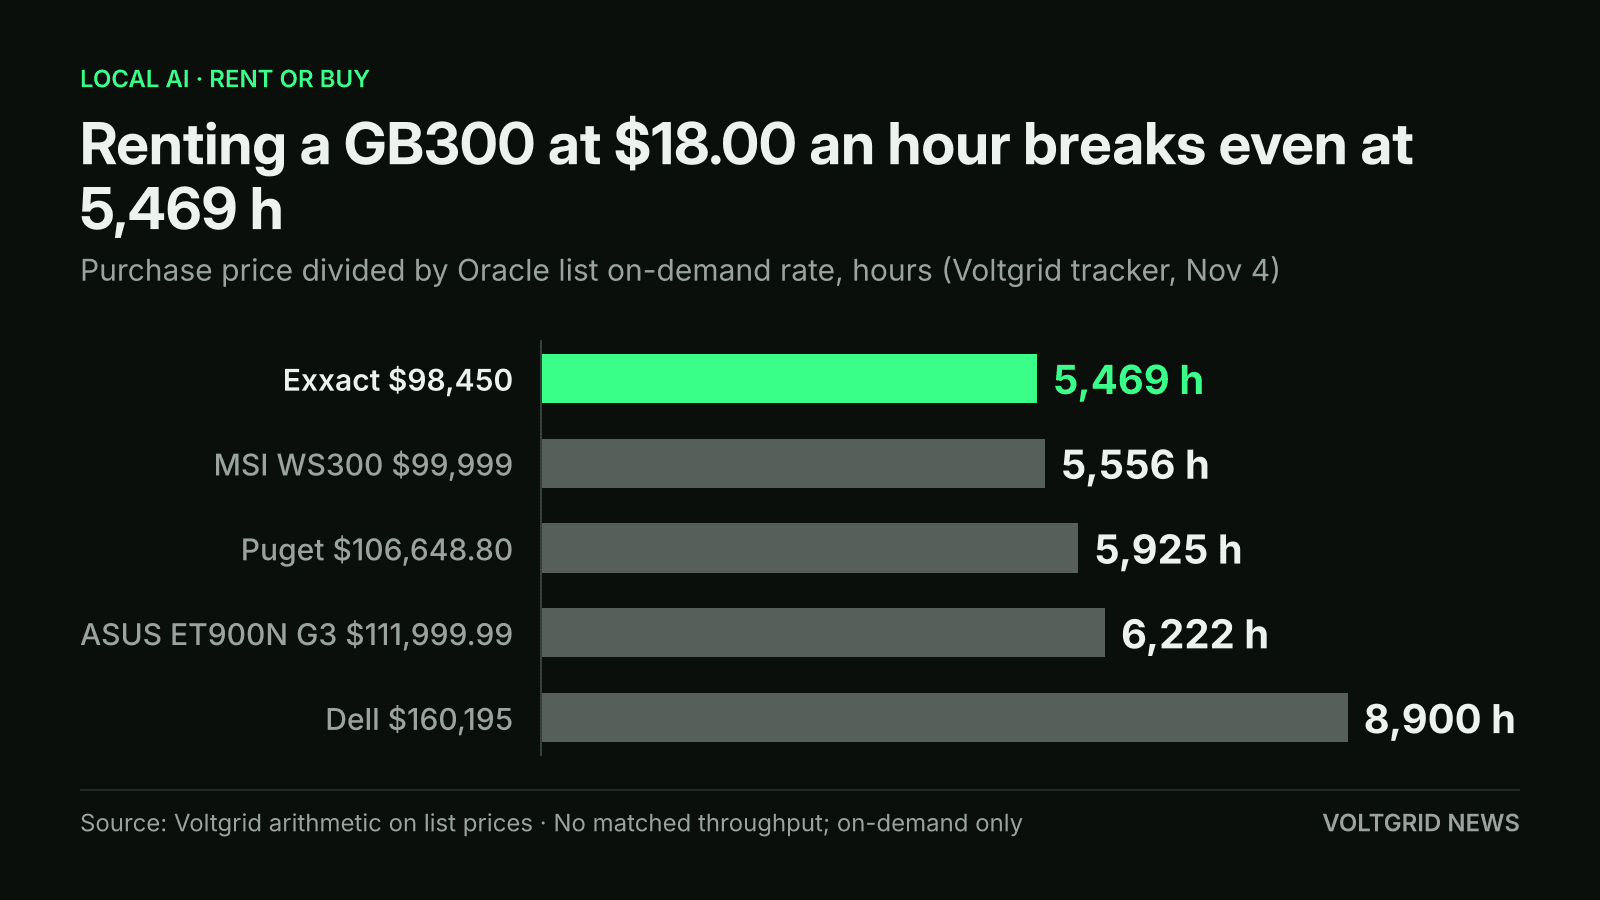
Voltgrid arithmetic on list prices, with no matched throughput and on-demand rates only: Exxact's $98,450 equals 5,469 rented GB300 hours.
Illustration (AI-generated)
Which DGX Station Alternative to Buy
A team serving gpt-oss-120b, or any model that sits well inside 252 GB, to dozens of users has the best-measured option in a GB300 desktop; MiniMax M3, at 233 GB, is under that line, and four cards led it at 4 to 16 streams. StorageReview found the ASUS and MSI builds within 2% of each other on 24 of 28 tests; that says nothing about price, and the lab did not measure Exxact's build. Exxact's $98,450 was the lowest confirmed starting price Voltgrid found on Nov. 4; Supermicro's reported $92,887.47 is lower but unconfirmed.
A team whose model sits close to 252 GB, with MiniMax M3's 233 GB checkpoint as the measured case, that serves 4 to 16 streams and already has rack space and 208 V power can ask builders for a four-card quote. It gets half the memory, and the Station led once a model needed about 215 GB of Grace memory, as GLM-5.2 did.
A developer or small team that needs capacity more than many-user speed can buy a 512 GB Mac Studio for $22,299 or a 192 GB Strix Halo box for $6,799, knowing Voltgrid found no multi-user measurement of either. The first 512 GB Mac measurements should follow the Dec. 3 deliveries.
A team that needs Station-class speed only part of the time can rent a GB300 at $18.00 an hour for up to about 5,469 hours before buying wins, if its data may leave the building. GB10 pairs remain learning machines. Next to watch are StorageReview's 600 W MI350P rerun and DGX Station for Windows, which NVIDIA expects from partners in December.
How it compares
Full table| Product | Memory | Bandwidth | AI compute | Measured speed | Price |
|---|---|---|---|---|---|
| ASUS ExpertCenter Pro ET900N G3ASUS (NVIDIA DGX Station GB300 platform) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[1] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5X)[1] | up to 20 PFLOPS AI performance (ASUS gives no precision or sparsity label) (sparse)[2] | GPT-OSS-120B MXFP4, vLLM, 512/512, 1-128 streams: 9,280 aggregate output tok/s at 128 streams; 5,023 on 8,192/1,024 (StorageReview, ASUS-supplied unit, no add-in GPU)[3] | $111,999.99 at Central Computers, US (model ET900N G3-2SSD-V2, request a quote, unavailable online, read Nov 4, 2026); no ASUS list price[4] |
| HP ZGX Fury AI StationHP | 252 GB HBM3e GPU + 496 GB LPDDR5x CPU (4x 128 GB SOCAMM); 748 GB unified[5] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5x)[5] | — | Two-unit cluster with an ASUS ET900N G3 over two 400G DACs: GLM-5.3 NVFP4 5,018 output tok/s at 256 streams, 512/512, vLLM 0.27.1 TP2 with MTP (StorageReview); no single-unit HP result[6] | Japan list price from 28,490,000 yen incl. tax (sales from Oct 27, 2026); no US list price published[7] |
| NVIDIA DGX StationNVIDIA (systems built by ASUS, Dell, GIGABYTE, HP, MSI, Supermicro and Exxact) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[8] | GPU HBM3e 7.1 TB/s; CPU LPDDR5X 396 GB/s; NVLink-C2C 900 GB/s between them[8] | 15 PFLOPS FP4 (without sparsity)[8] | gpt-oss-120b MXFP4, stock vLLM, 512/512 chat workload: 9,280 output tok/s at 128 streams (5,023 on 8,192/1,024 prompts), single GB300 (StorageReview, ASUS ExpertCenter Pro ET900N G3)[9] | No NVIDIA list price; lowest US partner listing read Nov 4, 2026: Exxact Valence VWS-158270643 from $98,450 (Tom's Hardware found $94,930 in Aug); Dell Pro Precision with GB300 lists $160,195[10] |
| NVIDIA RTX PRO 6000 Blackwell Workstation EditionNVIDIA (sold through PNY, TD SYNNEX and workstation makers) | 96 GB[11] | 1,792 GB/s[11] | 4,000 AI TOPS (FP4, with sparsity) (sparse)[11] | gpt-oss-120b MXFP4, stock vLLM, 512/512 chat workload: 3,064 output tok/s at 128 streams (1,169 on 8,192/1,024 prompts); Server Edition at 600W (StorageReview)[9] | $16,000 on NVIDIA's US marketplace (Workstation Edition), listed out of stock[12] |
| Apple Mac Studio (M5 Ultra)Apple | up to 512 GB unified (96 GB on 30-core M5 Ultra; 256 GB or 512 GB on 36-core/80-core M5 Ultra)[13] | 1.2 TB/s[13] | — | Qwen 3.8 27B 4-bit MLX in LM Studio: about 55 tok/s on M5 Ultra (36-core, 256 GB) vs about 40 on M3 Ultra (BGR)[14] | $22,299 minimum with 512 GB ($6,799 36-core CPU/80-core GPU M5 Ultra config plus $15,500 memory upgrade; Oct 28, 2026)[15] |
| NVIDIA RTX Spark (N1X) PCsNVIDIA (MediaTek collaborated on the custom CPU design) | Up to 128 GB LPDDR5X (20-core CPU / 6,144-core GPU version); up to 64 GB (18-core / 5,120-core laptop version)[16] | Up to 300 GB/s: LPDDR5X-9400 on a 256-bit bus (NVIDIA's product page lists no bandwidth)[17] | — | gpt-oss:20b via Ollama in a Codex CLI coding agent, 64K context: 58.5 tok/s generation, 3 of 4 tasks passed (Dell XPS 16, 20-core N1X, 64 GB; StorageReview)[18] | Laptops from $2,599; pricing and configurations vary by region[19] |
| ASUS Ascent GX10ASUS | 64 GB or 128 GB LPDDR5X-8533 unified[20] | 273 GB/s (8533 MT/s), as listed by StorageReview; ASUS's spec page states no bandwidth[21] | Up to 1 PFLOP FP4 (GB10; NVIDIA's footnote: theoretical, using the sparsity feature). ASUS's pages say 1 petaFLOP / FP4 with no sparsity label (sparse)[22] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 70 tok/s at batch 1 rising to 680 tok/s aggregate at batch 64 (StorageReview)[21] | $5,999 (128 GB, 1 TB, GX10-GG0010BN, ASUS eShop US, Oct 30, 2026)[23] |
| Dell Pro Precision with GB10 (model FCM1253; launched as Dell Pro Max with GB10)Dell | 128 GB LPDDR5x up to 8533 MT/s onboard (64 GB option also listed)[24] | 273 GB/s (128 GB LPDDR5x, 256-bit)[25] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 68.57 tok/s at batch 1 rising to 670.83 tok/s aggregate at batch 64 (StorageReview)[26] | $7,967 (128 GB, 2 TB Gen4 QLC SSD default config, Dell.com US, read Nov 2, 2026 16:40 UTC)[24] |
| Framework Desktop (Ryzen AI Max+ PRO 495, 192 GB)Framework | 192 GB LPDDR5X-8533 soldered[27] | 273 GB/s (256-bit)[27] | — | — | $6,799 (Max+ PRO 495 192 GB DIY Edition pre-order, Nov 3, 2026; storage not included)[28] |
| GIGABYTE AI TOP ATOMGIGABYTE | 128 GB unified system memory[29] | 273 GB/s (LPDDR5x-8533, 256-bit)[30] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 60.71 tok/s at batch 1 rising to 649.62 tok/s aggregate at batch 64 (StorageReview)[30] | $7,312.00 advertised at CDW US against a $7,999.99 list (128 GB, 4 TB, ATAGB10-9000; read Nov 2, 2026)[31] |
| GMKtec EVO-X5 Pro AI Mini PCGMKtec | 192 GB LPDDR5X-8533 onboard (8 x 24 GB, non-upgradeable); up to 160 GB allocatable as VRAM[32] | Up to 273 GB/s[33] | — | GMKtec Laboratory table: GLM-5.3-Flash UD-IQ4_XS (146.05 GB) decode 17.79 tok/s, prefill 70.18, TTFT 14.71 s; Qwen3.8-Flash-Next ROCmFP4-FAST (93.48 GB) decode 45.08 tok/s[32] | $6,799 (192 GB/2 TB) and $7,099 (192 GB/4 TB), GMKtec US store, Nov 2, 2026[32] |
| HP ZGX Nano AI Station (G1n)HP | 128 GB coherent unified system memory[34] | 273 GB/s (128 GB LPDDR5x)[35] | GB10: up to 1 PFLOP FP4, theoretical, using the sparsity feature; HP and reviewers list 1,000 TOPS FP4 (sparse)[22] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.6 tok/s at batch 1 rising to 722.9 tok/s aggregate at batch 64 (StorageReview)[36] | $7,399.00 at the HP Store for the 4 TB model; $4,759 on Amazon (Notebookcheck, review updated Oct 5, 2026)[37] |
| Lenovo ThinkStation PGXLenovo | 128 GB LPDDR5X unified (256-bit)[38] | 273 GB/s[38] | — | — | about $4,100 for the 1 TB configuration (Mar 2026)[39] |
| MSI EdgeXpert (MS-C931)MSI | 64 GB or 128 GB LPDDR5x unified (256-bit)[40] | 273 GB/s[40] | 1 PFLOPS FP4 (sparse)[40] | — | No list price; MSI sells via quote (Get a quote)[40] |
| NVIDIA DGX SparkNVIDIA (partner GB10 systems from Acer, ASUS, Dell, GIGABYTE, HP, Lenovo and MSI) | 128 GB; a 64 GB configuration is sold only through OEM partners[22] | 273 GB/s[22] | Up to 1 PFLOP FP4 (theoretical, using the sparsity feature) (sparse)[22] | Qwen 3.8 27B (dense) with multi-token prediction: decode of about 20 tokens/s, with time-to-first-token staying interactive out to the full 262K context.[41] | $6,950.00 (128 GB, 4 TB) on NVIDIA's enterprise marketplace with an Add To Cart button in a copy cached 07:59 UTC on 2026-10-31; stock unverified (listed out of stock on 2026-10-21); 64 GB partner systems from $4,999[42] |
| NVIDIA DGX Spark 64 GBNVIDIA (sold by Acer, ASUS, Dell, Gigabyte, HP and MSI) | 64 GB LPDDR5X unified (two units pool 128 GB over ConnectX-7)[43] | 273 GB/s (256-bit; NVIDIA spec table covers both 64 GB and 128 GB)[22] | 1 PFLOPS FP4 (sparse; NVIDIA spec table covers both memory configurations)[22] | — | from $4,999 (partner systems, Oct 2026; no Founders Edition)[43] |
| AMD Ryzen AI Halo Developer PlatformAMD | 128 GB LPDDR5x-8000 unified[44] | 256 GB/s[44] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL 256/256: 222 tok/s aggregate at batch 64 vs 701 on DGX Spark (StorageReview)[45] | $3,999 with 2 TB SSD (Jul 2026)[45] |
| Framework Desktop (Ryzen AI Max+ 395)Framework | 128 GB LPDDR5x-8000 soldered (32 GB and 64 GB options)[46] | 256 GB/s[47] | — | gpt-oss-120b MXFP4 in LM Studio (out-of-the-box setup): roughly 45 tok/s (ServeTheHome; Ryzen AI Max+ 395, 128 GB, Windows 11 Pro)[48] | $3,449 (DIY Edition, Max+ 395 with 128 GB, system only; out of stock, Nov 3, 2026)[49] |
| Acer Veriton GN100 AI Mini WorkstationAcer | 128 GB LPDDR5x coherent unified[50] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.65 tok/s at batch 1 rising to 713.18 tok/s aggregate at batch 64 (StorageReview)[51] | from $3,999 in North America (announced Sep 3, 2025; prices vary by region)[50] |
| ASRock Industrial AI BOX-A395ASRock Industrial | 128 GB LPDDR5X-8000 soldered[52] | — | — | AgentSTH V7, 32 threads: 15% ahead of the next-closest Ryzen AI Max+ 395 box (single-core within 1%); estimated SPEC CPU2026 int rate: top of a 44% spread across four 395 systems; measured by ServeTheHome, Ubuntu 26.04[53] | — |
| Dell Pro Precision with GB300 (model FCT6263; announced as Dell Pro Max with GB300)Dell | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU[54] | — | — | — | $160,195.00 (Dell.com US default config FCT6263 with RTX PRO 2000 display GPU, read Nov 4, 2026); RTX PRO 6000 Workstation Edition option adds $13,560[54] |
| GMKtec EVO-X2 AI Mini PCGMKtec | 64 GB or 128 GB onboard LPDDR5X-8000 (non-upgradeable)[55] | — | — | — | $3,499.99 (128 GB/1 TB, GMKtec US store, Oct 30, 2026; listed against $3,999.99)[55] |
| HP Z2 Mini G1a WorkstationHP | up to 128 GB unified, up to 96 GB assignable to the GPU, up to 8000 MT/s[56] | — | up to 50 NPU TOPS[56] | gpt-oss-120b GGUF (63.39 GB, full GPU offload) in LM Studio: close to 40 tok/s (StorageReview)[57] | $4,781 list for StorageReview's review configuration; about $3,300 street (B&H top spec with 2 TB SSD at $3,342.65, Aug 2025)[57] |
| Microsoft Surface RTX Spark Dev BoxMicrosoft | 128 GB unified memory[58] | — | up to 1 PFLOP of AI compute (Microsoft; precision and sparsity not stated on the page) (sparse)[58] | — | From $5,999.99 (Microsoft Store US, pre-order, read Nov 1, 2026)[58] |
| MSI XpertStation WS300MSI (NVIDIA DGX Station platform) | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU (748 GB coherent)[59] | — | — | StorageReview vLLM: gpt-oss-120b MXFP4 9,294 output tok/s at 128 streams (512/512), 5,038 on 8,192/1,024; MiniMax M3 NVFP4 1,041 at 32 streams with EAGLE3-GQA at a forced acceptance length of 3 (best-case)[59] | $99,999.00 'Start From' at Newegg US (model WS300T60L, 2x 2 TB NVMe RAID1), sold by Newegg as a request-a-quote listing (read Nov 4, 2026)[60] |
| Tenstorrent TT-QuietBox 2 (Blackhole)Tenstorrent | 128 GB GDDR6 on the accelerators + 256 GB DDR5-5600 system memory[61] | — | — | — | $9,999 (Oct 30, 2026)[61] |
| WiCi One (RTX 5060 Ti edition)WiCi | 16 GB GDDR7 VRAM; 1 TB NVMe 4 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[62] | — | — | — | $2,599 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout. Early-access price was $1,999 (Notebookcheck, Engadget, Sep 2026)[62] |
| WiCi One (RTX 5090 edition)WiCi | 32 GB GDDR7 VRAM; 4 TB NVMe 5 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[62] | — | — | — | $9,999 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout[62] |
Italic values are reported by an outlet or measured by an independent lab; the rest come from the maker. Measured speeds use different models, quantizations and tools, so read each with its source rather than against the others. Voltgrid News does not test hardware itself.
Sources (62)
- [1] ASUS
- [2] ASUS
- [3] StorageReview
- [4] Central Computers
- [5] HP
- [6] StorageReview
- [7] HP Japan
- [8] NVIDIA
- [9] StorageReview
- [10] Exxact
- [11] NVIDIA
- [12] NVIDIA
- [13] Apple
- [14] BGR
- [15] MacRumors
- [16] NVIDIA
- [17] ServeTheHome
- [18] StorageReview
- [19] NVIDIA
- [20] ASUS
- [21] StorageReview
- [22] NVIDIA
- [23] ASUS eShop
- [24] Dell
- [25] HotHardware
- [26] StorageReview
- [27] Framework Blog
- [28] Framework
- [29] GIGABYTE (PR Newswire)
- [30] StorageReview
- [31] CDW
- [32] GMKtec
- [33] GMKtec
- [34] HP
- [35] HotHardware
- [36] StorageReview
- [37] Notebookcheck
- [38] Lenovo PSREF
- [39] ServeTheHome
- [40] MSI
- [41] Tom's Hardware
- [42] NVIDIA Marketplace
- [43] NVIDIA Blog
- [44] AMD
- [45] StorageReview
- [46] Framework
- [47] Framework Blog
- [48] ServeTheHome
- [49] Framework
- [50] Acer
- [51] StorageReview
- [52] ServeTheHome
- [53] ServeTheHome
- [54] Dell
- [55] GMKtec
- [56] HP
- [57] StorageReview
- [58] Microsoft
- [59] StorageReview
- [60] Newegg
- [61] Tenstorrent
- [62] WiCi
Sources
- 01AI Deployment & Inference SystemsPuget Systems · pugetsystems.com
- 02Exxact Valence NVIDIA DGX Station - 1x NVIDIA GB300 Grace Blackwell Ultra Desktop Superchip - VWS-158270643Exxact · exxactcorp.com
- 03NVIDIA DGX Spark Cluster Review: Distributed Inference on Dell, GIGABYTE, and HPStorageReview · storagereview.com