NVIDIA RTX PRO 6000 Review: 600W Card Serves gpt-oss-120b at 3,064 tok/s
StorageReview's vLLM runs put one 600W RTX PRO 6000 Server Edition at 3,064 tok/s on gpt-oss-120b, a third of a GB300 DGX Station. Its 96 GB holds 120B-class models; the 300W Max-Q gives up about 9% on Llama 3.1 8B (llama.cpp).
Local AI DeskEdited by Ege Erten
9 min readAI-assisted
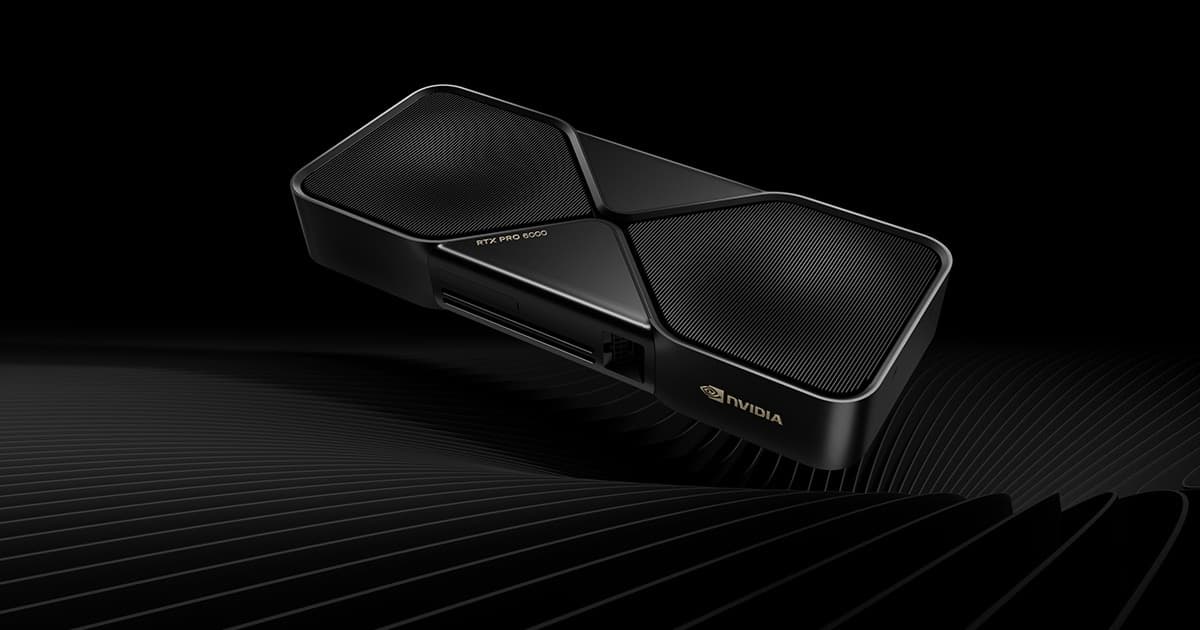
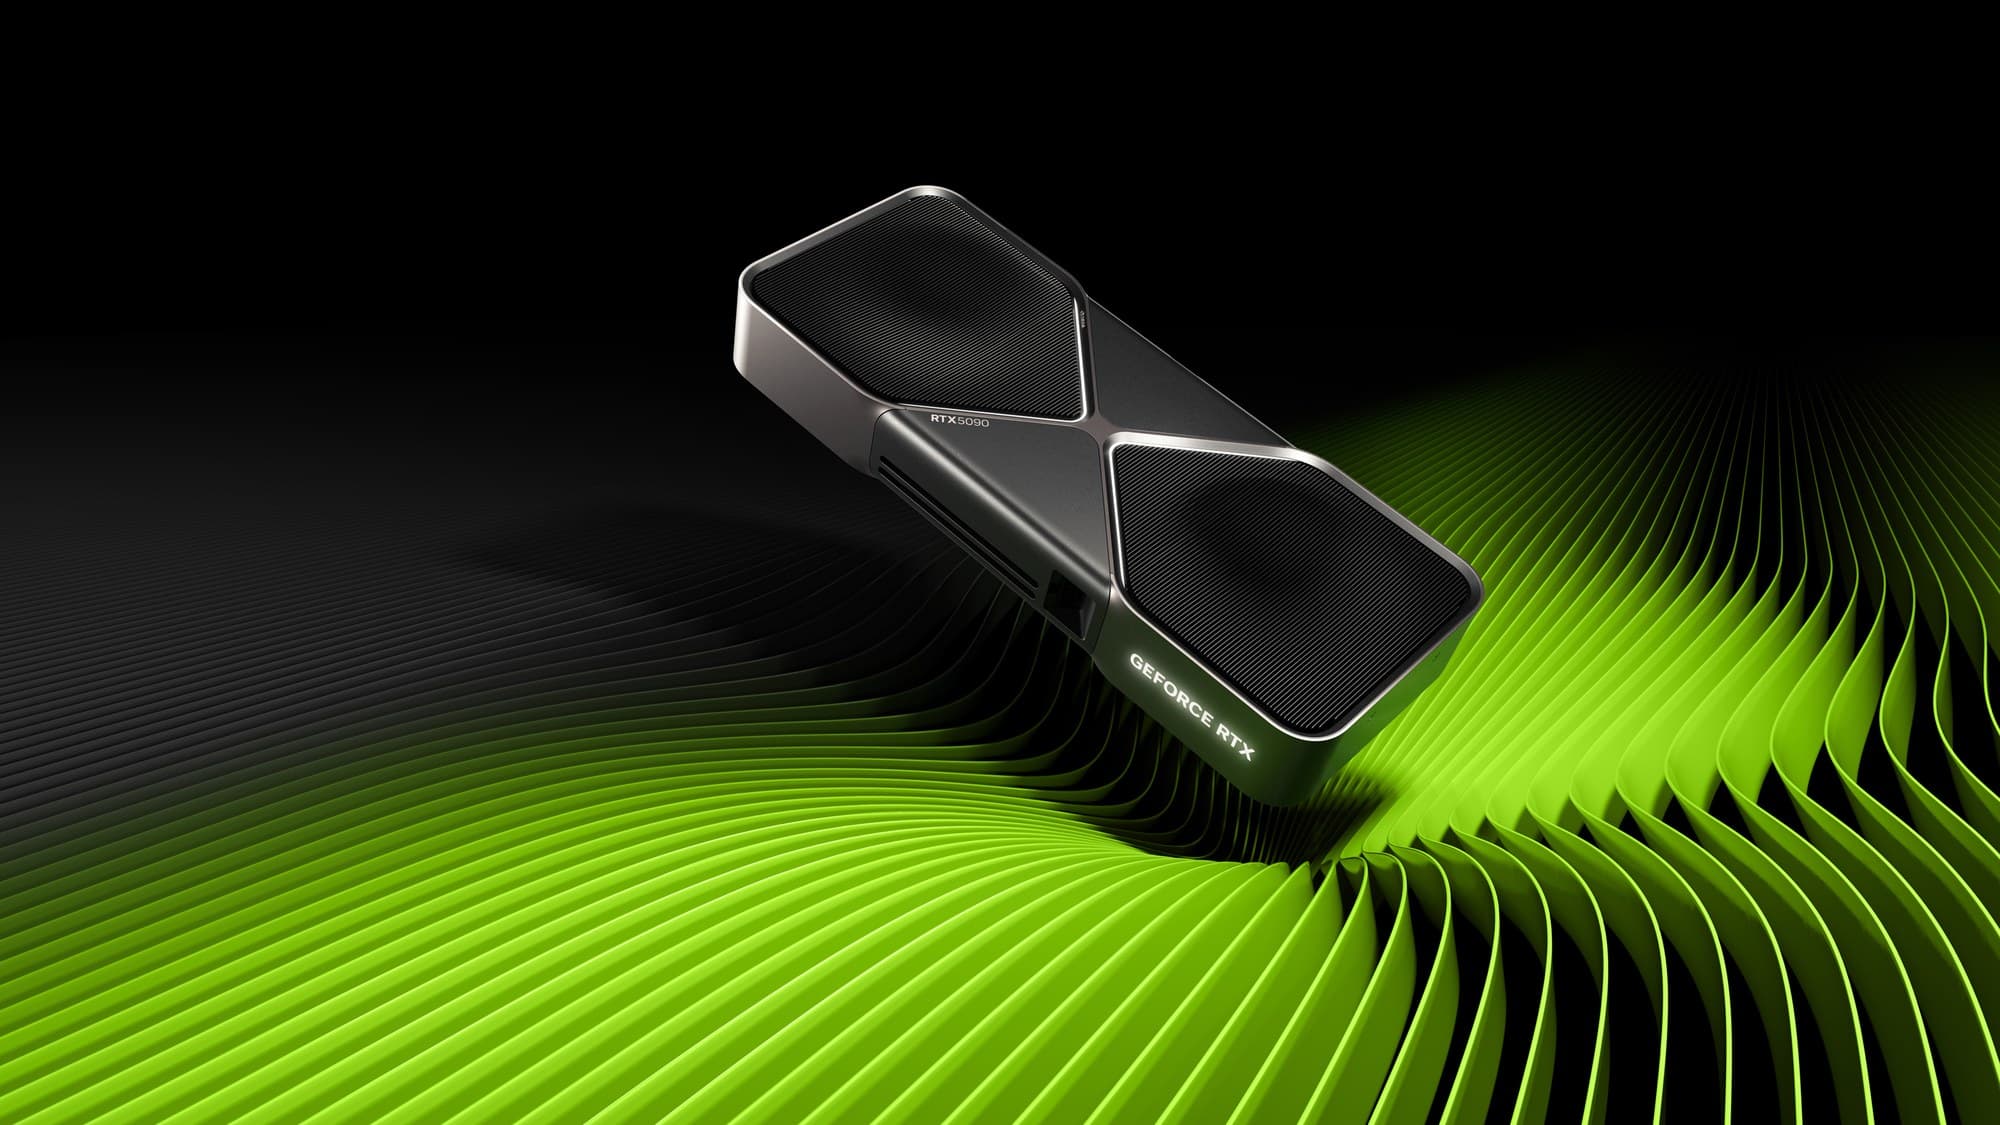
NVIDIA's product-page image of the RTX PRO 6000 Blackwell Workstation Edition, the 600W fan-cooled card with 96 GB of GDDR7.
Image: NVIDIA
Source · Press image from the NVIDIA product page, used for news reporting.
One NVIDIA RTX PRO 6000 Blackwell Server Edition, running at 600W, served gpt-oss-120b at 3,064 output tokens per second across 128 streams in StorageReview's vLLM test published Nov. 3, 2026. That is about a third of the 9,280 an ASUS ExpertCenter Pro ET900N G3 with a GB300 chip reached on the same harness.
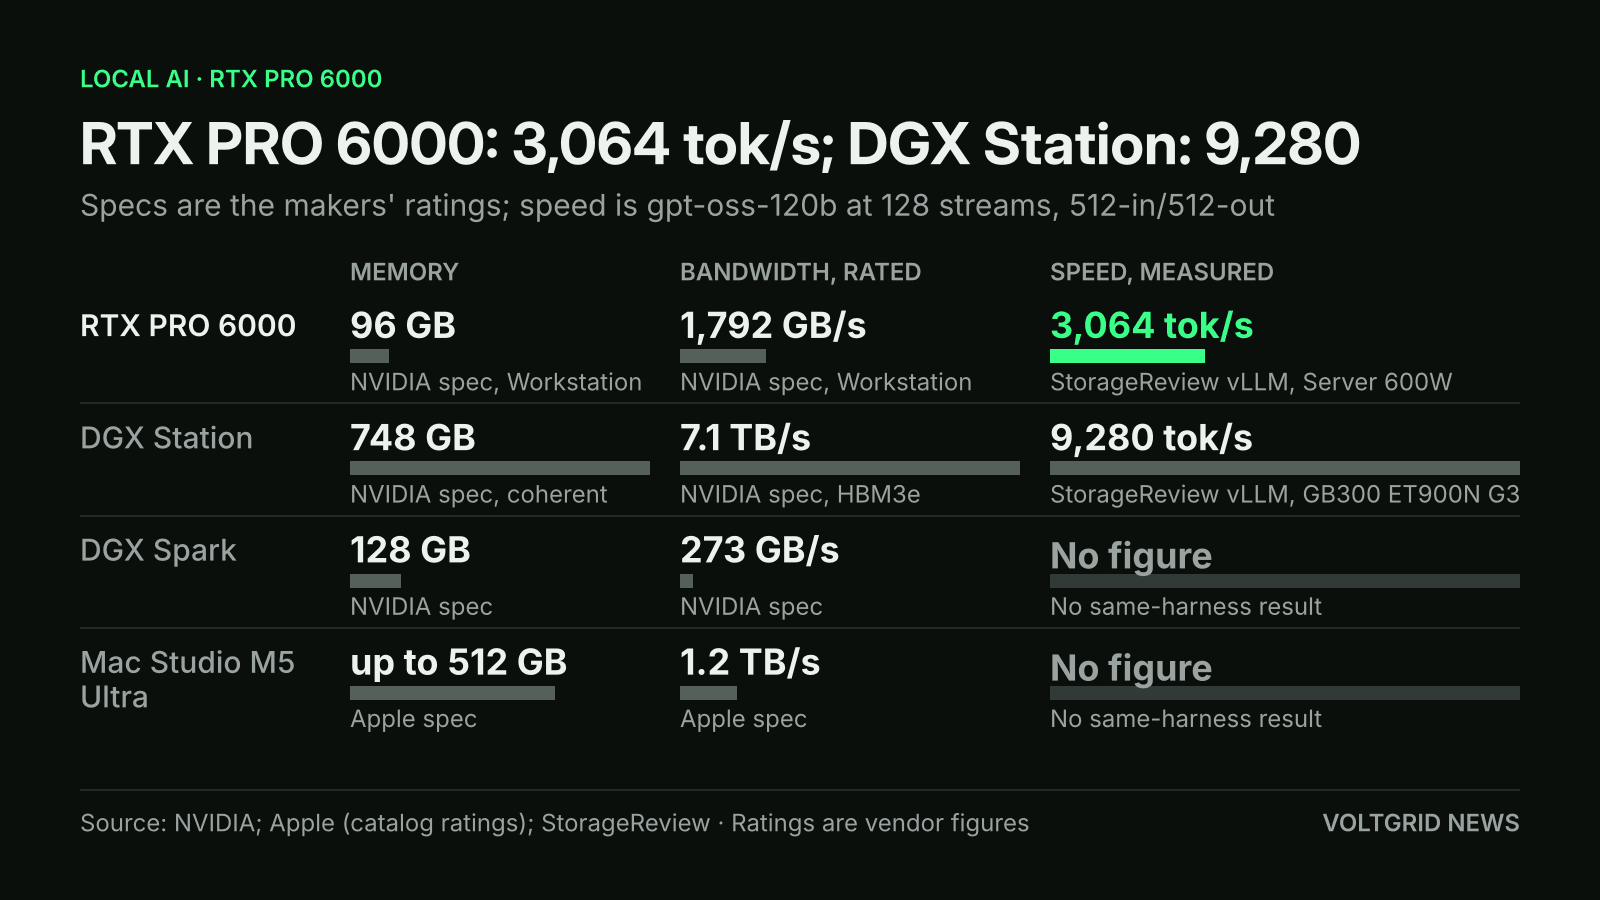
StorageReview's vLLM run puts one RTX PRO 6000 Server Edition at 3,064 tok/s and a DGX Station at 9,280; memory and bandwidth bars are the makers' ratings, and the Spark and Mac have no same-harness speed.
Illustration (AI-generated)
The card's case does not rest on speed. It rests on 96 GB of memory in one PCIe slot. That capacity lets a single card hold OpenAI's 120-billion-parameter open model with room left for a large context cache. The RTX 5090 shares its GB202 chip but has 32 GB. This review sets NVIDIA's specifications against what StorageReview and Gamers Nexus measured on three editions of the card: the 600W Workstation Edition, the 300W Max-Q Workstation Edition and the passive Server Edition. Voltgrid did not test the card. Every figure below names its edition, its power limit and the software that produced it, because the outlets used different tools.
What's new
NVIDIA announced the RTX PRO 6000 Blackwell at GTC on March 18, 2025, as the successor to the RTX 6000 Ada. Partners began shipping in April and May 2025. NVIDIA's product page lists the Workstation Edition with 96 GB of GDDR7 memory with error correction, 1,792 GB/s of bandwidth, a 600 W maximum power draw and a dual-slot board 12.0 inches long on PCIe 5.0 x16.
Memory is the main change. The RTX 5090, built on the same GB202 chip, stops at 32 GB. Gamers Nexus counted 32 memory modules of 3 GB each on its teardown board, which makes 96 GB. The 512-bit bus is NVIDIA's figure.
The chip is a fuller GB202. NVIDIA enables 24,064 CUDA cores, against 21,760 on the RTX 5090, Gamers Nexus noted. NVIDIA quotes 4,000 AI TOPS, a theoretical FP4 figure that assumes sparsity. StorageReview's matrix-multiply test, which measures sustained rather than peak math, found 419 TFLOPS in BF16, 820 in FP8 and 1,634 in block-scaled FP4 on the 600W Server Edition.
The family is new too. The same silicon and memory ship as a 600W Workstation Edition with fans, a 300W Max-Q Workstation Edition for multi-card towers, and a passive Server Edition that StorageReview lists as configurable from 300 to 600W. NVIDIA also offers Multi-Instance GPU, which splits one card into up to four 24 GB slices, according to NVIDIA's datasheet.
What it solves
Memory bandwidth decides how fast a model writes once it fits. Memory capacity decides whether it fits at all. The RTX PRO 6000 answers the second question for 120B-class mixture-of-experts models without a second card.
StorageReview's numbers show what that means in practice. In its llama.cpp serving test inside a Dell Pro Precision 9 T2 tower, gpt-oss-120b with 8,192-token prompts left room for 64 parallel request slots and 22.5 GiB of context cache on one card. A single user got 182.7 tokens per second on the 600W Workstation Edition and 160.6 on the 300W Max-Q. Those are llama.cpp figures. They are not comparable with the vLLM throughput numbers elsewhere in this review.
The second problem it solves is the 32 GB wall. Gamers Nexus ran LM Studio in a test it labelled experimental, from a June 2025 video that predates the vLLM and llama.cpp runs above by more than a year. Its Workstation Edition and an RTX 5090 Founders Edition tied at about 81 tokens per second on an 8B model. On the 26 GB Mistral Small build, the 5090 fell to 17 against the PRO card's 42.4. On Gemma 3 27B the gap was 29 to 5, and on Llama 3.3 70B at Q4_K_S Gamers Nexus' figure put the PRO card 928% ahead. The pattern is the point: once the model leaves VRAM, the consumer card collapses.
The limit is equally clear. Above 96 GB the card needs company. StorageReview needed two Server Edition cards for MiniMax-M2.7 in NVFP4 and four for MiniMax-M3 and GLM-5.2. On GLM-5.2, four cards holding 384 GB managed 9 tokens per second for one user, against 35 on a single DGX Station.
Pros and Cons
The strongest evidence comes from one lab running one harness. StorageReview's Nov. 3 first look at AMD's Instinct MI350P put the RTX PRO 6000 Server Edition, at its full 600W in a Dell PowerEdge XE7740, beside the MI350P at 450W, an H200 NVL at 450W and an ASUS ExpertCenter Pro ET900N G3 DGX Station. NVIDIA's cards ran NVIDIA's vLLM 26.08 container on CUDA 13.4.1. On gpt-oss-120b, which ships in MXFP4 so every card ran the same weights, the RTX card reached 3,064 output tokens per second on 512-token chat prompts and 1,169 on 8,192-token prompts at 128 streams. The H200 NVL logged 3,376 and 1,825, the MI350P 5,057 and 2,101, and the DGX Station 9,280 and 5,023.
That test also shows the weakness. StorageReview measured the card's GDDR7 at 1,540 GB/s on reads and 1,483 GB/s on writes, against 3,291 GB/s for the MI350P and 6,869 GB/s for the DGX Station. On Mistral Small 3.1 24B at a single stream, the RTX card wrote 56 tokens per second in FP8 against 100 on the MI350P. StorageReview credits the AMD card's HBM3E memory for its single-stream lead. The RTX card kept its lead only where NVIDIA's NVFP4 builds ran at high concurrency, as on Llama 3.1 8B at 128 streams, 8,869 against 8,383, with NVFP4 on the RTX card and MXFP4 on the MI350P, two different FP4 formats.
The power limit matters less than its label suggests. StorageReview ran both Workstation Editions in the same Dell tower in its Oct. 20 review. MLPerf Client's Llama 3.1 8B decode on llama.cpp rose from 230.9 tokens per second on the 300W Max-Q to 252.8 on the 600W card, about 9% (Voltgrid's arithmetic from StorageReview's figures: 8.7% below the 600W card, 9.5% above the Max-Q). Time to first token fell from 0.082 to 0.059 seconds, 28% less. Across its suite, StorageReview found the 600W card added 7% to 20% on decode and 20% to 39% on prompt processing and image generation.
The heat is real. Gamers Nexus measured the 600W Workstation Edition's core at about 82C under a fixed render load, not the Server Edition in a chassis,, about 10C warmer than the RTX 5090 FE, with VRAM near 88C. Noise was about 1 dBA higher than the 5090 once Gamers Nexus adjusted for the noise floor. Its teardown found thermal paste instead of liquid metal, and some power inductors only partly covered by thermal pads. In StorageReview's Xeon tower, fitting the 600W card cost the processor 4% to 5% on all-core work and meant removing the 25GbE network card from the adjacent slot.
Who it's for
The first buyer is a developer or small team that wants a 120B-class mixture-of-experts model on one card in an existing tower. StorageReview's figures of 160.6 to 182.7 tokens per second for one user on gpt-oss-120b, depending on the edition, are interactive speeds. Sixty-four slots fit in memory for a team sharing the card.
The second is a studio that needs graphics, video and AI in one machine. StorageReview noted that the card's graphics, ray-tracing and video hardware give it a broader role than AMD's MI350P accelerator, and Gamers Nexus measured it 5% to 14% ahead of an RTX 5090 in games.
The third is a server buyer filling PCIe slots who plans to scale by card count. StorageReview's tests show the Server Edition handles 24B to 120B models on one card and large MoE models such as MiniMax-M2.7 on two cards and MiniMax-M3 on four.
It is not for a buyer whose target model is larger than 96 GB and who wants one device. Four cards ran GLM-5.2 at 9 tokens per second for one user in StorageReview's test, against 35 on a single DGX Station.
Why Memory Bandwidth Sets Decode Speed
A language model writes one token at a time, and each token needs the active weights read from memory again. Decode speed therefore tracks how fast memory can feed the chip more than how much math the chip can do, while memory capacity decides whether the model fits at all.
StorageReview's vLLM runs show the split. Its RTX PRO 6000 Server Edition measured 1,540 GB/s on reads and the GB300 DGX Station 6,869 GB/s, and the Station served gpt-oss-120b at 9,280 tokens per second to the card's 3,064. StorageReview credits the MI350P's HBM3E memory for its single-stream lead. The Spark's 273 GB/s and the Mac Studio's 1.2 TB/s are NVIDIA's and Apple's ratings, not measurements.
How it compares
Against the NVIDIA DGX Station, the numbers come from the same StorageReview harness. The ASUS-built GB300 Station's single GPU served gpt-oss-120b at 9,280 tokens per second to the RTX card's 3,064, and gpt-oss-20b at 22,041 to 7,937. It also has 748 GB of coherent memory, 252 GB of it HBM3e at 7.1 TB/s. The Station is rated at 1,600 W of system power by NVIDIA, and Dell lists its default Dell Pro Precision GB300 tower at $160,195 on Dell.com as of Nov. 1. Those are three different units: the 9,280 tok/s came from ASUS's machine, the wattage is NVIDIA's rating and the price is Dell's. Our DGX Station review cited an earlier StorageReview RTX PRO 6000 result from a different setup. The figures here are the lab's newest, from the Server Edition in a server.
Against the NVIDIA DGX Spark, the trade is capacity for bandwidth. The Spark holds 128 GB of unified memory but moves it at 273 GB/s, against the Workstation Edition's rated 1,792 GB/s. Its power supply is rated 240 W, and the 128 GB, 4 TB model was listed at $6,950 in a copy of NVIDIA's marketplace page cached Oct. 31, with stock unverified. StorageReview's new runs did not include a GB10 machine, so this review sets no tokens-per-second ratio between the two. Our GB10 comparison has the Spark-class vLLM figures.
Against the Apple Mac Studio with M5 Ultra, the Mac offers up to 512 GB of unified memory at 1.2 TB/s in a box with a 480 W maximum continuous power rating. MacRumors, reading Apple's configurator, put the 512 GB configuration at a minimum of $22,299 on Oct. 28. The Mac holds models the RTX card cannot, but its published LLM tests use MLX and LM Studio on different models from the ones StorageReview ran on the RTX card, so no like-for-like speed comparison exists yet.
Price is the open variable. NVIDIA's US marketplace listed the Workstation Edition at $16,000, out of stock, when last read on Aug. 10, 2026. That listing has not been rechecked since, so treat the figure as dated. Gamers Nexus paid $8,000 for its card in 2025. In StorageReview's Dell.com configuration, which used the 300W Max-Q card, the card made up $19,090 of a roughly $28,300 tower, and Dell charged the same for the 300W and 600W editions.
What to watch
StorageReview said it will rerun the MI350P at its full 600W in a Dell PowerEdge XE7745 and repeat its two-card tests on ROCm 10.1. It gave no date. Those runs will show whether the RTX card's gap to AMD's PCIe card narrows or widens. StorageReview's Oct. 20 Dell Pro Precision 9 T2 review also plans a pass with external power and temperature logging to explain the CPU slowdown it saw with the 600W card in the Xeon tower.
The rivals have dates of their own. DGX Station for Windows is due from partners in December 2026, Apple's first 512 GB M5 Ultra orders are due to arrive on Dec. 3, and NVIDIA's quarterly results call is set for Nov. 17.
The last open item is a current US price for the RTX PRO 6000 Workstation Edition. Until NVIDIA or a major retailer posts one, any cost-per-token comparison with the DGX Spark or Mac Studio rests on an August reading.
How it compares
Full table| Product | Memory | Bandwidth | AI compute | Measured speed | Price |
|---|---|---|---|---|---|
| HP ZGX Fury AI StationHP | 252 GB HBM3e GPU + 496 GB LPDDR5x CPU (4x 128 GB SOCAMM); 748 GB unified[1] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5x)[1] | — | Two-unit cluster with an ASUS ET900N G3 over two 400G DACs: GLM-5.3 NVFP4 5,018 output tok/s at 256 streams, 512/512, vLLM 0.27.1 TP2 with MTP (StorageReview); no single-unit HP result[2] | Japan list price from 28,490,000 yen incl. tax (sales from Oct 27, 2026); no US list price published[3] |
| NVIDIA DGX StationNVIDIA (systems built by ASUS, Dell, GIGABYTE, HP, MSI, Supermicro and Exxact) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[4] | GPU HBM3e 7.1 TB/s; CPU LPDDR5X 396 GB/s; NVLink-C2C 900 GB/s between them[4] | 15 PFLOPS FP4 (without sparsity)[4] | gpt-oss-120b MXFP4, stock vLLM, 512/512 chat workload: 9,280 output tok/s at 128 streams (5,023 on 8,192/1,024 prompts), single GB300 (StorageReview, ASUS ExpertCenter Pro ET900N G3)[5] | No NVIDIA list price; first public US OEM list price is Dell Pro Precision with GB300 at $160,195 default config (Dell.com, read Nov 1, 2026); ServeTheHome had heard about $100K[6] |
| NVIDIA RTX PRO 6000 Blackwell Workstation EditionNVIDIA (sold through PNY, TD SYNNEX and workstation makers)This story | 96 GB[7] | 1,792 GB/s[7] | 4,000 AI TOPS (FP4, with sparsity) (sparse)[7] | gpt-oss-120b MXFP4, stock vLLM, 512/512 chat workload: 3,064 output tok/s at 128 streams (1,169 on 8,192/1,024 prompts); Server Edition at 600W (StorageReview)[5] | $16,000 on NVIDIA's US marketplace (Workstation Edition), listed out of stock[8] |
| Apple Mac Studio (M5 Ultra)Apple | up to 512 GB unified (96 GB on 30-core M5 Ultra; 256 GB or 512 GB on 36-core/80-core M5 Ultra)[9] | 1.2 TB/s[9] | — | Qwen 3.8 27B 4-bit MLX in LM Studio: about 55 tok/s on M5 Ultra (36-core, 256 GB) vs about 40 on M3 Ultra (BGR)[10] | $22,299 minimum with 512 GB ($6,799 36-core CPU/80-core GPU M5 Ultra config plus $15,500 memory upgrade; Oct 28, 2026)[11] |
| NVIDIA RTX Spark (N1X) PCsNVIDIA (MediaTek collaborated on the custom CPU design) | Up to 128 GB LPDDR5X (20-core CPU / 6,144-core GPU version); up to 64 GB (18-core / 5,120-core laptop version)[12] | Up to 300 GB/s: LPDDR5X-9400 on a 256-bit bus (NVIDIA's product page lists no bandwidth)[13] | — | gpt-oss:20b via Ollama in a Codex CLI coding agent, 64K context: 58.5 tok/s generation, 3 of 4 tasks passed (Dell XPS 16, 20-core N1X, 64 GB; StorageReview)[14] | Laptops from $2,599; pricing and configurations vary by region[15] |
| ASUS Ascent GX10ASUS | 64 GB or 128 GB LPDDR5X-8533 unified[16] | 273 GB/s (8533 MT/s), as listed by StorageReview; ASUS's spec page states no bandwidth[17] | Up to 1 PFLOP FP4 (GB10; NVIDIA's footnote: theoretical, using the sparsity feature). ASUS's pages say 1 petaFLOP / FP4 with no sparsity label (sparse)[18] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 70 tok/s at batch 1 rising to 680 tok/s aggregate at batch 64 (StorageReview)[17] | $5,999 (128 GB, 1 TB, GX10-GG0010BN, ASUS eShop US, Oct 30, 2026)[19] |
| Dell Pro Precision with GB10 (model FCM1253; launched as Dell Pro Max with GB10)Dell | 128 GB LPDDR5x up to 8533 MT/s onboard (64 GB option also listed)[20] | 273 GB/s (128 GB LPDDR5x, 256-bit)[21] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 68.57 tok/s at batch 1 rising to 670.83 tok/s aggregate at batch 64 (StorageReview)[22] | $7,967 (128 GB, 2 TB Gen4 QLC SSD default config, Dell.com US, read Nov 2, 2026 16:40 UTC)[20] |
| Framework Desktop (Ryzen AI Max+ PRO 495, 192 GB)Framework | 192 GB LPDDR5X-8533 soldered[23] | 273 GB/s (256-bit)[23] | — | — | $6,799 (Max+ PRO 495 192 GB DIY Edition pre-order, Nov 3, 2026; storage not included)[24] |
| GIGABYTE AI TOP ATOMGIGABYTE | 128 GB unified system memory[25] | 273 GB/s (LPDDR5x-8533, 256-bit)[26] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 60.71 tok/s at batch 1 rising to 649.62 tok/s aggregate at batch 64 (StorageReview)[26] | $7,312.00 advertised at CDW US against a $7,999.99 list (128 GB, 4 TB, ATAGB10-9000; read Nov 2, 2026)[27] |
| GMKtec EVO-X5 Pro AI Mini PCGMKtec | 192 GB LPDDR5X-8533 onboard (8 x 24 GB, non-upgradeable); up to 160 GB allocatable as VRAM[28] | Up to 273 GB/s[29] | — | GMKtec Laboratory table: GLM-5.3-Flash UD-IQ4_XS (146.05 GB) decode 17.79 tok/s, prefill 70.18, TTFT 14.71 s; Qwen3.8-Flash-Next ROCmFP4-FAST (93.48 GB) decode 45.08 tok/s[28] | $6,799 (192 GB/2 TB) and $7,099 (192 GB/4 TB), GMKtec US store, Nov 2, 2026[28] |
| HP ZGX Nano AI Station (G1n)HP | 128 GB coherent unified system memory[30] | 273 GB/s (128 GB LPDDR5x)[31] | GB10: up to 1 PFLOP FP4, theoretical, using the sparsity feature; HP and reviewers list 1,000 TOPS FP4 (sparse)[18] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.6 tok/s at batch 1 rising to 722.9 tok/s aggregate at batch 64 (StorageReview)[32] | $7,399.00 at the HP Store for the 4 TB model; $4,759 on Amazon (Notebookcheck, review updated Oct 5, 2026)[33] |
| Lenovo ThinkStation PGXLenovo | 128 GB LPDDR5X unified (256-bit)[34] | 273 GB/s[34] | — | — | about $4,100 for the 1 TB configuration (Mar 2026)[35] |
| MSI EdgeXpert (MS-C931)MSI | 64 GB or 128 GB LPDDR5x unified (256-bit)[36] | 273 GB/s[36] | 1 PFLOPS FP4 (sparse)[36] | — | No list price; MSI sells via quote (Get a quote)[36] |
| NVIDIA DGX SparkNVIDIA (partner GB10 systems from Acer, ASUS, Dell, GIGABYTE, HP, Lenovo and MSI) | 128 GB; a 64 GB configuration is sold only through OEM partners[18] | 273 GB/s[18] | Up to 1 PFLOP FP4 (theoretical, using the sparsity feature) (sparse)[18] | Qwen 3.8 27B (dense) with multi-token prediction: decode of about 20 tokens/s, with time-to-first-token staying interactive out to the full 262K context.[37] | $6,950.00 (128 GB, 4 TB) on NVIDIA's enterprise marketplace with an Add To Cart button in a copy cached 07:59 UTC on 2026-10-31; stock unverified (listed out of stock on 2026-10-21); 64 GB partner systems from $4,999[38] |
| NVIDIA DGX Spark 64 GBNVIDIA (sold by Acer, ASUS, Dell, Gigabyte, HP and MSI) | 64 GB LPDDR5X unified (two units pool 128 GB over ConnectX-7)[39] | 273 GB/s (256-bit; NVIDIA spec table covers both 64 GB and 128 GB)[18] | 1 PFLOPS FP4 (sparse; NVIDIA spec table covers both memory configurations)[18] | — | from $4,999 (partner systems, Oct 2026; no Founders Edition)[39] |
| AMD Ryzen AI Halo Developer PlatformAMD | 128 GB LPDDR5x-8000 unified[40] | 256 GB/s[40] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL 256/256: 222 tok/s aggregate at batch 64 vs 701 on DGX Spark (StorageReview)[41] | $3,999 with 2 TB SSD (Jul 2026)[41] |
| Framework Desktop (Ryzen AI Max+ 395)Framework | 128 GB LPDDR5x-8000 soldered (32 GB and 64 GB options)[42] | 256 GB/s[43] | — | gpt-oss-120b MXFP4 in LM Studio (out-of-the-box setup): roughly 45 tok/s (ServeTheHome; Ryzen AI Max+ 395, 128 GB, Windows 11 Pro)[44] | $3,449 (DIY Edition, Max+ 395 with 128 GB, system only; out of stock, Nov 3, 2026)[45] |
| Acer Veriton GN100 AI Mini WorkstationAcer | 128 GB LPDDR5x coherent unified[46] | — | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.65 tok/s at batch 1 rising to 713.18 tok/s aggregate at batch 64 (StorageReview)[47] | from $3,999 in North America (announced Sep 3, 2025; prices vary by region)[46] |
| ASRock Industrial AI BOX-A395ASRock Industrial | 128 GB LPDDR5X-8000 soldered[48] | — | — | AgentSTH V7, 32 threads: 15% ahead of the next-closest Ryzen AI Max+ 395 box (single-core within 1%); estimated SPEC CPU2026 int rate: top of a 44% spread across four 395 systems; measured by ServeTheHome, Ubuntu 26.04[49] | — |
| Dell Pro Precision with GB300 (model FCT6263; announced as Dell Pro Max with GB300)Dell | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU[6] | — | — | — | $160,195 (Dell.com US default config with RTX PRO 2000 display GPU and 16 TB SSD, read Nov 1, 2026)[6] |
| GMKtec EVO-X2 AI Mini PCGMKtec | 64 GB or 128 GB onboard LPDDR5X-8000 (non-upgradeable)[50] | — | — | — | $3,499.99 (128 GB/1 TB, GMKtec US store, Oct 30, 2026; listed against $3,999.99)[50] |
| HP Z2 Mini G1a WorkstationHP | up to 128 GB unified, up to 96 GB assignable to the GPU, up to 8000 MT/s[51] | — | up to 50 NPU TOPS[51] | gpt-oss-120b GGUF (63.39 GB, full GPU offload) in LM Studio: close to 40 tok/s (StorageReview)[52] | $4,781 list for StorageReview's review configuration; about $3,300 street (B&H top spec with 2 TB SSD at $3,342.65, Aug 2025)[52] |
| Microsoft Surface RTX Spark Dev BoxMicrosoft | 128 GB unified memory[53] | — | up to 1 PFLOP of AI compute (Microsoft; precision and sparsity not stated on the page) (sparse)[53] | — | From $5,999.99 (Microsoft Store US, pre-order, read Nov 1, 2026)[53] |
| MSI XpertStation WS300MSI (NVIDIA DGX Station platform) | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU (748 GB coherent)[54] | — | — | GPT-OSS-120B MXFP4, vLLM, 512/512 ISL/OSL, concurrency sweep to 128: peak 9,294 output tok/s vs 3,384 on an RTX PRO 6000 and 500 on DGX Spark (StorageReview, MSI-hosted unit, no add-in GPU)[54] | ServeTheHome calls it a $100K+ system; no MSI list price given[55] |
| Tenstorrent TT-QuietBox 2 (Blackhole)Tenstorrent | 128 GB GDDR6 on the accelerators + 256 GB DDR5-5600 system memory[56] | — | — | — | $9,999 (Oct 30, 2026)[56] |
| WiCi One (RTX 5060 Ti edition)WiCi | 16 GB GDDR7 VRAM; 1 TB NVMe 4 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[57] | — | — | — | $2,599 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout. Early-access price was $1,999 (Notebookcheck, Engadget, Sep 2026)[57] |
| WiCi One (RTX 5090 edition)WiCi | 32 GB GDDR7 VRAM; 4 TB NVMe 5 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[57] | — | — | — | $9,999 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout[57] |
Italic values are reported by an outlet or measured by an independent lab; the rest come from the maker. Measured speeds use different models, quantizations and tools, so read each with its source rather than against the others. Voltgrid News does not test hardware itself.
Sources (57)
- [1] HP
- [2] StorageReview
- [3] HP Japan
- [4] NVIDIA
- [5] StorageReview
- [6] Dell
- [7] NVIDIA
- [8] NVIDIA
- [9] Apple
- [10] BGR
- [11] MacRumors
- [12] NVIDIA
- [13] ServeTheHome
- [14] StorageReview
- [15] NVIDIA
- [16] ASUS
- [17] StorageReview
- [18] NVIDIA
- [19] ASUS eShop
- [20] Dell
- [21] HotHardware
- [22] StorageReview
- [23] Framework Blog
- [24] Framework
- [25] GIGABYTE (PR Newswire)
- [26] StorageReview
- [27] CDW
- [28] GMKtec
- [29] GMKtec
- [30] HP
- [31] HotHardware
- [32] StorageReview
- [33] Notebookcheck
- [34] Lenovo PSREF
- [35] ServeTheHome
- [36] MSI
- [37] Tom's Hardware
- [38] NVIDIA Marketplace
- [39] NVIDIA Blog
- [40] AMD
- [41] StorageReview
- [42] Framework
- [43] Framework Blog
- [44] ServeTheHome
- [45] Framework
- [46] Acer
- [47] StorageReview
- [48] ServeTheHome
- [49] ServeTheHome
- [50] GMKtec
- [51] HP
- [52] StorageReview
- [53] Microsoft
- [54] StorageReview
- [55] ServeTheHome
- [56] Tenstorrent
- [57] WiCi
Sources
- 01NVIDIA RTX PRO 6000 Blackwell Workstation EditionNVIDIA · nvidia.com
- 02NVIDIA RTX PRO 6000 Blackwell Benchmarks & Tear-Down | Thermals, Gaming, LLM, & Acoustic TestsGamers Nexus · gamersnexus.net
- 03AMD Instinct MI350P First Look: 144GB of HBM3E in a 600W PCIe CardStorageReview · storagereview.com
- 04Dell Pro Precision 9 T2 Review: Xeon 6 Brings Four Channels of DDR5-6400 and E3.S to the Single-GPU TowerStorageReview · storagereview.com