Framework Desktop Review: 128GB Ryzen AI Max+ 395 at 45 tok/s, $3,449
ServeTheHome measured about 45 tok/s on gpt-oss-120b with the 128 GB Ryzen AI Max+ 395 model. It now lists at $3,449, up from $1,999 at launch, and every configuration is out of stock in the US.
Local AI DeskEdited by Ege Erten
8 min readAI-assisted
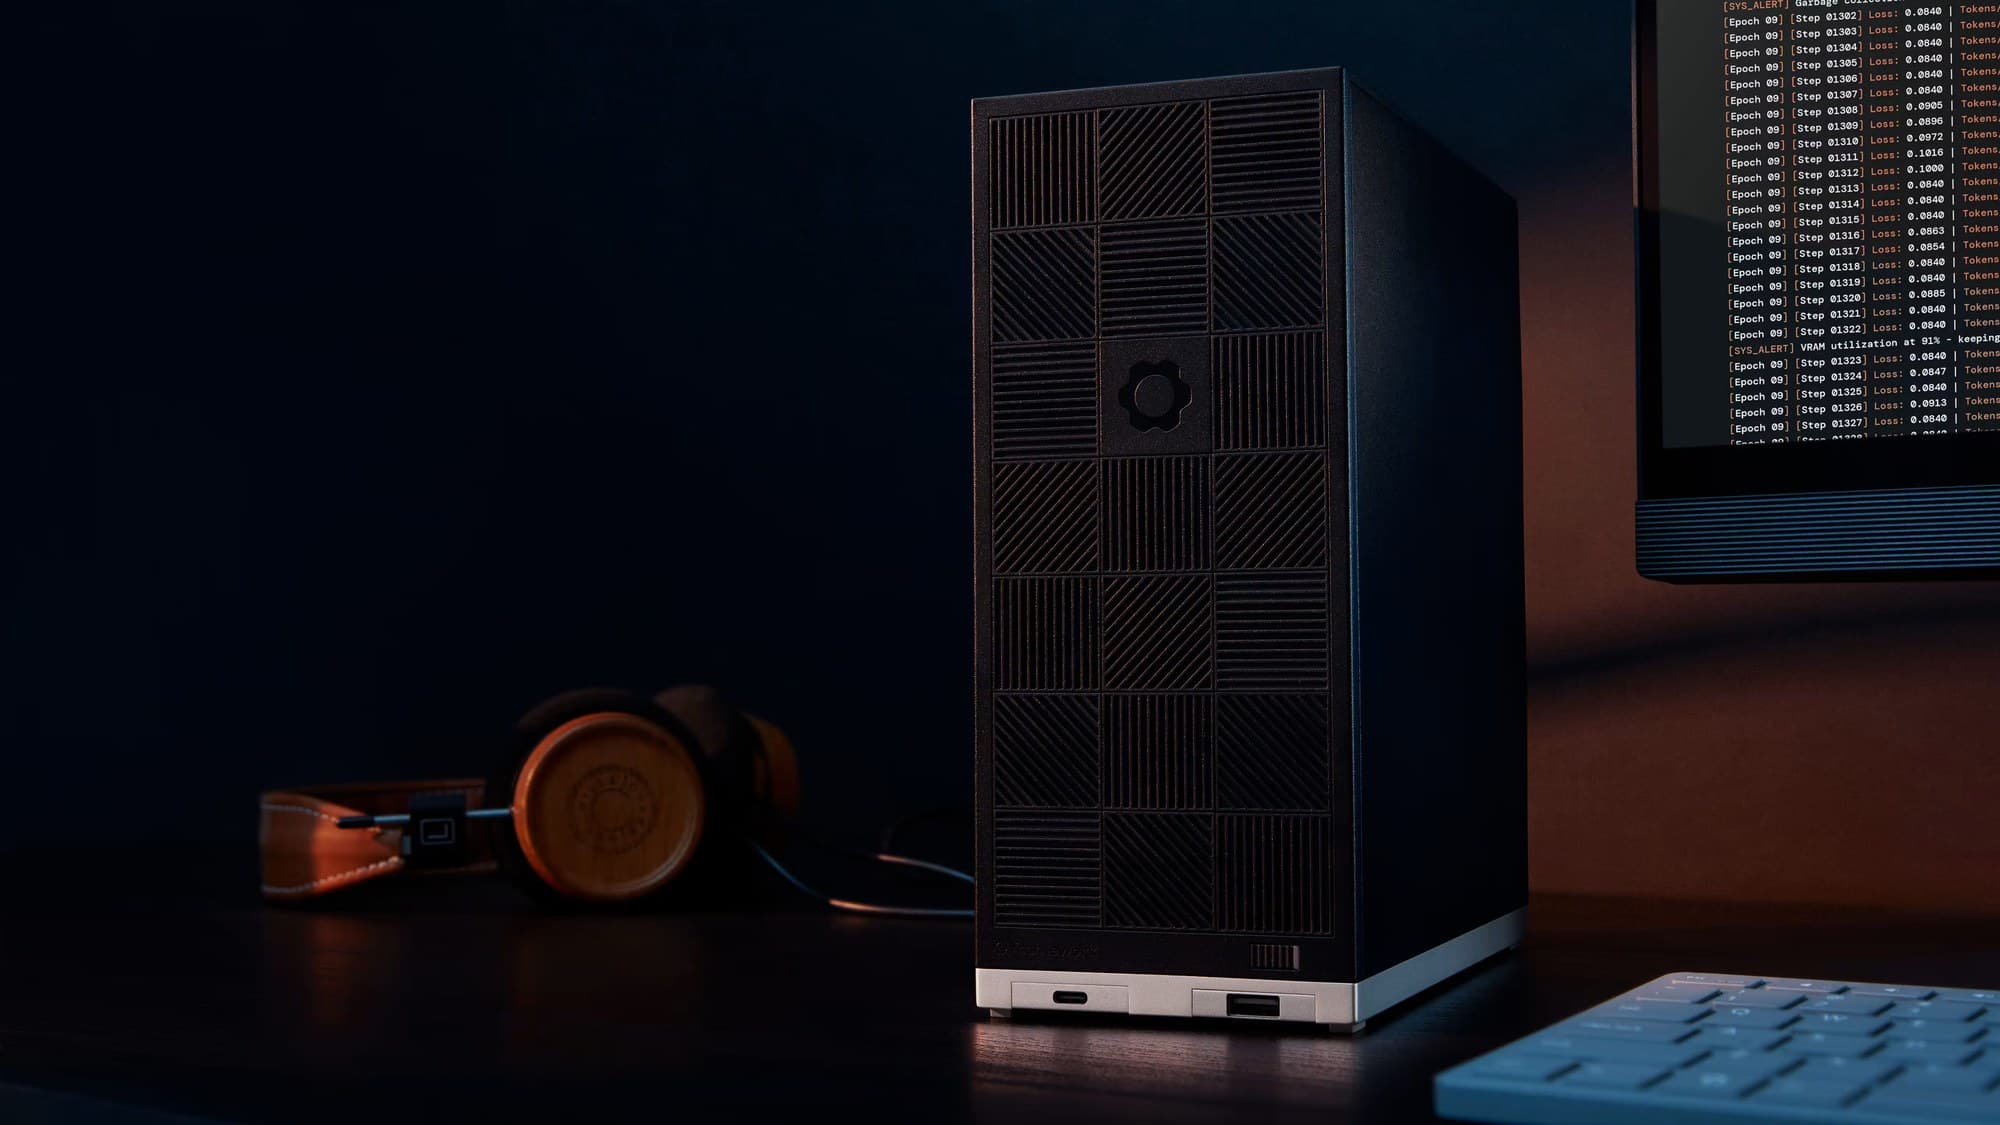
The Framework Desktop, shown in Framework's product-page image.
Image: Framework
Source · Press image from the Framework website, used for news reporting.
The Framework Desktop with AMD's Ryzen AI Max+ 395 and 128 GB of memory ran gpt-oss-120b at roughly 45 tokens per second for ServeTheHome, but on Nov. 4 Framework's US store listed it at $3,449, system only, and out of stock.
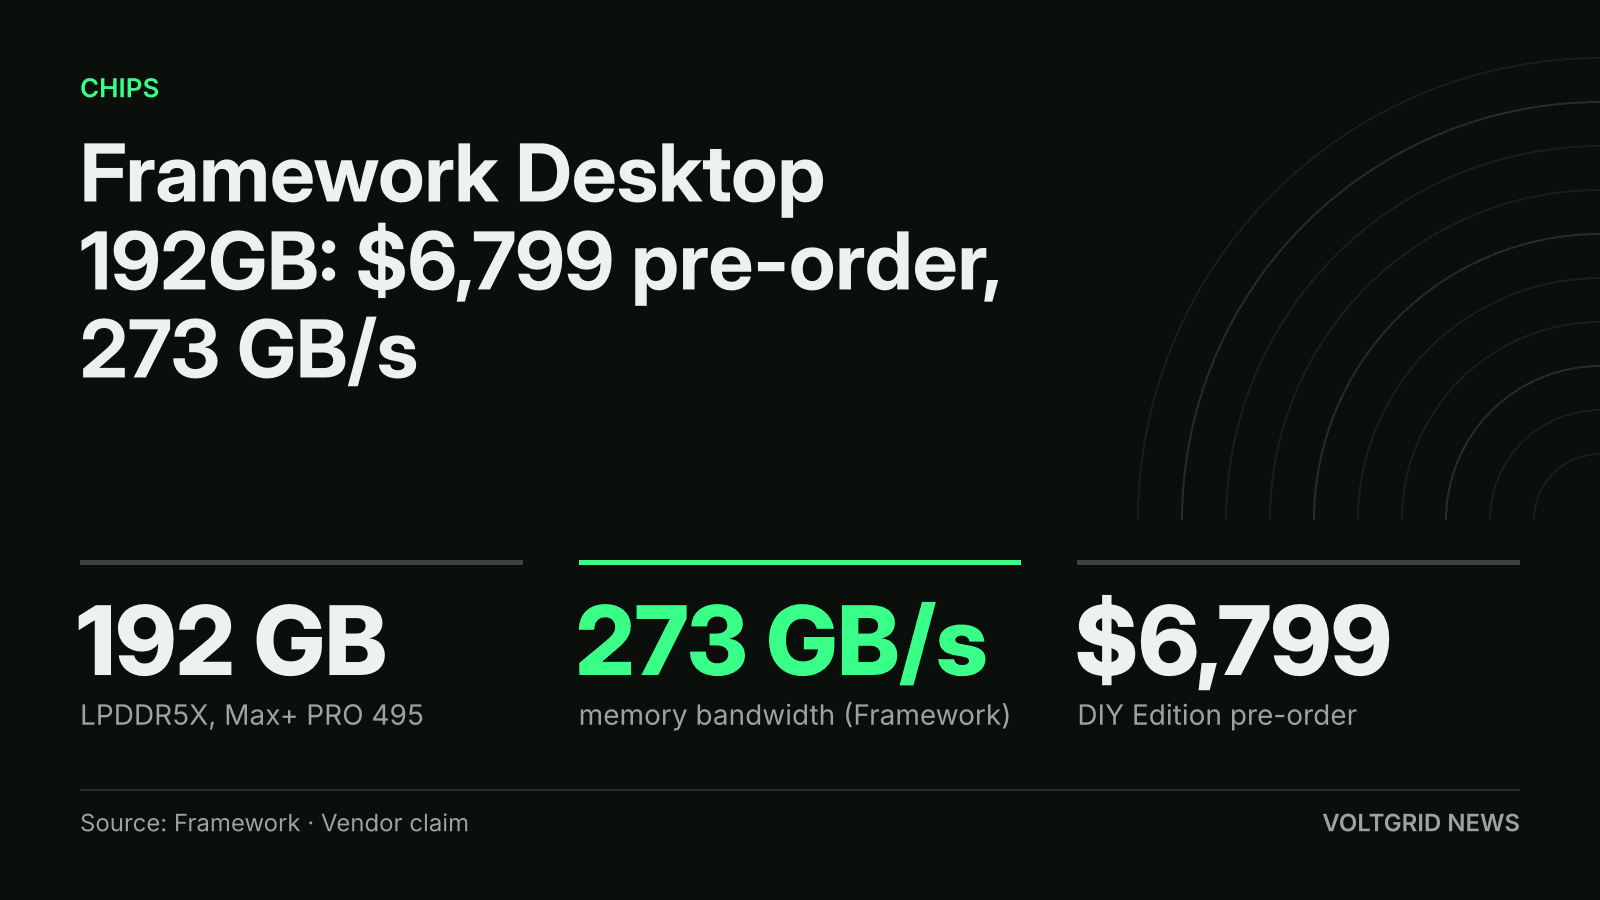
That price is $1,450, or about 73%, above the $1,999 Framework announced for the same 128 GB DIY configuration on Feb. 25, 2025. Every Ryzen AI Max 300 configuration on the store page, from the $1,269 Max 385 with 32 GB to the $1,959 Max+ 395 with 64 GB, showed "out of stock" with a notify-me button. Framework gave no restock date. This review sets the maker's claims against three independent sources: ServeTheHome's review of a 128 GB unit it bought, Notebookcheck's review of a 64 GB unit, and a reproducible llama.cpp sweep that the Level1Techs forum member lhl ran on pre-production 128 GB units and published on GitHub. The 192 GB sibling with the Ryzen AI Max+ PRO 495 is a different machine, covered in our report on its $6,799 pre-order.
What's new
The Framework Desktop is a 4.5-litre mini-ITX desktop, 96.8 x 205.5 x 226.1 mm and 3.1 kg, built around a mobile-class chip. The Ryzen AI Max+ 395 puts 16 Zen 5 cores and a 40-core Radeon 8060S GPU on one package with 128 GB of LPDDR5x-8000 shared between them. Framework says the memory runs on a 256-bit bus for 256 GB/s, and that it had to solder the memory to reach that speed, after months of trying modular options with AMD.
The power budget is a desktop's, not a laptop's. Framework rates the chip at 120 W sustained and 140 W boost, fed by a 400 W FlexATX power supply it developed with FSP. The mainboard is standard mini-ITX with a PCIe x4 slot, two M.2 2280 slots, two USB4 ports, two DisplayPort, HDMI and 5 Gbit Ethernet, so it can move into another case.
The buying model is also unusual for this class. Every system is a DIY Edition: the board, chip, memory and heatsink arrive installed, and the buyer adds the fan, side panel, front tiles, expansion cards, storage and operating system. On Nov. 4 the store listed a 2 TB SanDisk SN7100 SSD at $505 extra and Windows 11 Pro at $199.
What it solves
Memory capacity decides which models load at all. gpt-oss-120b in MXFP4 is a 63.39 GB file in StorageReview's run on HP's Z2 Mini (Ryzen AI Max+ PRO 395), so it fits in 128 GB with room for context. Framework says one unit runs Llama 3.3 70B at Q6 "at real-time conversational speed", and that several units linked over USB4 and 5 Gbit Ethernet can run the full DeepSeek R1 671B. Both are the maker's claims; no source we read measured either.
Bandwidth decides how fast the answer comes out, and here the sweep is the useful evidence. A model reads its active weights from memory for every token it writes, so speed tracks how many bytes each token needs. lhl measured about 215 GB/s of usable GPU bandwidth out of the 256 GB/s theoretical. On that bus, the dense Shisa V2 70B at Q4_K_M, which used about 40.5 GiB of memory at peak, generated 5.0 tokens per second. Qwen 3 30B-A3B, a mixture-of-experts model with 3 billion active parameters, generated 72.0. The 142-billion-parameter dots1, with 14 billion active, reached 20.6.
That split is the practical lesson. The machine holds large models, and it runs them quickly only when few of their parameters are active per token. gpt-oss-120b is such a model, which is why ServeTheHome's 45 tokens per second is possible on a 256 GB/s bus. Llama 3.3 70B at Q6 is dense and larger than the Q4_K_M 70B that lhl measured at 5.0, which suggests it would run slower still, though no one in our sources measured that exact model and quantization.
Pros and Cons
The strongest pro is the combination of speed and calm. ServeTheHome, which bought its 128 GB unit, measured roughly 45 tokens per second on gpt-oss-120b MXFP4 with an out-of-the-box LM Studio setup on Windows 11 Pro, without stating context length or batch size. It measured 10 to 20 W at idle and 140 to 170 W under load, ran the system for a day and a half at 140 W without trouble, and recorded 36 to 37 dBA at idle and 39 to 41 dBA under load with the Noctua fan, quieter than the Minisforum S1-Max. It credited the large heatsink and the 120 mm fan.
Notebookcheck's 64 GB unit told the same story on power and heat. It measured 10.5 W at idle on average, 140.6 W in Cyberpunk 2077 at 1080p Ultra and a 164.2 W peak, against 178.1 W and 214.9 W for the GMKtec EVO-X2 on the same chip. Under Prime95 the CPU boosted to 4 GHz at 115 W, then settled at 3.6 GHz and 100 W, with cores at 50 to 65 °C. Notebookcheck called it quieter, cooler and more efficient than smaller mini PCs with the same processor. Its unit had half the memory of the AI configuration and it ran no language models, so its numbers speak to thermals, not to tokens per second.
The cons are about money and plumbing. ServeTheHome priced its configuration, with a 2 TB SSD, Windows 11 Pro and cosmetic extras, at $2,500 to $2,600 in November 2025, and said that 5GbE should not be the only wired networking on a system at that price; loading models from network storage took longer, so its team reached for other machines. It also found that the board's PCIe Gen4 x4 slot has no rear opening for a card, and that a team member fitted the Noctua fan in the less effective orientation, which caused problems under sustained load. Notebookcheck listed the soldered memory, no 10 Gbps RJ-45 option, Wi-Fi without 320 MHz channels and no PCIe 5 SSD or ECC support among its cons, and noted that hot air exits through the side panel.
lhl's figures carry their own caveat. They come from pre-production units with near-production firmware, Linux kernels 6.15.5 and 6.15.6, ROCm 7.0 nightly builds and llama.cpp build b5863 from July 10, 2025. lhl chose the best backend for each model, mostly Vulkan for generation, and wrote that prompt processing had a lot of performance still on the table. Results on current software may differ.
Who it's for
It fits a developer who wants to run a mixture-of-experts model in the 100B class locally on x86, on Windows or Linux, without a separate GPU: ServeTheHome's 45 tokens per second on gpt-oss-120b is fast enough for interactive use. It fits a buyer who values a quiet desk machine that draws about 140 W under load and can be opened and repaired. It also fits someone who already owns storage, a fan and an operating system licence, since the $3,449 DIY system needs none of Framework's add-ons.
It does not fit a buyer who needs a dense 70B model at interactive speed, given lhl's 5.0 tokens per second at Q4_K_M, or a team that plans to cluster units: 5GbE and USB4 are the only built-in links, and no independent source has measured Framework's multi-unit claim. As of Nov. 4, a buyer could not order one from Framework's US store at all.
How it compares
The closest rivals use the same chip, so price and build decide most of it. Our AMD Ryzen AI Halo review covers AMD's own box with the same Max+ 395, 128 GB and 256 GB/s, which StorageReview priced at $3,999 with a 2 TB SSD in July. Framework's $3,449 system plus its $505 2 TB SSD comes to $3,954 before a fan or expansion cards, within $45 of the Halo's price. The Halo brings single 10GbE where the Framework has 5GbE. StorageReview's Halo figure of 222 tokens per second aggregate at batch 64 came from vLLM serving, a different tool and load from ServeTheHome's single-user LM Studio run, so the two numbers do not compare.
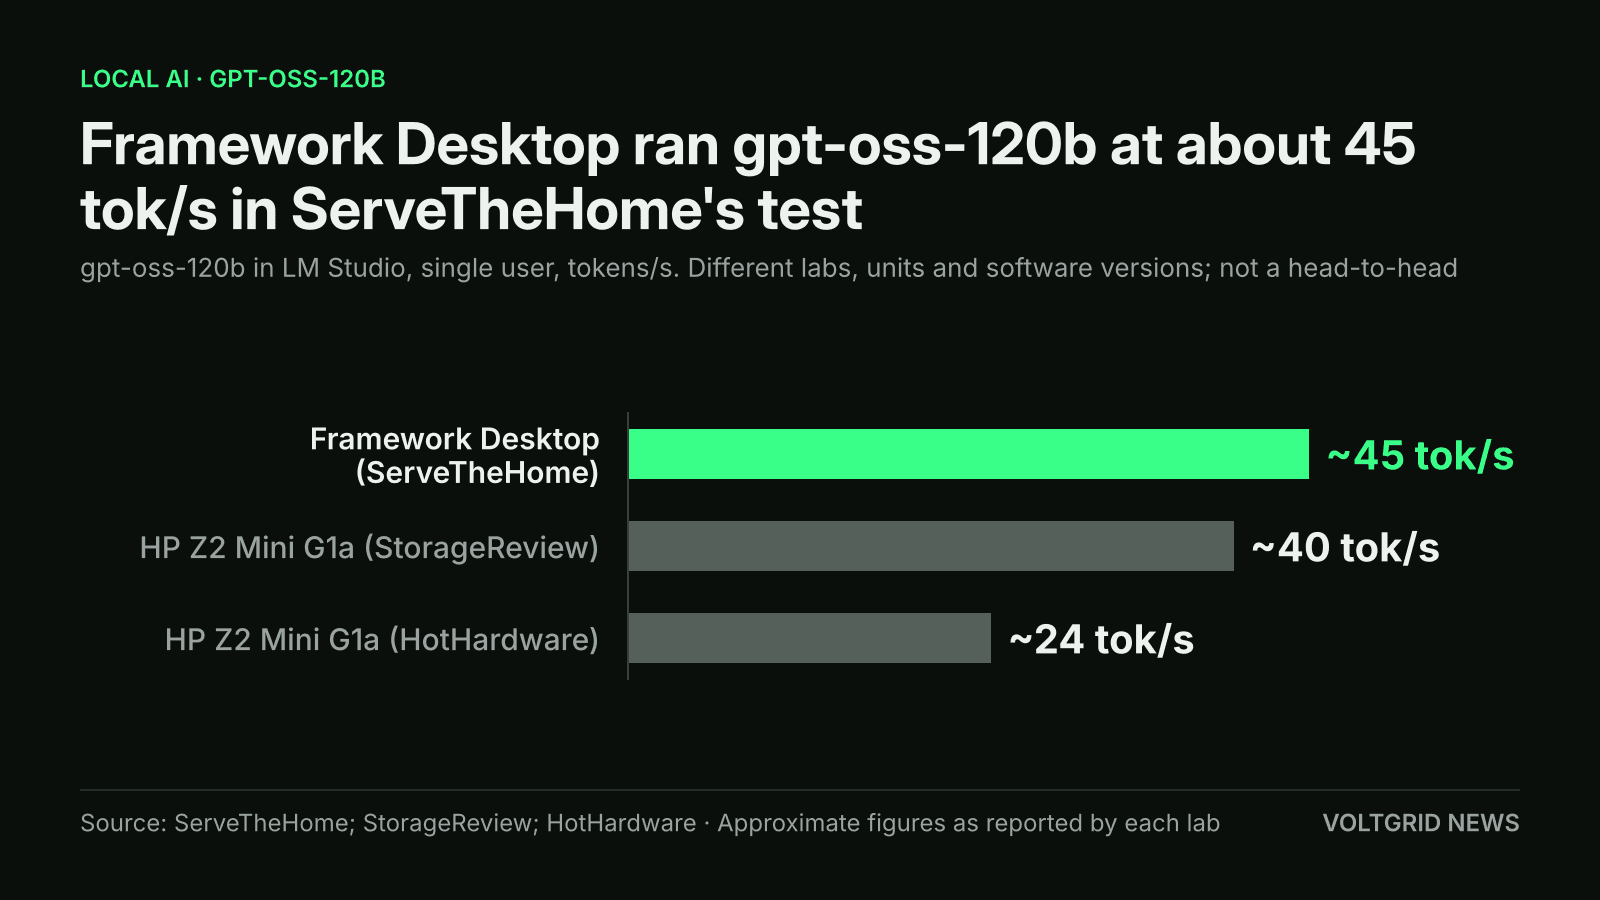
ServeTheHome measured about 45 tok/s on the Framework Desktop; the two HP Z2 Mini results come from different labs, so the bars are not a controlled comparison.
Illustration (AI-generated)
HP's Z2 Mini G1a is the closest like-for-like speed result. Our Z2 Mini review reports StorageReview's close to 40 tokens per second on gpt-oss-120b in LM Studio with 96 GB assigned to the GPU, and HotHardware's about 24 in the same app. That is the same model and the same application as ServeTheHome's 45, but different labs, units and software versions, so the gap is a range across reviews rather than a controlled head-to-head. Notebookcheck measured the Z2 Mini at 195.1 W in the same Cyberpunk 2077 test, above the Framework's 140.6 W.
GMKtec's EVO-X2 listed at $3,499.99 with 128 GB and 1 TB on GMKtec's US store on Oct. 30, with the same 120 W sustained and 140 W peak rating. ServeTheHome ranked the Framework third among the Strix Halo machines it tested, behind the Minisforum S1-Max and Beelink GTR9 Pro and ahead of the EVO-X2, which it called usually the cheapest and likely the best price-performance pick if networking does not matter.
The NVIDIA alternative costs more. Our DGX Spark review covers the 128 GB GB10 box at 273 GB/s, listed at $6,950 with 4 TB of storage in a copy of NVIDIA's marketplace page cached Oct. 31, against $3,449 for the Framework system without storage ($3,954 with a 2 TB SSD), with 200 Gbps ConnectX-7 networking for linking up to four units. ServeTheHome argued the GB10 boxes make sense for buyers who only do AI on NVIDIA's stack, and Strix Halo for those who want Windows, gaming on the side or lower cost. According to our 192 GB report, Phoronix's llama.cpp runs put Dell's GB10 box ahead of the Framework on smaller models. The table below the story sets out every machine's sourced specs.
What to watch
The first date is a restock: Framework's US store showed every Max+ 395 configuration out of stock on Nov. 4 with no date given, and the $3,449 price may move again when it returns. The second is the 192 GB PRO 495 model, whose first two November batches were sold out on Nov. 3, with a third batch listed for December; its first independent measurements will show what 273 GB/s and 192 GB change. The third is software: no recognized lab has published a vLLM serving or multi-user test on a Framework Desktop, and lhl's sweep used mid-2025 nightly builds, so a current llama.cpp or vLLM run on gpt-oss-120b would settle where the machine stands today.
How it compares
Full table| Product | Memory | Bandwidth | AI compute | Measured speed | Price |
|---|---|---|---|---|---|
| ASUS ExpertCenter Pro ET900N G3ASUS (NVIDIA DGX Station GB300 platform) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[1] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5X)[1] | up to 20 PFLOPS AI performance (ASUS gives no precision or sparsity label) (sparse)[2] | GPT-OSS-120B MXFP4, vLLM, 512/512, 1-128 streams: 9,280 aggregate output tok/s at 128 streams; 5,023 on 8,192/1,024 (StorageReview, ASUS-supplied unit, no add-in GPU)[3] | $111,999.99 at Central Computers, US (model ET900N G3-2SSD-V2, request a quote, unavailable online, read Nov 4, 2026); no ASUS list price[4] |
| HP ZGX Fury AI StationHP | 252 GB HBM3e GPU + 496 GB LPDDR5x CPU (4x 128 GB SOCAMM); 748 GB unified[5] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5x)[5] | — | Two-unit cluster with an ASUS ET900N G3 over two 400G DACs: GLM-5.3 NVFP4 5,018 output tok/s at 256 streams, 512/512, vLLM 0.27.1 TP2 with MTP (StorageReview); no single-unit HP result[6] | Japan list price from 28,490,000 yen incl. tax (sales from Oct 27, 2026); no US list price published[7] |
| NVIDIA DGX StationNVIDIA (systems built by ASUS, Dell, GIGABYTE, HP, MSI, Supermicro and Exxact) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[8] | GPU HBM3e 7.1 TB/s; CPU LPDDR5X 396 GB/s; NVLink-C2C 900 GB/s between them[8] | 15 PFLOPS FP4 (without sparsity)[8] | gpt-oss-120b MXFP4, stock vLLM, 512/512 chat workload: 9,280 output tok/s at 128 streams (5,023 on 8,192/1,024 prompts), single GB300 (StorageReview, ASUS ExpertCenter Pro ET900N G3)[9] | No NVIDIA list price; lowest US partner listing read Nov 4, 2026: Exxact Valence VWS-158270643 from $98,450 (Tom's Hardware found $94,930 in Aug); Dell Pro Precision with GB300 lists $160,195[10] |
| NVIDIA RTX PRO 6000 Blackwell Workstation EditionNVIDIA (sold through PNY, TD SYNNEX and workstation makers) | 96 GB[11] | 1,792 GB/s[11] | 4,000 AI TOPS (FP4, with sparsity) (sparse)[11] | gpt-oss-120b MXFP4, stock vLLM, 512/512 chat workload: 3,064 output tok/s at 128 streams (1,169 on 8,192/1,024 prompts); Server Edition at 600W (StorageReview)[9] | $16,000 on NVIDIA's US marketplace (Workstation Edition), listed out of stock[12] |
| Apple Mac Studio (M5 Ultra)Apple | up to 512 GB unified (96 GB on 30-core M5 Ultra; 256 GB or 512 GB on 36-core/80-core M5 Ultra)[13] | 1.2 TB/s[13] | — | Qwen 3.8 27B 4-bit MLX in LM Studio: about 55 tok/s on M5 Ultra (36-core, 256 GB) vs about 40 on M3 Ultra (BGR)[14] | $22,299 minimum with 512 GB ($6,799 36-core CPU/80-core GPU M5 Ultra config plus $15,500 memory upgrade; Oct 28, 2026)[15] |
| NVIDIA RTX Spark (N1X) PCsNVIDIA (MediaTek collaborated on the custom CPU design) | Up to 128 GB LPDDR5X (20-core CPU / 6,144-core GPU version); up to 64 GB (18-core / 5,120-core laptop version)[16] | Up to 300 GB/s: LPDDR5X-9400 on a 256-bit bus (NVIDIA's product page lists no bandwidth)[17] | — | gpt-oss:20b via Ollama in a Codex CLI coding agent, 64K context: 58.5 tok/s generation, 3 of 4 tasks passed (Dell XPS 16, 20-core N1X, 64 GB; StorageReview)[18] | Laptops from $2,599; pricing and configurations vary by region[19] |
| AMD Ryzen AI Halo (Ryzen AI Max+ PRO 495, 192 GB)AMD | 192 GB LPDDR5X (256-bit)[20] | 273 GB/s[20] | — | — | $7,299.99 for the Linux version (released the week of Oct 12, 2026); Windows version coming soon[20] |
| ASUS Ascent GX10ASUS | 64 GB or 128 GB LPDDR5X-8533 unified[21] | 273 GB/s (8533 MT/s), as listed by StorageReview; ASUS's spec page states no bandwidth[22] | Up to 1 PFLOP FP4 (GB10; NVIDIA's footnote: theoretical, using the sparsity feature). ASUS's pages say 1 petaFLOP / FP4 with no sparsity label (sparse)[23] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 70 tok/s at batch 1 rising to 680 tok/s aggregate at batch 64 (StorageReview)[22] | $5,999 (128 GB, 1 TB, GX10-GG0010BN, ASUS eShop US, Oct 30, 2026)[24] |
| Dell Pro Precision with GB10 (model FCM1253; launched as Dell Pro Max with GB10)Dell | 128 GB LPDDR5x up to 8533 MT/s onboard (64 GB option also listed)[25] | 273 GB/s (128 GB LPDDR5x, 256-bit)[26] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 68.57 tok/s at batch 1 rising to 670.83 tok/s aggregate at batch 64 (StorageReview)[27] | $7,967 (128 GB, 2 TB Gen4 QLC SSD default config, Dell.com US, read Nov 2, 2026 16:40 UTC)[25] |
| Framework Desktop (Ryzen AI Max+ PRO 495, 192 GB)Framework | 192 GB LPDDR5X-8533 soldered[28] | 273 GB/s (256-bit)[28] | — | — | $6,799 (Max+ PRO 495 192 GB DIY Edition pre-order, Nov 3, 2026; storage not included)[29] |
| GIGABYTE AI TOP ATOMGIGABYTE | 128 GB unified system memory[30] | 273 GB/s (LPDDR5x-8533, 256-bit)[31] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 60.71 tok/s at batch 1 rising to 649.62 tok/s aggregate at batch 64 (StorageReview)[31] | $7,312.00 advertised at CDW US against a $7,999.99 list (128 GB, 4 TB, ATAGB10-9000; read Nov 2, 2026)[32] |
| GMKtec EVO-X5 Pro AI Mini PCGMKtec | 192 GB LPDDR5X-8533 onboard (8 x 24 GB, non-upgradeable); up to 160 GB allocatable as VRAM[33] | Up to 273 GB/s[34] | — | GMKtec Laboratory table: GLM-5.3-Flash UD-IQ4_XS (146.05 GB) decode 17.79 tok/s, prefill 70.18, TTFT 14.71 s; Qwen3.8-Flash-Next ROCmFP4-FAST (93.48 GB) decode 45.08 tok/s[33] | $6,799 (192 GB/2 TB) and $7,099 (192 GB/4 TB), GMKtec US store, Nov 2, 2026[33] |
| HP ZGX Nano AI Station (G1n)HP | 128 GB coherent unified system memory[35] | 273 GB/s (128 GB LPDDR5x)[36] | GB10: up to 1 PFLOP FP4, theoretical, using the sparsity feature; HP and reviewers list 1,000 TOPS FP4 (sparse)[23] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.6 tok/s at batch 1 rising to 722.9 tok/s aggregate at batch 64 (StorageReview)[37] | $7,399.00 at the HP Store for the 4 TB model; $4,759 on Amazon (Notebookcheck, review updated Oct 5, 2026)[38] |
| Lenovo ThinkStation PGXLenovo | 128 GB LPDDR5X unified (256-bit)[39] | 273 GB/s[39] | — | — | about $4,100 for the 1 TB configuration (Mar 2026)[40] |
| MSI EdgeXpert (MS-C931)MSI | 64 GB or 128 GB LPDDR5x unified (256-bit)[41] | 273 GB/s[41] | 1 PFLOPS FP4 (sparse)[41] | — | No list price; MSI sells via quote (Get a quote)[41] |
| NVIDIA DGX SparkNVIDIA (partner GB10 systems from Acer, ASUS, Dell, GIGABYTE, HP, Lenovo and MSI) | 128 GB; a 64 GB configuration is sold only through OEM partners[23] | 273 GB/s[23] | Up to 1 PFLOP FP4 (theoretical, using the sparsity feature) (sparse)[23] | Qwen 3.8 27B (dense) with multi-token prediction: decode of about 20 tokens/s, with time-to-first-token staying interactive out to the full 262K context.[42] | $6,950.00 (128 GB, 4 TB) on NVIDIA's enterprise marketplace with an Add To Cart button in a copy cached 07:59 UTC on 2026-10-31; stock unverified (listed out of stock on 2026-10-21); 64 GB partner systems from $4,999[43] |
| NVIDIA DGX Spark 64 GBNVIDIA (sold by Acer, ASUS, Dell, Gigabyte, HP and MSI) | 64 GB LPDDR5X unified (two units pool 128 GB over ConnectX-7)[44] | 273 GB/s (256-bit; NVIDIA spec table covers both 64 GB and 128 GB)[23] | 1 PFLOPS FP4 (sparse; NVIDIA spec table covers both memory configurations)[23] | — | from $4,999 (partner systems, Oct 2026; no Founders Edition)[44] |
| Sipeed MaixStationSipeed | 128 GB LPDDR5X (256-bit)[20] | 273 GB/s (Sipeed claim)[20] | 256 TOPS FP4 (native FP4, no sparsity; Axera/Sipeed claim)[20] | — | about $3,999 expected for 128 GB, with Kickstarter launch discounts (Sipeed to Tom's Hardware, Oct 2026)[20] |
| AMD Ryzen AI Halo Developer PlatformAMD | 128 GB LPDDR5x-8000 unified[45] | 256 GB/s[45] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL 256/256: 222 tok/s aggregate at batch 64 vs 701 on DGX Spark (StorageReview)[46] | $3,999 with 2 TB SSD (Jul 2026)[46] |
| Framework Desktop (Ryzen AI Max+ 395)FrameworkThis story | 128 GB LPDDR5x-8000 soldered (32 GB and 64 GB options)[47] | 256 GB/s[48] | — | gpt-oss-120b MXFP4 in LM Studio (out-of-the-box setup): roughly 45 tok/s (ServeTheHome; Ryzen AI Max+ 395, 128 GB, Windows 11 Pro)[49] | $3,449 (DIY Edition, Max+ 395 with 128 GB, system only; out of stock, Nov 3, 2026)[50] |
| Acer Veriton GN100 AI Mini WorkstationAcer | 128 GB LPDDR5x coherent unified[51] | — | — | gpt-oss-120b, vLLM, total token throughput: prefill heavy 303.61 to 2,777.56 tok/s; decode heavy 38.38 to 292.41 tok/s (batch 1 to 64, StorageReview)[52] | from $3,999 in North America (announced Sep 3, 2025; prices vary by region)[51] |
| ASRock Industrial AI BOX-A395ASRock Industrial | 128 GB LPDDR5X-8000 soldered[53] | — | — | AgentSTH V7, 32 threads: 15% ahead of the next-closest Ryzen AI Max+ 395 box (single-core within 1%); estimated SPEC CPU2026 int rate: top of a 44% spread across four 395 systems; measured by ServeTheHome, Ubuntu 26.04[54] | — |
| Dell Pro Precision with GB300 (model FCT6263; announced as Dell Pro Max with GB300)Dell | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU[55] | — | — | — | $160,195.00 (Dell.com US default config FCT6263 with RTX PRO 2000 display GPU, read Nov 4, 2026); RTX PRO 6000 Workstation Edition option adds $13,560[55] |
| GMKtec EVO-X2 AI Mini PCGMKtec | 64 GB or 128 GB onboard LPDDR5X-8000 (non-upgradeable)[56] | — | — | Llama 3.3 70B Q6_K Instruct: 3.7-3.8 tok/s generation fully on the Radeon 8060S (about 2 tok/s CPU-only); Qwen3-32B 10.4-10.5 tok/s; 128 GB unit, short prompt, tool not named (ServeTheHome)[57] | $3,499.99 (128 GB/1 TB) and $3,649.99 (128 GB/2 TB), each against $3,999.99; $2,199.99 for 64 GB/1 TB (GMKtec US store, read Nov 4, 2026)[56] |
| HP Z2 Mini G1a WorkstationHP | up to 128 GB unified, up to 96 GB assignable to the GPU, up to 8000 MT/s[58] | — | up to 50 NPU TOPS[58] | gpt-oss-120b GGUF (63.39 GB, full GPU offload) in LM Studio: close to 40 tok/s (StorageReview)[59] | $4,781 list for StorageReview's review configuration; about $3,300 street (B&H top spec with 2 TB SSD at $3,342.65, Aug 2025)[59] |
| Microsoft Surface RTX Spark Dev BoxMicrosoft | 128 GB unified memory[60] | — | up to 1 PFLOP of AI compute (Microsoft; precision and sparsity not stated on the page) (sparse)[60] | — | From $5,999.99 (Microsoft Store US, pre-order, read Nov 1, 2026)[60] |
| MSI XpertStation WS300MSI (NVIDIA DGX Station platform) | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU (748 GB coherent)[61] | — | — | StorageReview vLLM: gpt-oss-120b MXFP4 9,294 output tok/s at 128 streams (512/512), 5,038 on 8,192/1,024; MiniMax M3 NVFP4 1,041 at 32 streams with EAGLE3-GQA at a forced acceptance length of 3 (best-case)[61] | $99,999.00 'Start From' at Newegg US (model WS300T60L, 2x 2 TB NVMe RAID1), sold by Newegg as a request-a-quote listing (read Nov 4, 2026)[62] |
| Tenstorrent TT-QuietBox 2 (Blackhole)Tenstorrent | 128 GB GDDR6 on the accelerators + 256 GB DDR5-5600 system memory[63] | — | — | — | $9,999 (Oct 30, 2026)[63] |
| WiCi One (RTX 5060 Ti edition)WiCi | 16 GB GDDR7 VRAM; 1 TB NVMe 4 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[64] | — | — | — | $2,599 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout. Early-access price was $1,999 (Notebookcheck, Engadget, Sep 2026)[64] |
| WiCi One (RTX 5090 edition)WiCi | 32 GB GDDR7 VRAM; 4 TB NVMe 5 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[64] | — | — | — | $9,999 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout[64] |
Italic values are reported by an outlet or measured by an independent lab; the rest come from the maker. Measured speeds use different models, quantizations and tools, so read each with its source rather than against the others. Voltgrid News does not test hardware itself.
Sources (64)
- [1] ASUS
- [2] ASUS
- [3] StorageReview
- [4] Central Computers
- [5] HP
- [6] StorageReview
- [7] HP Japan
- [8] NVIDIA
- [9] StorageReview
- [10] Exxact
- [11] NVIDIA
- [12] NVIDIA
- [13] Apple
- [14] BGR
- [15] MacRumors
- [16] NVIDIA
- [17] ServeTheHome
- [18] StorageReview
- [19] NVIDIA
- [20] Tom's Hardware
- [21] ASUS
- [22] StorageReview
- [23] NVIDIA
- [24] ASUS eShop
- [25] Dell
- [26] HotHardware
- [27] StorageReview
- [28] Framework Blog
- [29] Framework
- [30] GIGABYTE (PR Newswire)
- [31] StorageReview
- [32] CDW
- [33] GMKtec
- [34] GMKtec
- [35] HP
- [36] HotHardware
- [37] StorageReview
- [38] Notebookcheck
- [39] Lenovo PSREF
- [40] ServeTheHome
- [41] MSI
- [42] Tom's Hardware
- [43] NVIDIA Marketplace
- [44] NVIDIA Blog
- [45] AMD
- [46] StorageReview
- [47] Framework
- [48] Framework Blog
- [49] ServeTheHome
- [50] Framework
- [51] Acer
- [52] StorageReview
- [53] ServeTheHome
- [54] ServeTheHome
- [55] Dell
- [56] GMKtec
- [57] ServeTheHome
- [58] HP
- [59] StorageReview
- [60] Microsoft
- [61] StorageReview
- [62] Newegg
- [63] Tenstorrent
- [64] WiCi