DeepSeek V4.1 Flash KV Cache: 1.7 GB at FP8 for 1M Tokens, Rivals 43-73 GB
DeepSeek V4.1 Flash needs 1.7 GB for a 1M-token FP8 cache against 43 to 73 GB for three rivals, by Voltgrid's calculation from published configs; its 510 GB of weights, not the context, decide the machine.
Local AI DeskEdited by Ege Erten
8 min readAI-assisted
Follows our story: DGX Station Alternatives: 4 RTX PRO 6000s Lead Only on MiniMax M3
NVIDIA's DGX Station pairs 252 GB of HBM3e with 496 GB of LPDDR5X, 748 GB of coherent memory, the pool this comparison measures against.
Image: NVIDIA
Source · Press image from the NVIDIA DGX Station product page, used for news reporting.
DeepSeek V4.1 Flash needs 1.7 GB of KV cache for a 1M-token context at FP8, Voltgrid calculates from its published config, against 43.4 GB to 72.5 GB for GLM-5.3, Mistral Large 4 and MiniMax M3.1-Flash.
The key-value (KV) cache is the memory a model keeps for every token it has already read, so it does not have to recompute them. In the format DeepSeek actually uses, 4-bit floating point (FP4) with small scale factors, the figure falls to 890 bytes per token, or 0.93 GB for the full context. That is the number on DeepSeek's Hugging Face model card, and The Next Web reported it when the model launched on Sept. 10. Voltgrid's arithmetic from the config file and DeepSeek's reference inference code lands on the same 890 bytes. Every cache figure in this piece is Voltgrid's calculation from published configs, not a measurement on any machine; the weight sizes are the totals of the published checkpoint files, and prices are as reported.
The cache sits in memory on top of the weights, and it grows with every token of context. At 16-bit precision (BF16), GLM-5.3's cache for a 1M-token context comes to 99.9 GB, more than the 96 GB on one NVIDIA RTX PRO 6000 card before a single weight is loaded. DeepSeek's whole cache in its FP4 format would take under 1% of that card. For DeepSeek V4.1 Flash, the 510.3 GB of published weights, not the context, decide which machine can run it. For the other three, a full context adds tens of gigabytes to an already large model.
How Voltgrid Calculated the Cache
For a model with standard grouped-query attention, the cache per token is layers × 2 (one key and one value) × KV heads × head size × bytes per value. GLM-5.3 and Mistral Large 4 use latent attention instead, which stores one compressed 512-value latent plus a 64-value rotary key per layer. All four models also run a sparse-attention indexer, a small side attention that picks which earlier tokens to read, and its 128-value keys are counted as well. Voltgrid multiplied each per-token figure by 1,048,576 tokens, the maximum position count all four configs list, and counts a gigabyte as 10^9 bytes.
BF16 takes 2 bytes per value and 8-bit floating point (FP8) takes 1; the small per-block scale factors that FP8 formats carry are left out. The figures are for one sequence. They exclude fixed-size sliding-window and draft-model caches, which do not grow with the context, and the activations and overhead of the serving software. Weight sizes are the totals of the checkpoint files each maker posted.
Why DeepSeek V4.1 Flash's Cache Is So Small
DeepSeek V4.1 Flash has 40 layers, but its config names only four of them, layers 2, 8, 14 and 20, as sources for the long-range cache, and the layers that look further back than a short window read from those. Three of the four pool every two tokens into one 512-value latent. The fourth, layer 20, keeps one latent per token, because the config's compression ratio changes there from 2 to 1. The same four layers hold the indexer's 128-value keys. That adds up to 1,600 values per token: 3,200 bytes at BF16, or 3.36 GB for 1M tokens, and 1,600 bytes at FP8, or 1.68 GB.
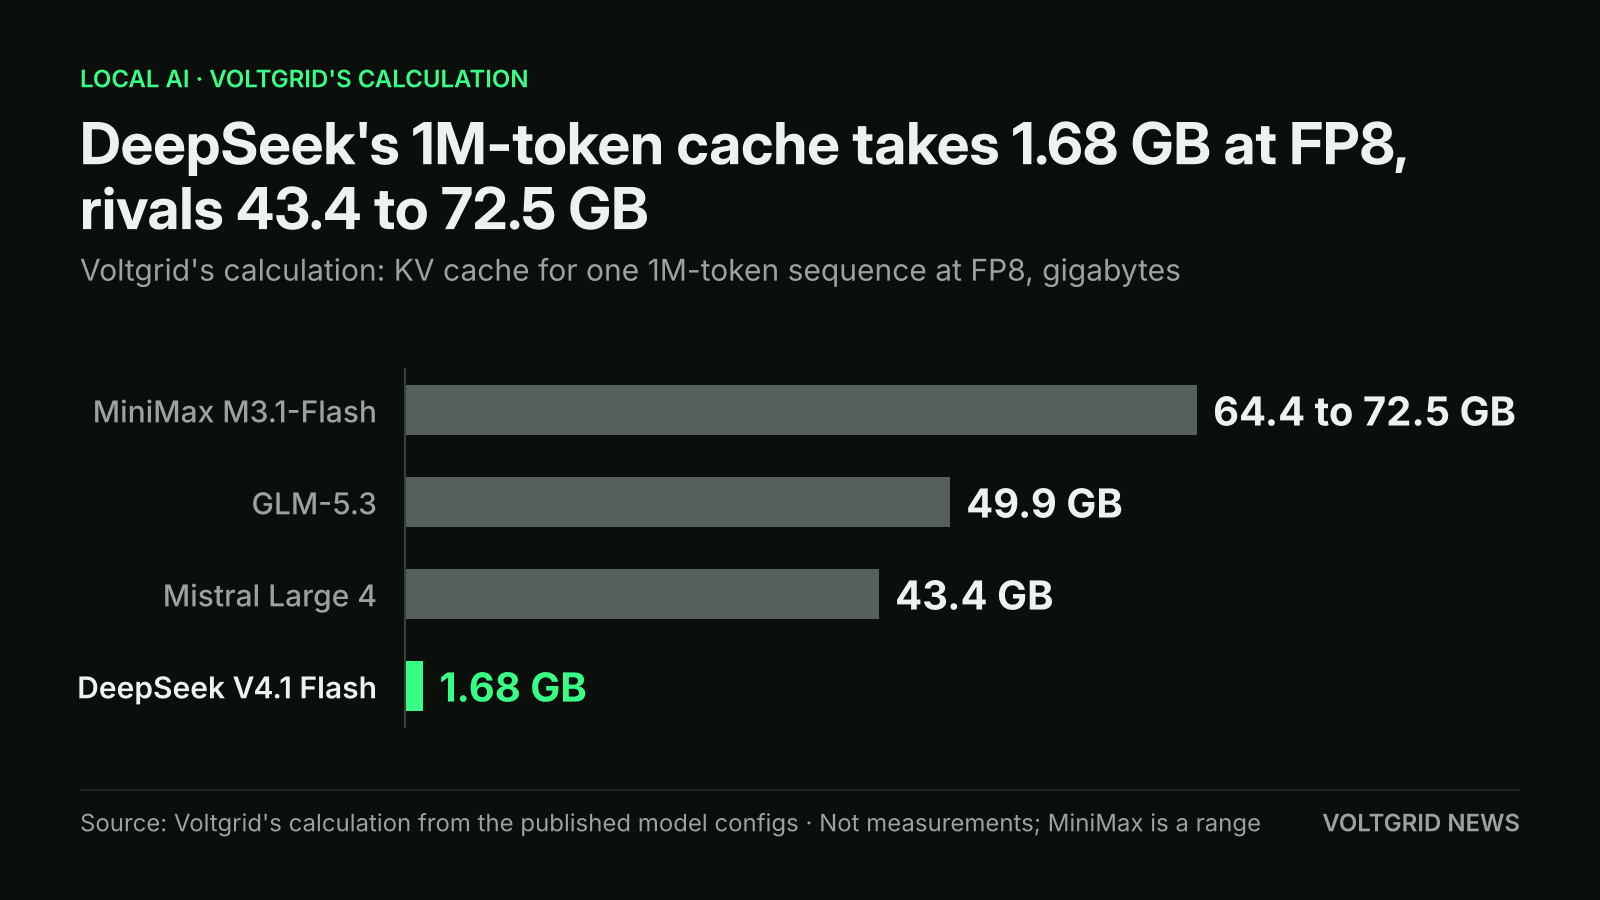
Voltgrid's calculation from the published configs, not a measurement: DeepSeek V4.1 Flash needs 1.68 GB at FP8 where the other three need 43.4 to 72.5 GB.
Illustration (AI-generated)
DeepSeek's reference code quantizes the latents to FP4 with one 8-bit scale per 16 values, and the indexer keys to FP4 with one scale per 32 values. Counting the 4-bit values plus those scales gives 890 bytes per token, the figure on DeepSeek's model card. Every layer also keeps a sliding window of the last 128 tokens, a few megabytes in all that does not grow with the context. DeepSeek's model card puts the result at about a quarter of the cache its predecessor, DeepSeek-V4-Flash, needed.
GLM-5.3, Mistral Large 4 and MiniMax M3.1-Flash at 1M Tokens
Z.ai's GLM-5.3 config lists a 512-value latent plus a 64-value rotary key in each of its 78 layers, which a serving engine that keeps the compressed form caches as 576 values. Only 21 layers carry indexer weights; the config marks the other 57 as sharing. That makes 47,616 values per token: 99.9 GB at BF16 and 49.9 GB at FP8 for 1M tokens. Its one multi-token-prediction layer, used only for speculative decoding, would add about 1.5 GB at BF16 when switched on.
Mistral Large 4 has 72 layers, but its config points nine of them at layer 35's cache instead of their own, so 63 layers write a latent. Nine of those 63 skip rotary position encoding and store 512 values rather than 576. With 44 indexers, the total is 41,344 values per token: 86.7 GB at BF16 and 43.4 GB at FP8. Mistral's own parameter file switches on FP8 for both the KV cache and the indexer, so 43.4 GB is the figure closest to how Mistral ships the model.
MiniMax's M3.1-Flash uses grouped-query attention: 60 layers, each with four KV heads of 128 values, holding a key and a value per head. That is 61,440 values per token, or 128.8 GB at BF16 and 64.4 GB at FP8, the largest of the four. Each layer also computes a 128-value index key for MiniMax Sparse Attention. The published files do not say whether that key is kept for every token or once per 128-token block. If it is kept per token, it adds 16.1 GB at BF16 and 8.1 GB at FP8, for up to 145.0 GB and 72.5 GB.
Which Machines Hold the Weights and the Cache
Weights come first. DeepSeek's checkpoint, FP8 with 4-bit experts, totals 510.3 GB of files. Z.ai's FP8 GLM-5.3 totals 755.6 GB, Mistral's FP8 Large 4 totals 1,060.6 GB and Mistral's own NVFP4 version 610.0 GB, and MiniMax's M3.1-Flash, which mixes 8-bit and 4-bit formats, 252.4 GB. With a 1M-token cache, that comes to 511.2 GB for DeepSeek in its FP4 cache format, and at FP8 to 805.6 GB for GLM-5.3, 653.4 GB for Mistral's NVFP4 checkpoint and 316.8 GB to 324.9 GB for MiniMax.
NVIDIA's DGX Station and the GB300 towers built on it, among them HP's ZGX Fury, Dell's Pro Precision with GB300 and MSI's XpertStation WS300, are the only catalog machines with room for three of the four. The Station's 748 GB of coherent memory, 252 GB of HBM3e on the GPU plus 496 GB of LPDDR5X on the Grace CPU in NVIDIA's spec, holds DeepSeek with more than 230 GB to spare, MiniMax with more than 400 GB, and Mistral Large 4 only as the NVFP4 checkpoint. GLM-5.3's FP8 weights alone, 755.6 GB, are already more than the Station's 748 GB, and with a 1M-token cache they need 805.6 GB. None of the four, with its cache, fits in the 252 GB of fast memory, so part of each model sits in the CPU memory at 396 GB/s. StorageReview found that single-stream speed on large mixture-of-experts models stays modest when experts spill there; Voltgrid's DGX Station review has the labs' single-user figures. The lowest US partner price in the catalog, read on Nov. 4, is Exxact's $98,450.
Apple's Mac Studio with the M5 Ultra and 512 GB of unified memory costs at least $22,299, according to MacRumors. On paper it holds MiniMax M3.1-Flash with a full 1M-token cache even at BF16, at 381.3 GB to 397.4 GB, though Apple does not say how much of the 512 GB the GPU may use. DeepSeek's 511.2 GB is nearly the whole 512 GB, too close to call a fit without a measurement, because macOS and the serving software need memory too. Digital Trends reported that the first 512 GB orders arrive on Dec. 3, while AppleInsider and Guru3D reported on Oct. 29 that Apple's store quoted 10 to 12 weeks, with Guru3D citing an estimated delivery of Jan. 28, 2027. MacStories reported a 256K-token GLM-5.3-Flash run failing out of memory on a 256 GB unit, the configuration Voltgrid's Mac Studio review covers.
Smaller machines hold none of the four published checkpoints. A DGX Spark, listed at $6,950, has 128 GB, and GLM-5.3's BF16 cache alone would take most of it. NVIDIA lists the RTX PRO 6000 at $16,000 for 96 GB.
Four RTX PRO 6000 cards give 384 GB, enough on paper for MiniMax's 324.9 GB with an FP8 cache. That four-card setup led the DGX Station only on the earlier MiniMax M3 in Voltgrid's comparison of DGX Station alternatives, and it has not been measured on M3.1-Flash.
Which to Buy
For DeepSeek V4.1 Flash with its full 1M-token context on one machine, a DGX Station-class GB300 tower is the catalog's only clear fit, and the context costs it about 1 GB in DeepSeek's FP4 cache format, or 1.7 GB at FP8, of its 748 GB. Those towers are also the only single boxes in the catalog that hold Mistral Large 4 with a 1M-token FP8 cache, and only in Mistral's NVFP4 checkpoint.
For MiniMax M3.1-Flash at 1M tokens, the 512 GB Mac Studio is the cheapest single box in the catalog with room on paper, at less than a quarter of the Station's lowest partner price, though its 1.2 TB/s of bandwidth trails the Station's 7.1 TB/s of HBM3e. GLM-5.3 fits no single catalog machine at Z.ai's FP8 precision. Buyers of a DGX Spark or one RTX PRO 6000 should not plan on running any of the four published checkpoints with a full context. WiCi's answer for small machines is to stream DeepSeek V4.1 Flash's weights from an SSD, as Voltgrid reported, on the maker's own benchmark.
These figures are for one user. Every extra 1M-token session adds its cache again, so four MiniMax sessions at FP8 would need 257.7 GB of KV cache, or up to 289.9 GB if the index keys are kept per token, on top of the weights, by the same arithmetic. Community quantizations shrink the weights further. The checkpoint and cache figures here are decimal gigabytes of a billion bytes each. The makers do not say whether their memory figures are decimal or binary gigabytes; if binary, each machine has about 7% more room than shown here, so the margins are nominal. Even then, GLM-5.3 with an FP8 cache, at 805.6 GB, would not fit the Station, whose 748 GB would be about 803 decimal gigabytes. The calculation says whether the bytes fit, not how fast a machine reads them at that length.
How it compares
Full table| Product | Memory | Bandwidth | AI compute | Measured speed | Price |
|---|---|---|---|---|---|
| ASUS ExpertCenter Pro ET900N G3ASUS (NVIDIA DGX Station GB300 platform) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[1] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5X)[1] | up to 20 PFLOPS AI performance (ASUS gives no precision or sparsity label) (sparse)[2] | GPT-OSS-120B MXFP4, vLLM, 512/512, 1-128 streams: 9,280 aggregate output tok/s at 128 streams; 5,023 on 8,192/1,024 (StorageReview, ASUS-supplied unit, no add-in GPU)[3] | $111,999.99 at Central Computers, US (model ET900N G3-2SSD-V2, request a quote, unavailable online, read Nov 4, 2026); no ASUS list price[4] |
| HP ZGX Fury AI StationHP | 252 GB HBM3e GPU + 496 GB LPDDR5x CPU (4x 128 GB SOCAMM); 748 GB unified[5] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5x)[5] | — | Two-unit cluster with an ASUS ET900N G3 over two 400G DACs: GLM-5.3 NVFP4 5,018 output tok/s at 256 streams, 512/512, vLLM 0.27.1 TP2 with MTP (StorageReview); no single-unit HP result[6] | Japan list price from 28,490,000 yen incl. tax (sales from Oct 27, 2026); no US list price published[7] |
| NVIDIA DGX StationNVIDIA (systems built by ASUS, Dell, GIGABYTE, HP, MSI, Supermicro and Exxact) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[8] | GPU HBM3e 7.1 TB/s; CPU LPDDR5X 396 GB/s; NVLink-C2C 900 GB/s between them[8] | 15 PFLOPS FP4 (without sparsity)[8] | gpt-oss-120b MXFP4, stock vLLM, 512/512 chat workload: 9,280 output tok/s at 128 streams (5,023 on 8,192/1,024 prompts), single GB300 (StorageReview, ASUS ExpertCenter Pro ET900N G3)[9] | No NVIDIA list price; lowest US partner listing read Nov 4, 2026: Exxact Valence VWS-158270643 from $98,450 (Tom's Hardware found $94,930 in Aug); Dell Pro Precision with GB300 lists $160,195[10] |
| NVIDIA RTX PRO 6000 Blackwell Workstation EditionNVIDIA (sold through PNY, TD SYNNEX and workstation makers) | 96 GB[11] | 1,792 GB/s[11] | 4,000 AI TOPS (FP4, with sparsity) (sparse)[11] | gpt-oss-120b MXFP4, stock vLLM, 512/512 chat workload: 3,064 output tok/s at 128 streams (1,169 on 8,192/1,024 prompts); Server Edition at 600W (StorageReview)[9] | $16,000 on NVIDIA's US marketplace (Workstation Edition), listed out of stock[12] |
| Apple Mac Studio (M5 Ultra)Apple | up to 512 GB unified (96 GB on 30-core M5 Ultra; 256 GB or 512 GB on 36-core/80-core M5 Ultra)[13] | 1.2 TB/s[13] | — | Qwen 3.8 27B 4-bit MLX in LM Studio: about 55 tok/s on M5 Ultra (36-core, 256 GB) vs about 40 on M3 Ultra (BGR)[14] | $22,299 minimum with 512 GB ($6,799 36-core CPU/80-core GPU M5 Ultra config plus $15,500 memory upgrade; Oct 28, 2026)[15] |
| NVIDIA RTX Spark (N1X) PCsNVIDIA (MediaTek collaborated on the custom CPU design) | Up to 128 GB LPDDR5X (20-core CPU / 6,144-core GPU version); up to 64 GB (18-core / 5,120-core laptop version)[16] | Up to 300 GB/s: LPDDR5X-9400 on a 256-bit bus (NVIDIA's product page lists no bandwidth)[17] | — | gpt-oss:20b via Ollama in a Codex CLI coding agent, 64K context: 58.5 tok/s generation, 3 of 4 tasks passed (Dell XPS 16, 20-core N1X, 64 GB; StorageReview)[18] | Laptops from $2,599; pricing and configurations vary by region[19] |
| AMD Ryzen AI Halo (Ryzen AI Max+ PRO 495, 192 GB)AMD | 192 GB LPDDR5X (256-bit)[20] | 273 GB/s[20] | — | — | $7,299.99 for the Linux version (released the week of Oct 12, 2026); Windows version coming soon[20] |
| ASUS Ascent GX10ASUS | 64 GB or 128 GB LPDDR5X-8533 unified[21] | 273 GB/s (8533 MT/s), as listed by StorageReview; ASUS's spec page states no bandwidth[22] | Up to 1 PFLOP FP4 (GB10; NVIDIA's footnote: theoretical, using the sparsity feature). ASUS's pages say 1 petaFLOP / FP4 with no sparsity label (sparse)[23] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 70 tok/s at batch 1 rising to 680 tok/s aggregate at batch 64 (StorageReview)[22] | $5,999 (128 GB, 1 TB, GX10-GG0010BN, ASUS eShop US, Oct 30, 2026)[24] |
| Dell Pro Precision with GB10 (model FCM1253; launched as Dell Pro Max with GB10)Dell | 128 GB LPDDR5x up to 8533 MT/s onboard (64 GB option also listed)[25] | 273 GB/s (128 GB LPDDR5x, 256-bit)[26] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 68.57 tok/s at batch 1 rising to 670.83 tok/s aggregate at batch 64 (StorageReview)[27] | $7,967 (128 GB, 2 TB Gen4 QLC SSD default config, Dell.com US, read Nov 2, 2026 16:40 UTC)[25] |
| Framework Desktop (Ryzen AI Max+ PRO 495, 192 GB)Framework | 192 GB LPDDR5X-8533 soldered[28] | 273 GB/s (256-bit)[28] | — | — | $6,799 (Max+ PRO 495 192 GB DIY Edition pre-order, Nov 3, 2026; storage not included)[29] |
| GIGABYTE AI TOP ATOMGIGABYTE | 128 GB unified system memory[30] | 273 GB/s (LPDDR5x-8533, 256-bit)[31] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 60.71 tok/s at batch 1 rising to 649.62 tok/s aggregate at batch 64 (StorageReview)[31] | $7,312.00 advertised at CDW US against a $7,999.99 list (128 GB, 4 TB, ATAGB10-9000; read Nov 2, 2026)[32] |
| GMKtec EVO-X5 Pro AI Mini PCGMKtec | 192 GB LPDDR5X-8533 onboard (8 x 24 GB, non-upgradeable); up to 160 GB allocatable as VRAM[33] | Up to 273 GB/s[34] | — | GMKtec Laboratory table: GLM-5.3-Flash UD-IQ4_XS (146.05 GB) decode 17.79 tok/s, prefill 70.18, TTFT 14.71 s; Qwen3.8-Flash-Next ROCmFP4-FAST (93.48 GB) decode 45.08 tok/s[33] | $6,799 (192 GB/2 TB) and $7,099 (192 GB/4 TB), GMKtec US store, Nov 2, 2026[33] |
| HP ZGX Nano AI Station (G1n)HP | 128 GB coherent unified system memory[35] | 273 GB/s (128 GB LPDDR5x)[36] | GB10: up to 1 PFLOP FP4, theoretical, using the sparsity feature; HP and reviewers list 1,000 TOPS FP4 (sparse)[23] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.6 tok/s at batch 1 rising to 722.9 tok/s aggregate at batch 64 (StorageReview)[37] | $7,399.00 at the HP Store for the 4 TB model; $4,759 on Amazon (Notebookcheck, review updated Oct 5, 2026)[38] |
| Lenovo ThinkStation PGXLenovo | 128 GB LPDDR5X unified (256-bit)[39] | 273 GB/s[39] | — | — | about $4,100 for the 1 TB configuration (Mar 2026)[40] |
| MSI EdgeXpert (MS-C931)MSI | 64 GB or 128 GB LPDDR5x unified (256-bit)[41] | 273 GB/s[41] | 1 PFLOPS FP4 (sparse)[41] | — | No list price; MSI sells via quote (Get a quote)[41] |
| NVIDIA DGX SparkNVIDIA (partner GB10 systems from Acer, ASUS, Dell, GIGABYTE, HP, Lenovo and MSI) | 128 GB; a 64 GB configuration is sold only through OEM partners[23] | 273 GB/s[23] | Up to 1 PFLOP FP4 (theoretical, using the sparsity feature) (sparse)[23] | Qwen 3.8 27B (dense) with multi-token prediction: decode of about 20 tokens/s, with time-to-first-token staying interactive out to the full 262K context.[42] | $6,950.00 (128 GB, 4 TB) on NVIDIA's enterprise marketplace with an Add To Cart button in a copy cached 07:59 UTC on 2026-10-31; stock unverified (listed out of stock on 2026-10-21); 64 GB partner systems from $4,999[43] |
| NVIDIA DGX Spark 64 GBNVIDIA (sold by Acer, ASUS, Dell, Gigabyte, HP and MSI) | 64 GB LPDDR5X unified (two units pool 128 GB over ConnectX-7)[44] | 273 GB/s (256-bit; NVIDIA spec table covers both 64 GB and 128 GB)[23] | 1 PFLOPS FP4 (sparse; NVIDIA spec table covers both memory configurations)[23] | — | from $4,999 (partner systems, Oct 2026; no Founders Edition)[44] |
| Sipeed MaixStationSipeed | 128 GB LPDDR5X (256-bit)[20] | 273 GB/s (Sipeed claim)[20] | 256 TOPS FP4 (native FP4, no sparsity; Axera/Sipeed claim)[20] | — | about $3,999 expected for 128 GB, with Kickstarter launch discounts (Sipeed to Tom's Hardware, Oct 2026)[20] |
| AMD Ryzen AI Halo Developer PlatformAMD | 128 GB LPDDR5x-8000 unified[45] | 256 GB/s[45] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL 256/256: 222 tok/s aggregate at batch 64 vs 701 on DGX Spark (StorageReview)[46] | $3,999 with 2 TB SSD (Jul 2026)[46] |
| Framework Desktop (Ryzen AI Max+ 395)Framework | 128 GB LPDDR5x-8000 soldered (32 GB and 64 GB options)[47] | 256 GB/s[48] | — | gpt-oss-120b MXFP4 in LM Studio (out-of-the-box setup): roughly 45 tok/s (ServeTheHome; Ryzen AI Max+ 395, 128 GB, Windows 11 Pro)[49] | $3,449 (DIY Edition, Max+ 395 with 128 GB, system only; out of stock, Nov 3, 2026)[50] |
| Acer Veriton GN100 AI Mini WorkstationAcer | 128 GB LPDDR5x coherent unified[51] | — | — | gpt-oss-120b, vLLM, total token throughput: prefill heavy 303.61 to 2,777.56 tok/s; decode heavy 38.38 to 292.41 tok/s (batch 1 to 64, StorageReview)[52] | from $3,999 in North America (announced Sep 3, 2025; prices vary by region)[51] |
| ASRock Industrial AI BOX-A395ASRock Industrial | 128 GB LPDDR5X-8000 soldered[53] | — | — | AgentSTH V7, 32 threads: 15% ahead of the next-closest Ryzen AI Max+ 395 box (single-core within 1%); estimated SPEC CPU2026 int rate: top of a 44% spread across four 395 systems; measured by ServeTheHome, Ubuntu 26.04[54] | — |
| Dell Pro Precision with GB300 (model FCT6263; announced as Dell Pro Max with GB300)Dell | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU[55] | — | — | — | $160,195.00 (Dell.com US default config FCT6263 with RTX PRO 2000 display GPU, read Nov 4, 2026); RTX PRO 6000 Workstation Edition option adds $13,560[55] |
| GMKtec EVO-X2 AI Mini PCGMKtec | 64 GB or 128 GB onboard LPDDR5X-8000 (non-upgradeable)[56] | — | — | Llama 3.3 70B Q6_K Instruct: 3.7-3.8 tok/s generation fully on the Radeon 8060S (about 2 tok/s CPU-only); Qwen3-32B 10.4-10.5 tok/s; 128 GB unit, short prompt, tool not named (ServeTheHome)[57] | $3,499.99 (128 GB/1 TB) and $3,649.99 (128 GB/2 TB), each against $3,999.99; $2,199.99 for 64 GB/1 TB (GMKtec US store, read Nov 4, 2026)[56] |
| HP Z2 Mini G1a WorkstationHP | up to 128 GB unified, up to 96 GB assignable to the GPU, up to 8000 MT/s[58] | — | up to 50 NPU TOPS[58] | gpt-oss-120b GGUF (63.39 GB, full GPU offload) in LM Studio: close to 40 tok/s (StorageReview)[59] | $4,781 list for StorageReview's review configuration; about $3,300 street (B&H top spec with 2 TB SSD at $3,342.65, Aug 2025)[59] |
| Microsoft Surface RTX Spark Dev BoxMicrosoft | 128 GB unified memory[60] | — | up to 1 PFLOP of AI compute (Microsoft; precision and sparsity not stated on the page) (sparse)[60] | — | From $5,999.99 (Microsoft Store US, pre-order, read Nov 1, 2026)[60] |
| MSI XpertStation WS300MSI (NVIDIA DGX Station platform) | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU (748 GB coherent)[61] | — | — | StorageReview vLLM: gpt-oss-120b MXFP4 9,294 output tok/s at 128 streams (512/512), 5,038 on 8,192/1,024; MiniMax M3 NVFP4 1,041 at 32 streams with EAGLE3-GQA at a forced acceptance length of 3 (best-case)[61] | $99,999.00 'Start From' at Newegg US (model WS300T60L, 2x 2 TB NVMe RAID1), sold by Newegg as a request-a-quote listing (read Nov 4, 2026)[62] |
| Tenstorrent TT-QuietBox 2 (Blackhole)Tenstorrent | 128 GB GDDR6 on the accelerators + 256 GB DDR5-5600 system memory[63] | — | — | — | $9,999 (Oct 30, 2026)[63] |
| WiCi One (RTX 5060 Ti edition)WiCi | 16 GB GDDR7 VRAM; 1 TB NVMe 4 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[64] | — | — | — | $2,599 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout. Early-access price was $1,999 (Notebookcheck, Engadget, Sep 2026)[64] |
| WiCi One (RTX 5090 edition)WiCi | 32 GB GDDR7 VRAM; 4 TB NVMe 5 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[64] | — | — | — | $9,999 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout[64] |
Italic values are reported by an outlet or measured by an independent lab; the rest come from the maker. Measured speeds use different models, quantizations and tools, so read each with its source rather than against the others. Voltgrid News does not test hardware itself.
Sources (64)
- [1] ASUS
- [2] ASUS
- [3] StorageReview
- [4] Central Computers
- [5] HP
- [6] StorageReview
- [7] HP Japan
- [8] NVIDIA
- [9] StorageReview
- [10] Exxact
- [11] NVIDIA
- [12] NVIDIA
- [13] Apple
- [14] BGR
- [15] MacRumors
- [16] NVIDIA
- [17] ServeTheHome
- [18] StorageReview
- [19] NVIDIA
- [20] Tom's Hardware
- [21] ASUS
- [22] StorageReview
- [23] NVIDIA
- [24] ASUS eShop
- [25] Dell
- [26] HotHardware
- [27] StorageReview
- [28] Framework Blog
- [29] Framework
- [30] GIGABYTE (PR Newswire)
- [31] StorageReview
- [32] CDW
- [33] GMKtec
- [34] GMKtec
- [35] HP
- [36] HotHardware
- [37] StorageReview
- [38] Notebookcheck
- [39] Lenovo PSREF
- [40] ServeTheHome
- [41] MSI
- [42] Tom's Hardware
- [43] NVIDIA Marketplace
- [44] NVIDIA Blog
- [45] AMD
- [46] StorageReview
- [47] Framework
- [48] Framework Blog
- [49] ServeTheHome
- [50] Framework
- [51] Acer
- [52] StorageReview
- [53] ServeTheHome
- [54] ServeTheHome
- [55] Dell
- [56] GMKtec
- [57] ServeTheHome
- [58] HP
- [59] StorageReview
- [60] Microsoft
- [61] StorageReview
- [62] Newegg
- [63] Tenstorrent
- [64] WiCi
Sources
- 01Mistral Large 4 (1T-A52B) model card and configMistral AI (Hugging Face) · huggingface.co
- 02DeepSeek launches V4.1-Flash and retires V4-Pro, its flagship modelThe Next Web · thenextweb.com
- 03Mistral Large 4 NVFP4 checkpointMistral AI (Hugging Face) · huggingface.co
- 04MiniMax-M3.1-Flash model card and configMiniMax (Hugging Face) · huggingface.co
- 05GLM-5.3 model card and configZ.ai (Hugging Face) · huggingface.co
- 06DeepSeek-V4.1-Flash model cardDeepSeek (Hugging Face) · huggingface.co