Strix Halo Linux vs Windows: Ubuntu 26.10 1.16x Faster on GMKtec EVO-X2
Phoronix's Nov. 19 tests of the 128GB GMKtec Strix Halo mini PC put Linux ahead in 26 of 32 llama.cpp results, including every prompt-processing run; Windows 11 Pro led only Vulkan generation on six models.
4 min read
Follows GMKtec EVO-X2 Review: 128GB Strix Halo Now $3,499.99, Up From $1,999
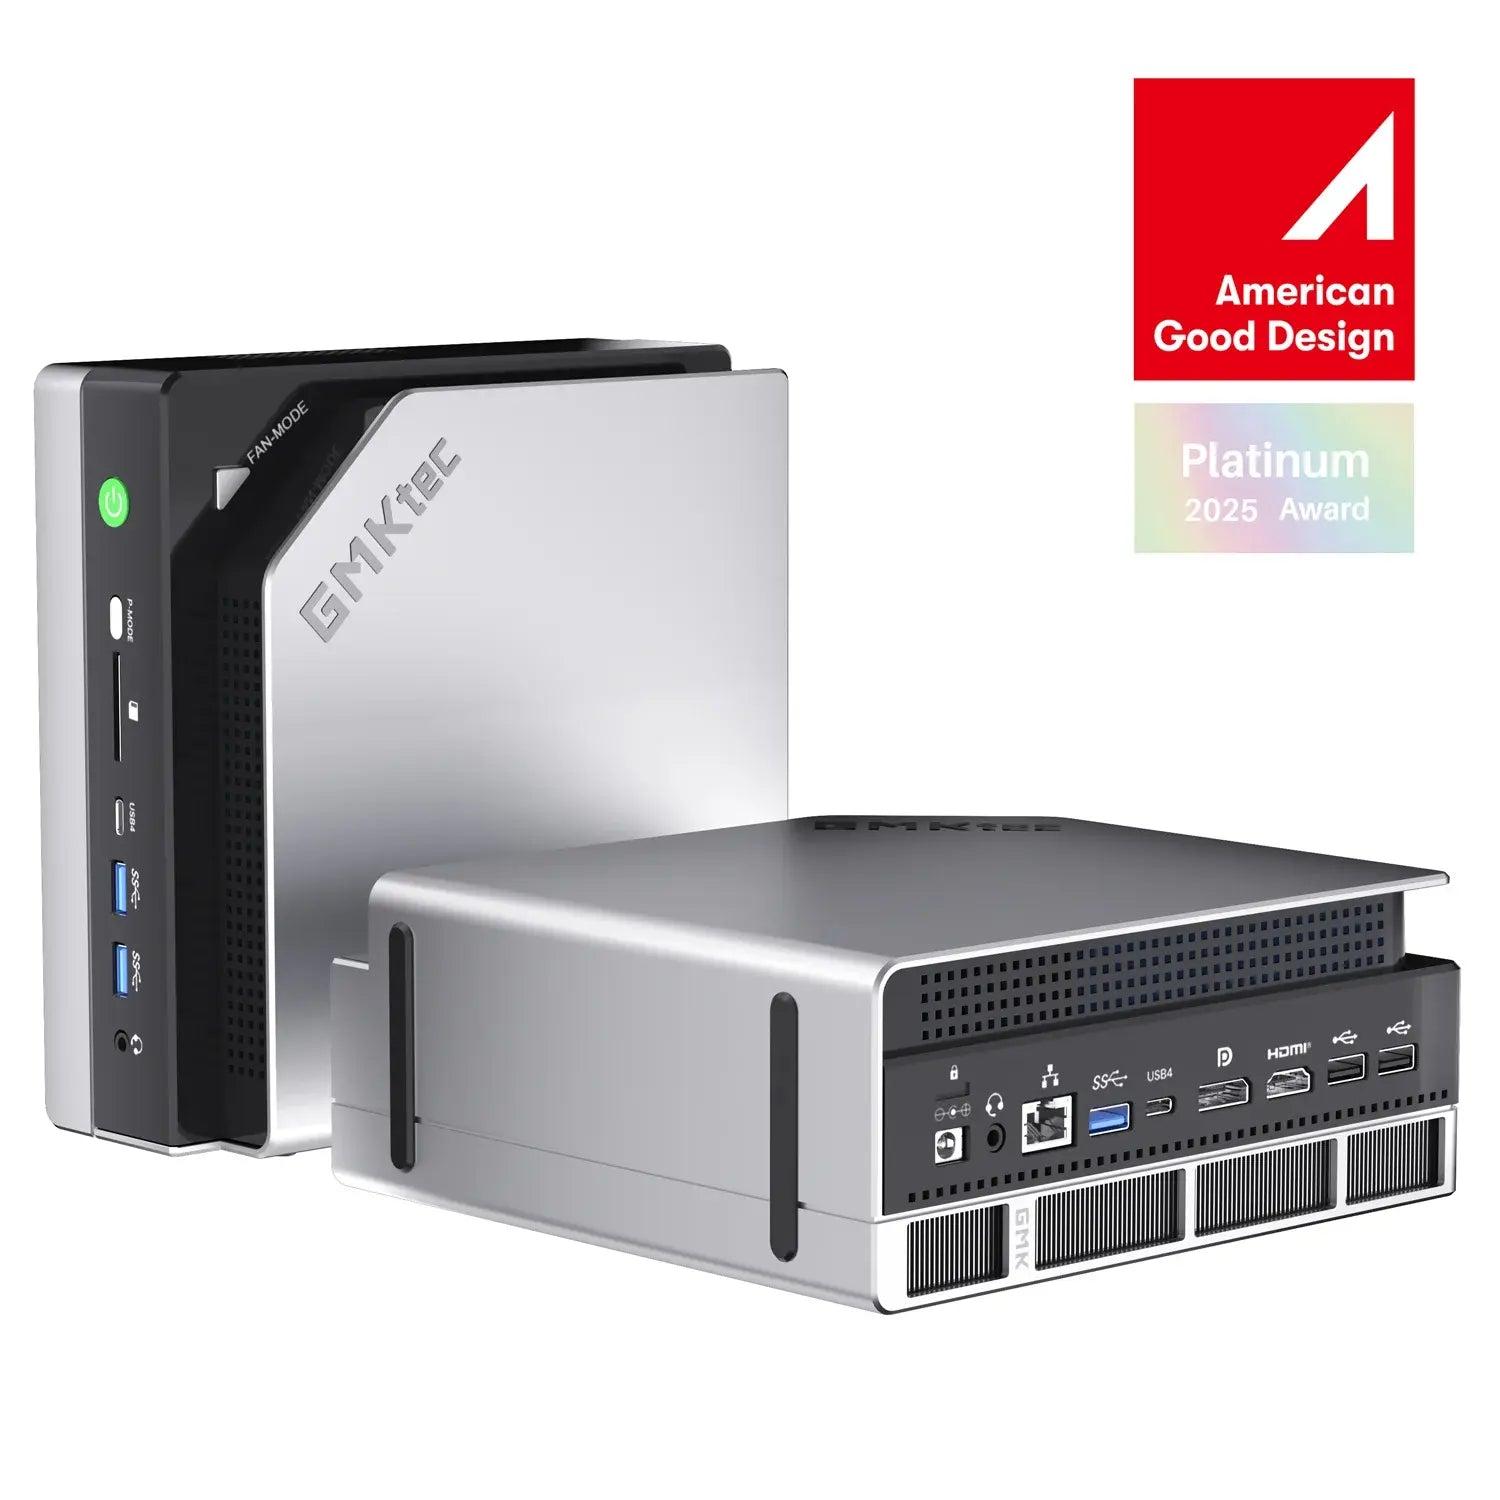
The GMKtec EVO-X2 with the Ryzen AI Max+ 395, the machine Phoronix tested.
Image: GMKtec
Source · Product image from the GMKtec product page, used for news reporting.
On the Ryzen AI Max+ 395 "Strix Halo" in a 128GB GMKtec EVO-X2, Ubuntu 26.10 delivered 1.16 times the performance of Windows 11 Pro by geometric mean across more than one hundred benchmarks spanning games, creator applications and AI, according to Phoronix results published on Nov. 19, 2026.
Phoronix founder Michael Larabel ran the comparison on a review sample with AMD's Ryzen AI Max+ 395 (Strix Halo), Radeon 8060S graphics, 128GB of LPDDR5-8000 memory as Phoronix labels it (GMKtec's spec page lists LPDDR5X-8000) and a 2TB XG401 NVMe SSD. Windows 11 Pro was tested as GMKtec ships it, and both systems carried every update available as of Nov. 16. The workloads ran from games and creator applications to AI inference. GMKtec's own store page markets the EVO-X2 as a Windows 11 AI+ PC, so the pre-installed system trailed Ubuntu overall in this test, although Windows still led six llama.cpp Vulkan generation charts. Phoronix gives no cause.
Strix Halo llama.cpp Results: Linux Led Prompt Processing
The AI results come from llama.cpp, run on eight models with two backends, Vulkan on the Radeon 8060S and CPU BLAS on the processor's CPU cores (AMD lists 16 Zen 5 cores and 32 threads for the chip; Phoronix does not say how many threads llama.cpp used), and two tests: prompt processing of 2,048 tokens and generation of 128 tokens. That makes 32 results. Ubuntu was faster in 26 of them and Windows in six. This story reports which system led each chart, not the speeds behind it.
Prompt processing is the phase in which the model reads the whole input before it writes its first token, so it decides how long a long document, a codebase or a chat history takes to load. Ubuntu led all 16 prompt-processing results, on both backends and on every model: Qwen3.5-9B, gpt-oss-20b, Llama-3.1-Tulu-3-8B, Mistral-7B-Instruct-v0.3, DeepSeek-R1-Distill-Llama-8B and granite-3.0-3b-a800m, all at Q8_0, plus GLM-4.7-Flash at IQ4_XS and MiniMax-M2.5 at UD-TQ1_0.
Token generation, the speed at which an answer appears, split by backend. On the CPU, Ubuntu led all eight models. On Vulkan, Windows was faster on the six Q8_0 models, while Ubuntu was faster on GLM-4.7-Flash and MiniMax-M2.5, the two models run at lower-bit quantizations. Because those are different models as well as different quantizations (IQ4_XS and UD-TQ1_0), the results cannot separate the effect of quantization from the model itself. Phoronix summed it up the same way: Linux dominated CPU inference, the Vulkan results were much closer, and Ubuntu was usually ahead there too.
Ubuntu led 26 of 32 llama.cpp charts in Phoronix's Nov. 19 tests; Windows led six Vulkan generation charts.
Graphic: Voltgrid News
Why Prompt Speed and Generation Speed Can Split
Prompt processing and generation lean on different parts of the chip. Prefill reads the whole prompt at once and is limited by compute. Decode writes one token at a time and re-reads the model's weights for each, so memory bandwidth limits it. AMD rates the Radeon 8060S at up to 60 TFLOPS of FP16 AI compute, and Framework states 256 GB/s of memory bandwidth for its Desktop with the same chip.
With different bottlenecks, different drivers and software paths can lead each phase. Phoronix reported which system led each llama.cpp chart, not why, so Ubuntu's sweep of prompt processing and Windows' six Vulkan generation wins are measured outcomes, not a diagnosis.
What the Gap Means for an EVO-X2 Buyer
The Windows wins fell in one corner of the chart: Vulkan generation on the six Q8_0 models, by name gpt-oss-20b, Qwen3.5-9B, Llama-3.1-Tulu-3-8B, DeepSeek-R1-Distill-Llama-8B, Mistral-7B-Instruct-v0.3 and granite-3.0-3b-a800m. GMKtec says the 128GB version runs models as large as Qwen3 235B, and on prompt processing, the step that grows with input length, Linux led on every model Phoronix ran. Phoronix did not test a ROCm or HIP backend, gpt-oss-120b or a 70B-class dense model. Our EVO-X2 review covered ServeTheHome's Llama 3.3 70B run, in which it measured 3.7 to 3.8 tok/s generating at Q6_K on the Radeon 8060S in a July 2025 review that does not name its inference tool; that is a different model, quantization and software era from Phoronix's charts and is not comparable to them.
Running Linux tools inside Windows is not a clean way around the gap for ROCm users either. AMD's ROCm 10.2 release notes of Nov. 18 warn that AI jobs under WSL2 can stop with an illegal memory access error on Ryzen APUs, Strix Halo included, as Voltgrid reported on Nov. 19. AMD's workaround is to stay on ROCm 10.1.0. Phoronix tested native Ubuntu, not WSL2.
GMKtec's US store listed the 128GB/1TB model at $3,499.99 and the 128GB/2TB model at $3,649.99 on Nov. 22, each against a $3,999.99 compare-at price, with the 64GB/1TB version at $2,199.99, all in stock. The page also warns of a price increase without giving a date.
What Phoronix Has Not Measured Yet
This is one lab's result on one machine. Phoronix tested only the GMKtec unit, so whether the same gap shows up on other Ryzen AI Max+ 395 systems such as the Framework Desktop or the HP Z2 Mini G1a is unmeasured. The next things to watch are a Windows-against-Linux run on the ROCm backend with gpt-oss-120b or a 70B-class model, and whether GMKtec's $3,499.99 price for the 128GB model holds.
How it compares
Full table| Product | Memory | Bandwidth | AI compute | Measured speed | Price |
|---|---|---|---|---|---|
| ASUS ExpertCenter Pro ET900N G3ASUS (NVIDIA DGX Station GB300 platform) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[1] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5X)[1] | up to 20 PFLOPS AI performance (ASUS gives no precision or sparsity label) (sparse)[2] | GPT-OSS-120B MXFP4, vLLM, 512/512, 1-128 streams: 9,280 aggregate output tok/s at 128 streams; 5,023 on 8,192/1,024 (StorageReview, ASUS-supplied unit, no add-in GPU)[3] | $111,999.99 at Central Computers, US (ET900N G3-2SSD-V2, read Nov 8, 2026); no ASUS list price[4] |
| HP ZGX Fury AI StationHP | 252 GB HBM3e GPU + 496 GB LPDDR5x CPU (4x 128 GB SOCAMM); 748 GB unified[5] | 7.1 TB/s (GPU HBM3e); 396 GB/s (CPU LPDDR5x)[5] | up to 20 petaFLOPS FP4 (HP gives no sparsity label) (sparse)[5] | Two-unit cluster with an ASUS ET900N G3 over two 400G DACs: GLM-5.3 NVFP4 5,018 output tok/s at 256 streams, 512/512, vLLM 0.27.1 TP2 with MTP (StorageReview); no single-unit HP result[6] | $132,000.00 on HP Store US (ZGX Fury G1n, 3-yr warranty, no graphics card, 4x 2 TB SED SSDs; Add to cart; read Nov 11, 2026)[7] |
| MSI XpertStation WS300MSI (NVIDIA DGX Station platform) | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU (748 GB coherent)[8] | 7.1 TB/s (GPU HBM3e); 396 GB/s CPU LPDDR5X[8] | — | StorageReview vLLM: gpt-oss-120b MXFP4 9,294 output tok/s at 128 streams (512/512), 5,038 on 8,192/1,024; MiniMax M3 NVFP4 1,041 at 32 streams with EAGLE3-GQA at a forced acceptance length of 3 (best-case)[8] | $99,999.00 'Start From' at Newegg US (model WS300T60L, 2x 2 TB NVMe RAID1), request-a-quote listing sold by Newegg (read Nov 15, 2026)[9] |
| NVIDIA DGX StationNVIDIA (systems built by ASUS, Dell, GIGABYTE, HP, MSI, Supermicro and Exxact) | 748 GB coherent: 252 GB HBM3e (GPU) + 496 GB LPDDR5X (CPU)[10] | GPU HBM3e 7.1 TB/s; CPU LPDDR5X 396 GB/s; NVLink-C2C 900 GB/s between them[10] | 15 PFLOPS FP4 (without sparsity)[10] | gpt-oss-120b MXFP4, vLLM, 512/512 chat workload: 9,280 output tok/s at 128 streams (MSI WS300 9,294), single GB300 (StorageReview, ASUS ExpertCenter Pro ET900N G3)[3] | No NVIDIA list price; lowest US partner listing read Nov 4, 2026: Exxact Valence VWS-158270643 from $98,450 (Tom's Hardware found $94,930 in Aug); Dell Pro Precision with GB300 lists $160,195[11] |
| Supermicro Super AI Station (ARS-511GD-NB-LCC)Supermicro (NVIDIA DGX Station platform) | 748 GB total coherent: 252 GB HBM3e GPU + 496 GB LPDDR5X system[12] | 7.1 TB/s (GPU HBM3E); 396 GB/s (CPU LPDDR5X)[13] | up to 20 PFLOPS FP4 (Supermicro gives no sparsity label; ServeTheHome describes it as sparse FP4)[12] | Qwen3.8 Flash Next NVFP4, vLLM, tool-loop 4,096-in/512-out: several scenarios exceeded 3,000 output tok/s at 32 concurrent users, still rising (ServeTheHome; RTX PRO 2000 installed)[14] | $92,887.47 before tax and shipping on Supermicro's online store (ARS-511GD-NB-LCC-01-G2); about $90,101.05 with a 3% new-customer discount (TechRadar, Sep 1, 2026)[15] |
| NVIDIA RTX PRO 6000 Blackwell Workstation EditionNVIDIA (sold through PNY, TD SYNNEX and workstation makers) | 96 GB[16] | 1,792 GB/s[16] | 4,000 AI TOPS (FP4, with sparsity) (sparse)[16] | gpt-oss-120b MXFP4, stock vLLM, 512/512 chat workload: 3,064 output tok/s at 128 streams (1,169 on 8,192/1,024 prompts); Server Edition at 600W (StorageReview)[17] | $16,000 on NVIDIA's US marketplace (Workstation Edition), listed out of stock[18] |
| Apple Mac Studio (M5 Ultra)Apple | up to 512 GB unified (96 GB on 30-core M5 Ultra; 256 GB or 512 GB on 36-core/80-core M5 Ultra)[19] | 1.2 TB/s[19] | — | GLM-5.3-Flash MLX 4-bit with MTP on TensorFold, ISL 2048/OSL 512: 94.0 tok/s at 0 context, 96.5 at 128K, 79.4 at 512K; TTFT 1.1 s at 0, 66.3 s at 128K (Tom's Hardware, 256 GB M5 Ultra)[20] | $22,299 minimum with 512 GB ($6,799 36-core CPU/80-core GPU M5 Ultra config plus $15,500 memory upgrade; Oct 28, 2026)[21] |
| Corsair FlexPrime V20C Workstation (CSW-9040004-NA)Corsair | 32 GB GDDR6 on the Arc Pro B70 GPU + 32 GB (2x 16 GB) DDR5 system memory[22] | 608 GB/s (GPU GDDR6)[22] | — | Qwen3.8 27B Q4_K_M, llama.cpp server: 19.8 tok/s at 1 request, 33.5 at 4, 35.4 at 8; TTFT 9,005 ms on 8,192-token prompt (StorageReview)[23] | $3,999.99 on Corsair US store (32 GB DDR5, 1 TB SSD; read Nov 15, 2026)[22] |
Show the other 35 machinesHide the other 35 machines
| Product | Memory | Bandwidth | AI compute | Measured speed | Price |
|---|---|---|---|---|---|
| ASUS ProArt GR1XASUS | 64 GB or up to 128 GB LPDDR5X unified memory (ASUS spec page, read Nov 18, 2026)[24] | 300 GB/s (ASUS spec page, read Nov 18, 2026)[24] | WITHDRAWN, not a sparse figure: ASUS and NVIDIA say 'up to 1 petaFLOP FP4' with no sparse or dense label; no field asserts either[25] | Qwen3.8 27B Q4_K_M, llama.cpp CUDA, Windows 11: 13.1 tok/s output at 1 request, 31.4 at 4, 40.0 at 8 requests; TTFT 8.6 s (StorageReview, 64 GB unit, sr-client 1.13)[26] | $4,499 (64 GB, 1 TB Gen4, Windows 11 Home) at ASUS eShop US; $4,499.99 at Best Buy, which lists 64 GB/2 TB at $4,999.99 (StorageReview, Nov 18, 2026)[26] |
| Mechrevo Master Road X10Mechrevo | 64 GB (with 1 TB SSD) or 128 GB (with 2 TB SSD) unified memory[27] | 300 GB/s (unified memory)[27] | up to 1 PFLOP FP4 (sparse)[27] | — | CNY 32,999 (64 GB/1 TB) to CNY 49,999 (128 GB/2 TB), China only[27] |
| NVIDIA RTX Spark (N1X) PCsNVIDIA (MediaTek collaborated on the custom CPU design) | Up to 128 GB LPDDR5X (20-core CPU / 6,144-core GPU version); up to 64 GB (18-core / 5,120-core laptop version)[25] | Up to 300 GB/s: LPDDR5X-9400 on a 256-bit bus (NVIDIA's product page lists no bandwidth)[28] | — | gpt-oss:20b via Ollama in a Codex CLI coding agent, 64K context: 58.5 tok/s generation, 3 of 4 tasks passed (Dell XPS 16, 20-core N1X, 64 GB; StorageReview)[29] | Laptops from $2,599; pricing and configurations vary by region[30] |
| AMD Ryzen AI Halo (Ryzen AI Max+ PRO 495, 192 GB)AMD | 192 GB LPDDR5X (256-bit)[31] | 273 GB/s[31] | — | — | $7,299.99 for the Linux version (released the week of Oct 12, 2026); Windows version coming soon[31] |
| ASUS Ascent GX10ASUS | 64 GB or 128 GB LPDDR5X-8533 unified[32] | 273 GB/s (8533 MT/s), as listed by StorageReview; ASUS's spec page states no bandwidth[33] | Up to 1 PFLOP FP4 (GB10; NVIDIA's footnote: theoretical, using the sparsity feature). ASUS's pages say 1 petaFLOP / FP4 with no sparsity label (sparse)[34] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 70 tok/s at batch 1 rising to 680 tok/s aggregate at batch 64 (StorageReview)[33] | $5,999 (128 GB, 1 TB, GX10-GG0010BN, ASUS eShop US, Oct 30, 2026)[35] |
| Dell Pro Precision with GB10 (model FCM1253; launched as Dell Pro Max with GB10)Dell | 128 GB LPDDR5x up to 8533 MT/s onboard (64 GB option also listed)[36] | 273 GB/s (128 GB LPDDR5x, 256-bit)[37] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 68.57 tok/s at batch 1 rising to 670.83 tok/s aggregate at batch 64 (StorageReview)[38] | $7,901.00 (default FCM1253, 128 GB, 2 TB Gen4 QLC) on Dell.com US, unchanged; 64 GB memory option listed at -$2,150.00, 4 TB TLC SED SSD +$2,450.00 (read Nov 20, 2026)[39] |
| Framework Desktop (Ryzen AI Max+ PRO 495, 192 GB)Framework | 192 GB LPDDR5X-8533 soldered[40] | 273 GB/s (256-bit)[40] | — | — | $6,799 (Max+ PRO 495 192 GB DIY Edition pre-order, Nov 3, 2026; storage not included)[41] |
| GIGABYTE AI TOP ATOMGIGABYTE | 128 GB unified system memory[42] | 273 GB/s (LPDDR5x-8533, 256-bit)[43] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 60.71 tok/s at batch 1 rising to 649.62 tok/s aggregate at batch 64 (StorageReview)[43] | $7,499.99 (128 GB, 4 TB PCIe 4.0) and $9,405.63 (128 GB, 4 TB PCIe 5.0; more options from $7,999.99); 128 GB from $5,999.99 (1 TB) and $6,999.99 (2 TB) at Newegg US, read Nov 9, 2026[44] |
| GMKtec EVO-X5 Pro AI Mini PCGMKtec | 192 GB LPDDR5X-8533 onboard (8 x 24 GB, non-upgradeable); up to 160 GB allocatable as VRAM[45] | Up to 273 GB/s[46] | — | GMKtec Laboratory table: GLM-5.3-Flash UD-IQ4_XS (146.05 GB) decode 17.79 tok/s, prefill 70.18, TTFT 14.71 s; Qwen3.8-Flash-Next ROCmFP4-FAST (93.48 GB) decode 45.08 tok/s[45] | $6,799 (192 GB/2 TB) and $7,099 (192 GB/4 TB), all variants available, GMKtec US store, read Nov 9, 2026[45] |
| HP ZGX Nano AI Station (G1n)HP | 128 GB coherent unified system memory[47] | 273 GB/s (128 GB LPDDR5x)[48] | GB10: up to 1 PFLOP FP4, theoretical, using the sparsity feature; HP and reviewers list 1,000 TOPS FP4 (sparse)[34] | gpt-oss-120b, vLLM online serving, equal ISL/OSL: 69.6 tok/s at batch 1 rising to 722.9 tok/s aggregate at batch 64 (StorageReview)[49] | $7,399.00 at the HP Store for the 4 TB model; $4,759 on Amazon (Notebookcheck, review updated Oct 5, 2026)[50] |
| Lenovo ThinkStation PGXLenovo | 128 GB LPDDR5X unified (256-bit)[51] | 273 GB/s[51] | Up to 1 PFLOP FP4 (Lenovo PSREF gives no sparsity label; XDA says NVIDIA's figure assumes structured sparsity) (sparse)[51] | Qwen3-Coder-Next FP8 (FP8 KV cache), vLLM NGC container, one request at a time, 170K context: 25-40 tok/s (XDA Developers, Lenovo-loaned unit)[52] | US from $5,079 (1 TB base model) on Lenovo's site, per TechRadar's review (Jun 9, 2026); UK from GBP 5,200[53] |
| MSI EdgeMesa N AI+ (128 GB, X-005US)MSI | 128 GB LPDDR5X unified system memory[54] | 273 GB/s[54] | — | Qwen3.8 27B Q4_K_M, llama.cpp CUDA, Windows 11: 13.0 tok/s output at 1 request, 31.1 at 4, 39.8 at 8 requests (StorageReview, 128 GB unit, default 62.5 GB GPU allocation)[55] | $7,499.00 (128 GB, 4 TB, X-005US, MSI US store, out of stock, read Nov 21, 2026)[54] |
| MSI EdgeXpert (MS-C931)MSI | 64 GB or 128 GB LPDDR5x unified (256-bit)[56] | 273 GB/s[56] | 1 PFLOPS FP4 (sparse)[56] | — | No list price; MSI sells via quote (Get a quote)[56] |
| NVIDIA DGX SparkNVIDIA (partner GB10 systems from Acer, ASUS, Dell, GIGABYTE, HP, Lenovo and MSI) | 128 GB; a 64 GB configuration is sold only through OEM partners[34] | 273 GB/s[34] | Up to 1 PFLOP FP4 (theoretical, using the sparsity feature) (sparse)[34] | Qwen 3.8 27B (dense) with multi-token prediction: decode of about 20 tokens/s, with time-to-first-token staying interactive out to the full 262K context.[57] | $6,950.00 (128 GB, 4 TB) on NVIDIA's enterprise marketplace with an Add To Cart button in a copy cached 07:59 UTC on 2026-10-31; stock unverified (listed out of stock on 2026-10-21); 64 GB partner systems from $4,999[58] |
| NVIDIA DGX Spark 64 GBNVIDIA (sold by Acer, ASUS, Dell, Gigabyte, HP and MSI) | 64 GB LPDDR5X unified (two units pool 128 GB over ConnectX-7)[59] | 273 GB/s (256-bit; NVIDIA spec table covers both 64 GB and 128 GB)[34] | 1 PFLOPS FP4 (sparse; NVIDIA spec table covers both memory configurations)[34] | — | from $4,999 (partner systems, Oct 2026; no Founders Edition)[59] |
| Sipeed MaixStationSipeed | 128 GB LPDDR5X (256-bit)[31] | 273 GB/s (Sipeed claim)[31] | 256 TOPS FP4 (native FP4, no sparsity; Axera/Sipeed claim)[31] | — | about $3,999 expected for 128 GB, with Kickstarter launch discounts (Sipeed to Tom's Hardware, Oct 2026)[31] |
| AMD Ryzen AI Halo Developer PlatformAMD | 128 GB LPDDR5x-8000 unified[60] | 256 GB/s[60] | — | gpt-oss-120b, vLLM online serving, equal ISL/OSL 256/256: 222 tok/s aggregate at batch 64 vs 701 on DGX Spark (StorageReview)[61] | $3,999 with 2 TB SSD (Jul 2026)[61] |
| Framework Desktop (Ryzen AI Max+ 395)Framework | 128 GB LPDDR5x-8000 soldered (32 GB and 64 GB options)[62] | 256 GB/s[63] | — | gpt-oss-120b MXFP4 in LM Studio (out-of-the-box setup): roughly 45 tok/s (ServeTheHome; Ryzen AI Max+ 395, 128 GB, Windows 11 Pro)[64] | $3,449 (DIY Edition, Max+ 395 with 128 GB, system only; out of stock, Nov 3, 2026)[65] |
| Acer Veriton GN100 AI Mini WorkstationAcer | 128 GB LPDDR5x coherent unified[66] | — | — | gpt-oss-120b, vLLM, total token throughput: prefill heavy 303.61 to 2,777.56 tok/s; decode heavy 38.38 to 292.41 tok/s (batch 1 to 64, StorageReview)[67] | from $3,999 in North America (announced Sep 3, 2025; prices vary by region)[66] |
| ASRock Industrial AI BOX-A395ASRock Industrial | 128 GB LPDDR5X-8000 soldered[68] | — | — | AgentSTH V7, 32 threads: 15% ahead of the next-closest Ryzen AI Max+ 395 box (single-core within 1%); estimated SPEC CPU2026 int rate: top of a 44% spread across four 395 systems; measured by ServeTheHome, Ubuntu 26.04[69] | — |
| Beelink GTR9 Pro (Ryzen AI Max+ 495, 128 GB)Beelink | 128 GB LPDDR5X-8533 unified (soldered)[70] | — | 132 AI TOPS on Beelink's page; AMD lists the PRO 495 at Overall TOPS up to 132 and NPU TOPS up to 55; no precision stated by either[70] | 4.24 tok/s, LM Studio, Qwen3.8-35B-A3B (Beelink's own figure on its store page; quantization, context, backend and RAM size not stated)[70] | $4,799 (128 GB/2 TB), Beelink store, pre-order (read Nov 13, 2026)[70] |
| Beelink GTR9 Pro (Ryzen AI Max+ 495, 192 GB)Beelink | 192 GB LPDDR5X-8533 unified (soldered)[70] | — | 132 AI TOPS on Beelink's page; AMD lists the PRO 495 at Overall TOPS up to 132 and NPU TOPS up to 55; no precision stated by either[70] | 4.24 tok/s, LM Studio, Qwen3.8-35B-A3B (Beelink's own figure on its store page; quantization, context, backend and RAM size not stated)[70] | $7,399 (192 GB/2 TB) or $7,799 (192 GB/4 TB), Beelink store, pre-order (read Nov 13, 2026)[70] |
| Bosgame M5 MAX AI Mini PCBosgame | 192 GB unified LPDDR5 (soldered); up to 160 GB allocatable to the GPU[71] | — | — | — | $6,199 introductory first-batch pre-order price (192 GB, 2 TB PCIe 4.0 SSD), from Nov 3, 2026, until the first allocation sells out[71] |
| Dell Creator Edition Desktop (DM1273)Dell | 128 GB LPDDR5X unified[72] | — | WITHDRAWN, not a sparse figure: NVIDIA's RTX Spark page says 'up to 1 petaflop FP4' and its Nov 18 desktop post 'up to 1 petaflop of AI performance'; neither says sparse or dense[25] | — | $7,590.00 Dell Price (128 GB, 2 TB Gen4 QLC, Windows 11 Pro default config; Dell.com US, read Nov 22, 2026)[72] |
| Dell Pro Max Micro (FCM2250)Dell | 24 GB GDDR7 on the RTX PRO 4000 SFF (23.9 GB usable measured) + 96 GB DDR5-6400 CSODIMM system RAM in StorageReview's tested build[73] | — | — | Ministral 3 8B, llama.cpp server (CUDA), 4,096-in/1,024-out: 52.0 tok/s at 1 request, 108.9 at 4; TTFT 1,477 ms (StorageReview, RTX PRO 4000 SFF 24 GB, driver 595.99.02, Ubuntu 26.04.1)[73] | From $1,449.00 on Dell.com US; RTX PRO 4000 SFF 24 GB option +$3,870.00 (read Nov 16, 2026)[74] |
| Dell Pro Precision 9 T4Dell | Up to 2x 96 GB GDDR7 (two RTX PRO 6000 Max-Q) + up to 4 TB DDR5 RDIMM in 16 slots, 8 channels[75] | — | — | MiniMax M2.7 Q4_K_M (129.3 GB) split across 2x RTX PRO 6000 Max-Q: 83.7 tok/s one user, 127.3 peak; 30.3 on one card plus system RAM (StorageReview, llama.cpp b11716, Ubuntu 26.04.1)[75] | From $5,925.00 on Dell.com US; dual RTX PRO 6000 Max-Q option +$30,820.00 (read Nov 14, 2026). StorageReview's tested build (Xeon 698X, 256 GB, 2x Max-Q) about $66,600[76] |
| Dell Pro Precision with GB300 (model FCT6263; announced as Dell Pro Max with GB300)Dell | 252 GB HBM3e GPU + 496 GB LPDDR5X CPU[77] | — | — | — | $160,195.00 (Dell.com US default config FCT6263, read Nov 8, 2026)[77] |
| Gigabyte AI TOP Aero | up to 128 GB LPDDR5X unified[78] | — | — | — | — |
| GMKtec EVO-X2 AI Mini PCGMKtec | 64 GB or 128 GB onboard LPDDR5X-8000 (non-upgradeable)[79] | — | — | Llama 3.3 70B Q6_K Instruct: 3.7-3.8 tok/s generation fully on the Radeon 8060S (about 2 tok/s CPU-only); Qwen3-32B 10.4-10.5 tok/s; 128 GB unit, short prompt, tool not named (ServeTheHome)[80] | $3,499.99 (128 GB/1 TB) and $3,649.99 (128 GB/2 TB), each against $3,999.99 compare-at; 64 GB/1 TB $2,199.99 against $2,599.99 (GMKtec US store, read Nov 22, 2026)[79] |
| HP Z2 Mini G1a WorkstationHP | up to 128 GB unified, up to 96 GB assignable to the GPU, up to 8000 MT/s[81] | — | up to 50 NPU TOPS[81] | gpt-oss-120b GGUF (63.39 GB, full GPU offload) in LM Studio: close to 40 tok/s (StorageReview)[82] | $4,781 list for StorageReview's review configuration; about $3,300 street (B&H top spec with 2 TB SSD at $3,342.65, Aug 2025)[82] |
| Microsoft Surface RTX Spark Dev BoxMicrosoft | 128 GB unified memory[83] | — | up to 1 PFLOP of AI compute (Microsoft; precision and sparsity not stated on the page) (sparse)[83] | — | From $5,999.99 (Microsoft Store US, pre-order, read Nov 1, 2026)[83] |
| MSI EdgeMesa N AI+ (64 GB) | — | — | — | — | $4,399 (64 GB / 1 TB, after MSI's cut from $4,699; Nov 2026)[84] |
| Tenstorrent TT-QuietBox 2 (Blackhole)Tenstorrent | 128 GB GDDR6 on the accelerators + 256 GB DDR5-5600 system memory[85] | — | — | — | $9,999 (Oct 30, 2026)[85] |
| WiCi One (RTX 5060 Ti edition)WiCi | 16 GB GDDR7 VRAM; 1 TB NVMe 4 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[86] | — | — | — | $2,599 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout. Early-access price was $1,999 (Notebookcheck, Engadget, Sep 2026)[86] |
| WiCi One (RTX 5090 edition)WiCi | 32 GB GDDR7 VRAM; 4 TB NVMe 5 SSD for TurboStream weight paging (WiCi's claim: NVMe used as working VRAM). System RAM not stated[86] | — | — | — | $9,999 list (WiCi shop, Oct 2026); a $600-off code (WICIWELCOME) is applied at checkout[86] |
Italic values are reported by an outlet or measured by an independent lab; the rest come from the maker. Measured speeds use different models, quantizations and tools, so read each with its source rather than against the others. Voltgrid News does not test hardware itself.
Sources (86)
- [1] ASUS
- [2] ASUS
- [3] StorageReview
- [4] Central Computers
- [5] HP
- [6] StorageReview
- [7] HP
- [8] StorageReview
- [9] Newegg
- [10] NVIDIA
- [11] Exxact
- [12] Supermicro
- [13] ServeTheHome
- [14] ServeTheHome
- [15] TechRadar
- [16] NVIDIA
- [17] StorageReview
- [18] NVIDIA
- [19] Apple
- [20] Tom's Hardware
- [21] MacRumors
- [22] Corsair
- [23] StorageReview
- [24] ASUS
- [25] NVIDIA
- [26] StorageReview
- [27] Notebookcheck
- [28] ServeTheHome
- [29] StorageReview
- [30] NVIDIA
- [31] Tom's Hardware
- [32] ASUS
- [33] StorageReview
- [34] NVIDIA
- [35] ASUS eShop
- [36] Dell
- [37] HotHardware
- [38] StorageReview
- [39] Dell
- [40] Framework Blog
- [41] Framework
- [42] GIGABYTE (PR Newswire)
- [43] StorageReview
- [44] Newegg
- [45] GMKtec
- [46] GMKtec
- [47] HP
- [48] HotHardware
- [49] StorageReview
- [50] Notebookcheck
- [51] Lenovo PSREF
- [52] XDA Developers
- [53] TechRadar
- [54] MSI
- [55] StorageReview
- [56] MSI
- [57] Tom's Hardware
- [58] NVIDIA Marketplace
- [59] NVIDIA Blog
- [60] AMD
- [61] StorageReview
- [62] Framework
- [63] Framework Blog
- [64] ServeTheHome
- [65] Framework
- [66] Acer
- [67] StorageReview
- [68] ServeTheHome
- [69] ServeTheHome
- [70] Beelink
- [71] Notebookcheck
- [72] Dell
- [73] StorageReview
- [74] Dell
- [75] StorageReview
- [76] Dell
- [77] Dell
- [78] Notebookcheck
- [79] GMKtec
- [80] ServeTheHome
- [81] HP
- [82] StorageReview
- [83] Microsoft
- [84] Notebookcheck
- [85] Tenstorrent
- [86] WiCi
Sources
- Desk
- Local AI Desk
- Published
- Sources
- 2 cited